<?xml version="1.0" encoding="utf-8"?>

<feed xmlns="http://www.w3.org/2005/Atom">
<title>FID Recht - Recht und Technik</title>
<generator uri="http://tt-rss.org/">Tiny Tiny RSS/23.04-0578bf802 (Unsupported)</generator>
<updated>2026-02-13T19:49:16+00:00</updated>
<id>https://vifa-recht.de/feed/19</id>
<link href="https://vifa-recht.de/feed/19" rel="self"/>

<link href="https://vifa-recht.de" rel="alternate"/>

<entry>
	<id>tag:vifa-recht.de,2026-10-23:/302196</id>
	<link href="https://www.gautrais.com/presse/ia-que-fait-reellement-linstitut-mila/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=ia-que-fait-reellement-linstitut-mila" rel="alternate" type="text/html"/>
	<title type="html">IA&amp;#160;: que fait réellement l’institut Mila ? (Quartier Libre, 15 octobre 2026)</title>
	<summary type="html"><![CDATA[<p>Situ&eacute; &agrave; Montr&eacute;al, l&rsquo;Institut qu&eacute;b&eacute;cois d&rsquo;intelligence artificielle Mila est le plus grand centre de ...</p>]]></summary>
	<content type="html"><![CDATA[<p><strong><a href="https://quartierlibre.ca/luniversite-champions-recherche-ia/" target="_blank" rel="noopener noreferrer">Situ&eacute; &agrave; Montr&eacute;al</a>, l&rsquo;Institut qu&eacute;b&eacute;cois d&rsquo;intelligence artificielle Mila est le plus grand centre de recherche universitaire en apprentissage profond au monde. Malgr&eacute; son statut, le r&ocirc;le qu&rsquo;il assume dans l&rsquo;industrie de l&rsquo;intelligence artificielle (IA) demeure peu connu du public.</strong> <strong><em>Quartier Libre</em></strong> <strong>s&rsquo;est donc pench&eacute; sur son positionnement dans ce secteur en constante &eacute;volution.</strong></p>
<h4><a href="https://quartierlibre.ca/ia-que-fait-linstitut-mila/" rel="noopener noreferrer" target="_blank">Pour en savoir +</a></h4>]]></content>
	<updated>2026-10-15T15:09:21+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-10-15T15:09:21+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-10-15:/301320</id>
	<link href="https://law.stanford.edu/2026/10/15/above-the-crossing-the-general-counsel-as-trust-architect/" rel="alternate" type="text/html"/>
	<title type="html">Above the Crossing: The General Counsel as Trust Architect</title>
	<summary type="html"><![CDATA[<p>Imagine standing in the middle of Shibuya Crossing. People approach from several directions. Your ...</p>]]></summary>
	<content type="html"><![CDATA[<article>
<header></header>
<p>Imagine standing in the middle of Shibuya Crossing. People approach from several directions. Your immediate concern is the next movement: someone coming toward you, a narrowing gap, a path opening to your left.</p>
<p>Now imagine observing the crossing from above. Entrances, destinations, and points of convergence become visible. You can begin to understand how individual movements relate to the surrounding structure.</p>
<p>I keep returning to this image when thinking about the general counsel&rsquo;s role. A contract question, a product review, a customer complaint, and a board inquiry can arrive as four separate demands. Each has a deadline and someone waiting for an answer.</p>
<p>Consider a hypothetical company whose AI supplier changes how customer data is handled. That change could affect an assurance in a contract, a product configuration, a customer response, and the accuracy of a governance report. The four demands share a dependency.</p>
<p>Recognizing that connection creates a different set of questions. Which promises depend on the supplier&rsquo;s behavior? Who can verify what changed? Who can act? How will the next change reach the right people?</p>
<p>This is where I see an opportunity for the GC to help build trust architecture.</p>
<h2>Making alignment durable</h2>
<p>Eric Dodson Greenberg&rsquo;s writing offers a useful starting point. He argues that AI-driven organizational speed makes alignment a central GC function. His earlier work on enterprise strategy and the profession&rsquo;s AI transition also emphasizes legal&rsquo;s cross-functional reach and architectural contribution.<sup>[<a href="https://vifa-recht.de#fn1" aria-label="Footnote 1" rel="noopener noreferrer" target="_blank">1</a>, <a href="https://vifa-recht.de#fn2" aria-label="Footnote 2" rel="noopener noreferrer" target="_blank">2</a>, <a href="https://vifa-recht.de#fn3" aria-label="Footnote 3" rel="noopener noreferrer" target="_blank">3</a>]</sup></p>
<p>I want to develop the institutional mechanics of that argument. Once people have aligned around a decision, where do its assumptions, authority, and limits live? What keeps the decision connected to changing conditions? Who can reopen it?</p>
<p>My earlier working paper, <em>The CLO as Trust Architect</em>, examines structural parallels across approximately 2,000 commercial agreements, qualitative litigation-workflow research, and an academic pilot of an AI-supported legal reasoning tool. The recurring concerns include verifiability, responsibility, procedural design, and the preservation of human judgment.<sup>[<a href="https://vifa-recht.de#fn4" aria-label="Footnote 4" rel="noopener noreferrer" target="_blank">4</a>]</sup></p>
<p>Those research streams have different limitations. Contract language reveals what parties wrote; performance requires separate evidence. Interviews offer situated accounts. A law-student pilot requires further study before its findings can be generalized to corporate counsel. The theory developed here introduces no new analysis of those datasets.<sup>[<a href="https://vifa-recht.de#fn4" aria-label="Footnote 4" rel="noopener noreferrer" target="_blank">4</a>]</sup></p>
<p>I call the proposed approach <strong>commitment-linked trust architecture</strong>: maintained connections among a consequential commitment, the capability needed to honor it, supporting evidence, decision authority, channels for challenge, and mechanisms for correction. Existing governance traditions supply many of these practices. The focus here is their connection across legal and operational domains.</p>
<h2>The value of a wider view</h2>
<p>Organizational research helps explain why the observer&rsquo;s position matters. Jay Galbraith connects task uncertainty with organizational information-processing demands. Ronald Burt studies the value of connections across otherwise separated groups. Karl Weick, Kathleen Sutcliffe, and David Obstfeld examine how organizations turn circumstances into interpretations that inform action.<sup>[<a href="https://vifa-recht.de#fn5" aria-label="Footnote 5" rel="noopener noreferrer" target="_blank">5</a>, <a href="https://vifa-recht.de#fn6" aria-label="Footnote 6" rel="noopener noreferrer" target="_blank">6</a>, <a href="https://vifa-recht.de#fn7" aria-label="Footnote 7" rel="noopener noreferrer" target="_blank">7</a>]</sup></p>
<p>Together, these ideas suggest a conditional advantage for legal leaders. A GC who can connect materially different perspectives may identify a dependency that remains difficult to see within one function. An engineer understands a configuration. Sales understands a customer&rsquo;s expectations. Legal sees the commitment connecting them.</p>
<p>That advantage requires access and interpretive discipline. A full calendar can contain repeated versions of the same incomplete account. Legal&rsquo;s escalations also provide a selected view of the enterprise. Routine successes and unreported failures may be missing.</p>
<p>Research by Robert Nelson and Laura Beth Nielsen documents variation in how inside counsel construct their roles. Deborah DeMott examines the GC&rsquo;s multiple responsibilities and the tensions they can create. A title alone tells us little about information access, influence, or professional independence.<sup>[<a href="https://vifa-recht.de#fn8" aria-label="Footnote 8" rel="noopener noreferrer" target="_blank">8</a>, <a href="https://vifa-recht.de#fn9" aria-label="Footnote 9" rel="noopener noreferrer" target="_blank">9</a>]</sup></p>
<p>Changing altitude therefore includes returning to the people doing the work and asking what the enterprise-level account leaves out.</p>
<h2>What complexity research contributes</h2>
<p>Edward Lorenz&rsquo;s work on deterministic nonperiodic flow showed how a system governed by specified equations can be highly sensitive to initial conditions. Small differences can grow, limiting long-range prediction from finite-precision observations. Understanding rules and predicting a trajectory are separate achievements.<sup>[<a href="https://vifa-recht.de#fn10" aria-label="Footnote 10" rel="noopener noreferrer" target="_blank">10</a>]</sup></p>
<p>For legal leadership, I draw a bounded lesson: discovering a dependency can improve a decision while substantial uncertainty remains. A company may map its reliance on a supplier and still be unable to anticipate the supplier&rsquo;s next consequential change.</p>
<p>James Crutchfield&rsquo;s work on structure and randomness, including his research with Cosma Shalizi on computational mechanics, adds a question about representation. What features of an observed process are worth retaining to understand its behavior? The choice depends on the process and the analytical task.<sup>[<a href="https://vifa-recht.de#fn11" aria-label="Footnote 11" rel="noopener noreferrer" target="_blank">11</a>, <a href="https://vifa-recht.de#fn12" aria-label="Footnote 12" rel="noopener noreferrer" target="_blank">12</a>]</sup></p>
<p>In a legal department, categorizing matters by subject can help assign expertise. Grouping them by a shared operational dependency can help identify a recurring source of difficulty. Each representation serves a purpose.</p>
<p>Claude Shannon&rsquo;s information theory gives precise mathematical treatments of information and communication. Applying its measures to organizational governance would require defined variables, probability distributions, and validation. Here it prompts a simpler design question: what information must survive a handoff for the next person to make a responsible decision?<sup>[<a href="https://vifa-recht.de#fn13" aria-label="Footnote 13" rel="noopener noreferrer" target="_blank">13</a>]</sup></p>
<p>W. Ross Ashby&rsquo;s work on regulatory variety and Herbert Simon&rsquo;s analysis of complex, nearly decomposable systems direct attention to response capacity and the relationships among subsystems. My organizational inference is to examine how bounded local discretion can coexist with coordinated responses to shared dependencies.<sup>[<a href="https://vifa-recht.de#fn14" aria-label="Footnote 14" rel="noopener noreferrer" target="_blank">14</a>, <a href="https://vifa-recht.de#fn15" aria-label="Footnote 15" rel="noopener noreferrer" target="_blank">15</a>]</sup></p>
<p>These are carefully limited connections across disciplines. Establishing mathematical chaos in an enterprise would require a specified model and evidence. The crossing metaphor helps us ask about partial observation; it supplies no proof that a company has one discoverable underlying order.</p>
<h2>Follow a promise into the operating system</h2>
<p>Trust scholarship makes the objective more precise. Mayer, Davis, and Schoorman connect trust with willingness to accept vulnerability. Onora O&rsquo;Neill emphasizes the evidence needed to place trust intelligently. A governance design should give people sound reasons for reliance.<sup>[<a href="https://vifa-recht.de#fn16" aria-label="Footnote 16" rel="noopener noreferrer" target="_blank">16</a>, <a href="https://vifa-recht.de#fn17" aria-label="Footnote 17" rel="noopener noreferrer" target="_blank">17</a>]</sup></p>
<p>Return to the hypothetical assurance about customer data. Start with the precise commitment and its scope: which data, which uses, which service, and which period? Include obligations imposed by law alongside the company&rsquo;s chosen promises.</p>
<p>Then identify the capability supporting the assurance. That may include a supplier restriction, a technical setting, access permissions, and a named operating owner. Connect those capabilities to evidence that an authorized person can inspect, including when it was collected and what it actually establishes.</p>
<p>Next, specify authority. Who may approve an ordinary use? Which change requires additional review? Who decides while a material fact remains unresolved? Give a concern somewhere to go, and give the recipient a usable way to pause, investigate, repair, or revise the activity.</p>
<p>Research on contracting for innovation by Ronald Gilson, Charles Sabel, and Robert Scott explores contractual arrangements that support collaboration under uncertainty. George Triantis examines modularity and innovation in contract design. Those traditions provide grounding for treating contractual arrangements as part of an evolving governance relationship.<sup>[<a href="https://vifa-recht.de#fn18" aria-label="Footnote 18" rel="noopener noreferrer" target="_blank">18</a>, <a href="https://vifa-recht.de#fn19" aria-label="Footnote 19" rel="noopener noreferrer" target="_blank">19</a>]</sup></p>
<p>In the architecture proposed here, technical owners retain responsibility for capability, legal interprets obligations, and authorized business leaders exercise commercial discretion within applicable limits. Elinor Ostrom&rsquo;s work on polycentric governance supports taking multiple decision centers and their coordination seriously. Its application to this corporate setting is a design proposal to test.<sup>[<a href="https://vifa-recht.de#fn20" aria-label="Footnote 20" rel="noopener noreferrer" target="_blank">20</a>]</sup></p>
<p>A challenge channel also needs social credibility. Amy Edmondson&rsquo;s research associates team psychological safety with learning behavior. A person who identifies a mismatch between a promise and actual practice needs a credible recipient, a response, and protection appropriate to the context.<sup>[<a href="https://vifa-recht.de#fn21" aria-label="Footnote 21" rel="noopener noreferrer" target="_blank">21</a>]</sup></p>
<p>The architecture lives in these connections. Its performance becomes visible when a change reaches the people who can reconsider affected commitments and act on them.</p>
<h2>A legal-informatics opportunity</h2>
<p>For legal technologists, this suggests a useful object to model: the relationship between a commitment and the conditions supporting it.</p>
<p>A prototype could connect the wording of an assurance to relevant capabilities, evidence records, decision owners, unresolved challenges, and correction actions. Dates, versions, scope, and provenance would matter. A supplier change could identify commitments requiring review. A reviewer could see which evidence applies and which assumptions remain uncertain.</p>
<p>This is a proposed representation. Its value would depend on the quality of the links and what people can do with them. An extracted clause needs validation. A reference to an audit report needs an explanation of its relevance. A recorded owner needs actual authority and capacity.</p>
<p>Nancy Leveson&rsquo;s systems-based approach to safety examines interactions, constraints, and feedback across technical and organizational components. That perspective supports examining the handoffs through which a locally reasonable action can create a wider problem.<sup>[<a href="https://vifa-recht.de#fn22" aria-label="Footnote 22" rel="noopener noreferrer" target="_blank">22</a>]</sup></p>
<p>Machine-learning systems add their own dependencies. D. Sculley and colleagues describe technical debt involving entanglement, data dependencies, and hidden feedback loops. These are reasons to examine the surrounding system when evaluating an AI-enabled workflow.<sup>[<a href="https://vifa-recht.de#fn23" aria-label="Footnote 23" rel="noopener noreferrer" target="_blank">23</a>]</sup></p>
<p>Suppose an AI tool drafts a customer assurance from an approved template. The system needs a way to determine whether the evidence supporting that template still applies. It also needs a route for uncertainty, a person empowered to intervene, and a way to find related outputs after a material error is discovered.</p>
<p>Madeleine Clare Elish&rsquo;s account of moral crumple zones warns that a person can absorb responsibility for a system over which they had limited control. A meaningful human-review role needs information, time, competence, and effective authority.<sup>[<a href="https://vifa-recht.de#fn24" aria-label="Footnote 24" rel="noopener noreferrer" target="_blank">24</a>]</sup></p>
<p>NIST&rsquo;s 2023 AI Risk Management Framework and its 2024 Generative AI Profile provide relevant resources for lifecycle governance, risk assessment, evaluation, and management. Trust architecture asks how those activities connect to the particular promises and decisions an organization expects others to rely on.<sup>[<a href="https://vifa-recht.de#fn25" aria-label="Footnote 25" rel="noopener noreferrer" target="_blank">25</a>, <a href="https://vifa-recht.de#fn26" aria-label="Footnote 26" rel="noopener noreferrer" target="_blank">26</a>]</sup></p>
<p>One proposed measure is the <strong>correction interval</strong>: the time between a documented material change affecting a commitment and completion of an appropriate response. Detection, authorization, implementation, and communication can each contribute to that interval. An alert should reach someone who can move the response forward.</p>
<h2>Keep the architecture open to challenge</h2>
<p>A working process can still pursue an objectionable objective or distribute burdens unfairly. Sitkin and Roth&rsquo;s analysis of legalistic remedies for trust distinguishes reliability concerns from concerns about values. Additional procedure can leave those deeper concerns unresolved.<sup>[<a href="https://vifa-recht.de#fn27" aria-label="Footnote 27" rel="noopener noreferrer" target="_blank">27</a>]</sup></p>
<p>Selbst and colleagues likewise explain how abstraction can exclude the social context that makes a technical intervention meaningful. An enterprise map should remain answerable to the people whose experiences it represents, including those who find the process difficult to challenge.<sup>[<a href="https://vifa-recht.de#fn28" aria-label="Footnote 28" rel="noopener noreferrer" target="_blank">28</a>]</sup></p>
<p>The GC&rsquo;s participation also operates within existing professional responsibilities. ABA Model Rule 1.13 identifies the organization as the client. Applicable jurisdictional rules and other law govern actual duties. A broad coordination role must preserve independent legal advice and appropriate escalation.<sup>[<a href="https://vifa-recht.de#fn29" aria-label="Footnote 29" rel="noopener noreferrer" target="_blank">29</a>]</sup></p>
<p>The same discipline applies to data collection. Retain proportionate evidence, control access, and resource its maintenance. A promise-dependency map can expose sensitive relationships. Its own governance deserves scrutiny.</p>
<h2>What would show that this works?</h2>
<p>The framework should be tested against actual decisions. Can another authorized person reconstruct the basis for an assurance? Do material changes reach the right owners? Can people challenge an assumption and obtain a response? How much work does the process create?</p>
<p>Researchers could study a bounded decision class, record a baseline, introduce specific connections, and compare results across time and suitable comparison groups. Measures should include error rates, missed changes, correction intervals, unresolved concerns, and administrative burden. Recording activity volume would help distinguish improvement from a quieter period.</p>
<p>Causal interpretation requires attention to competing explanations. Faster decisions may reflect different matter complexity, staffing, or customer requirements. Pearl&rsquo;s work on causal inference provides the methodological grounding for specifying assumptions about interventions and their effects.<sup>[<a href="https://vifa-recht.de#fn30" aria-label="Footnote 30" rel="noopener noreferrer" target="_blank">30</a>]</sup></p>
<p>Research should also compare arrangements led by different functions. The GC&rsquo;s potential contribution depends on access, mandate, independence, and implementation capacity. Other leaders may have those capabilities in a given organization.</p>
<p>Above the crossing, more relationships become visible. The view remains incomplete, and the people at street level continue to know things the observer cannot see.</p>
<p>A useful trust architecture makes that incompleteness manageable. It helps people find the basis for a promise, understand their authority, question a consequential assumption, and correct an action when the evidence changes. The next person making a decision can recover its basis and carry it forward, with a clear route for revision.</p>
<h2>Author and research note</h2>
<p>Olga V. Mack is CEO of TermScout and a former general counsel. Her earlier trust-architecture research draws partly on TermScout contract data. This essay develops a theoretical proposal; its company scenarios are hypothetical, and its suggested benefits require empirical testing.</p>
<section>
<h2>References</h2>
<ol>
<li value="1">Eric Dodson Greenberg. <a href="https://news.bloomberglaw.com/legal-exchange-insights-and-commentary/gcs-are-way-beyond-strategic-in-ai-era-they-build-alignment" rel="noopener noreferrer" target="_blank">GCs Are Way Beyond &lsquo;Strategic.&rsquo; In AI Era, They Build Alignment</a>. Bloomberg Law (Apr. 20, 2026). <a href="https://vifa-recht.de#fnref1-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="2">Eric Dodson Greenberg. <a href="https://www.linkedin.com/pulse/gc-enterprise-strategist-hidden-infrastructure-value-greenberg-bar8e" rel="noopener noreferrer" target="_blank">The GC as Enterprise Strategist: The Hidden Infrastructure of Value Creation</a>. LinkedIn (May 8, 2025). <a href="https://vifa-recht.de#fnref2-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="3">Eric Dodson Greenberg. <a href="https://news.bloomberglaw.com/legal-ops-and-tech/gcs-equipped-with-ai-will-steer-the-legal-professions-future" rel="noopener noreferrer" target="_blank">GCs Equipped With AI Will Steer the Legal Profession&rsquo;s Future</a>. Bloomberg Law (Oct. 6, 2025). <a href="https://vifa-recht.de#fnref3-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="4">Olga V. Mack. <a href="https://papers.ssrn.com/sol3/papers.cfm?abstract_id=6215298" rel="noopener noreferrer" target="_blank">The CLO as Trust Architect: Empirical Evidence from Contract Governance, Litigation Management, and AI-Driven Product Risk in the Age of Artificial Intelligence</a>. SSRN working paper (2026). <a href="https://vifa-recht.de#fnref4-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"><sup>1</sup></a> <a href="https://vifa-recht.de#fnref4-2" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"><sup>2</sup></a></li>
<li value="5">Jay R. Galbraith. <a href="https://doi.org/10.1287/inte.4.3.28" rel="noopener noreferrer" target="_blank">Organization Design: An Information Processing View</a>. 4(3) Interfaces 28&ndash;36 (1974). <a href="https://vifa-recht.de#fnref5-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="6">Ronald S. Burt. <a href="https://doi.org/10.1086/421787" rel="noopener noreferrer" target="_blank">Structural Holes and Good Ideas</a>. 110 American Journal of Sociology 349&ndash;399 (2004). <a href="https://vifa-recht.de#fnref6-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="7">Karl E. Weick, Kathleen M. Sutcliffe &amp; David Obstfeld. <a href="https://doi.org/10.1287/orsc.1050.0133" rel="noopener noreferrer" target="_blank">Organizing and the Process of Sensemaking</a>. 16 Organization Science 409&ndash;421 (2005). <a href="https://vifa-recht.de#fnref7-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="8">Robert L. Nelson &amp; Laura Beth Nielsen. <a href="https://www.jstor.org/stable/3115090" rel="noopener noreferrer" target="_blank">Cops, Counsel, and Entrepreneurs: Constructing the Role of Inside Counsel in Large Corporations</a>. 34 Law &amp; Society Review 457&ndash;494 (2000). <a href="https://vifa-recht.de#fnref8-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="9">Deborah A. DeMott. <a href="https://scholarship.law.duke.edu/faculty_scholarship/1239/" rel="noopener noreferrer" target="_blank">The Discrete Roles of General Counsel</a>. 74 Fordham Law Review 955&ndash;981 (2005). <a href="https://vifa-recht.de#fnref9-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="10">Edward N. Lorenz. <a href="https://cdanfort.w3.uvm.edu/research/lorenz-1963.pdf" rel="noopener noreferrer" target="_blank">Deterministic Nonperiodic Flow</a>. 20 Journal of the Atmospheric Sciences 130&ndash;141 (1963). <a href="https://vifa-recht.de#fnref10-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="11">James P. Crutchfield. <a href="https://csc.ucdavis.edu/~cmg/papers/Crutchfield.NaturePhysics2012.corrected.pdf" rel="noopener noreferrer" target="_blank">Between Order and Chaos</a>. 8 Nature Physics 17&ndash;24 (corrected author version) (2012). <a href="https://vifa-recht.de#fnref11-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="12">Cosma Rohilla Shalizi &amp; James P. Crutchfield. <a href="https://arxiv.org/abs/cond-mat/9907176" rel="noopener noreferrer" target="_blank">Computational Mechanics: Pattern and Prediction, Structure and Simplicity</a>. 104 Journal of Statistical Physics 817&ndash;879 (2001). <a href="https://vifa-recht.de#fnref12-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="13">Claude E. Shannon. <a href="https://people.math.harvard.edu/~ctm/home/text/others/shannon/entropy/entropy.pdf" rel="noopener noreferrer" target="_blank">A Mathematical Theory of Communication</a>. 27 Bell System Technical Journal 379&ndash;423, 623&ndash;656 (corrected reprint) (1948). <a href="https://vifa-recht.de#fnref13-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="14">W. Ross Ashby. <a href="https://ashby.info/Ashby-Introduction-to-Cybernetics.pdf" rel="noopener noreferrer" target="_blank">An Introduction to Cybernetics</a>. Chapman &amp; Hall, ch. 11 (1956). <a href="https://vifa-recht.de#fnref14-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="15">Herbert A. Simon. <a href="https://faculty.sites.iastate.edu/tesfatsi/archive/tesfatsi/ArchitectureOfComplexity.HSimon1962.pdf" rel="noopener noreferrer" target="_blank">The Architecture of Complexity</a>. 106 Proceedings of the American Philosophical Society 467&ndash;482 (1962). <a href="https://vifa-recht.de#fnref15-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="16">Roger C. Mayer, James H. Davis &amp; F. David Schoorman. <a href="https://www.jstor.org/stable/258792" rel="noopener noreferrer" target="_blank">An Integrative Model of Organizational Trust</a>. 20 Academy of Management Review 709&ndash;734 (1995). <a href="https://vifa-recht.de#fnref16-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="17">Onora O&rsquo;Neill. <a href="https://doi.org/10.1080/09672559.2018.1454637" rel="noopener noreferrer" target="_blank">Linking Trust to Trustworthiness</a>. 26 International Journal of Philosophical Studies 293&ndash;300 (2018). <a href="https://vifa-recht.de#fnref17-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="18">Ronald J. Gilson, Charles F. Sabel &amp; Robert E. Scott. <a href="https://scholarship.law.columbia.edu/faculty_scholarship/583/" rel="noopener noreferrer" target="_blank">Contracting for Innovation: Vertical Disintegration and Interfirm Collaboration</a>. 109 Columbia Law Review 431&ndash;502 (2009). <a href="https://vifa-recht.de#fnref18-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="19">George G. Triantis. <a href="https://law.stanford.edu/publications/improving-contract-quality-modularity-technology-and-innovation-in-contract-design/" rel="noopener noreferrer" target="_blank">Improving Contract Quality: Modularity, Technology, and Innovation in Contract Design</a>. 18 Stanford Journal of Law, Business &amp; Finance 177 (2013). <a href="https://vifa-recht.de#fnref19-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="20">Elinor Ostrom. <a href="https://doi.org/10.1257/aer.100.3.641" rel="noopener noreferrer" target="_blank">Beyond Markets and States: Polycentric Governance of Complex Economic Systems</a>. 100 American Economic Review 641&ndash;672 (2010). <a href="https://vifa-recht.de#fnref20-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="21">Amy Edmondson. <a href="https://doi.org/10.2307/2666999" rel="noopener noreferrer" target="_blank">Psychological Safety and Learning Behavior in Work Teams</a>. 44 Administrative Science Quarterly 350&ndash;383 (1999). <a href="https://vifa-recht.de#fnref21-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="22">Nancy Leveson. <a href="https://doi.org/10.1016/S0925-7535(03)00047-X" rel="noopener noreferrer" target="_blank">A New Accident Model for Engineering Safer Systems</a>. 42 Safety Science 237&ndash;270 (2004). <a href="https://vifa-recht.de#fnref22-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="23">D. Sculley et al. <a href="https://papers.neurips.cc/paper/5656-hidden-technical-debt-in-machine-learning-systems.pdf" rel="noopener noreferrer" target="_blank">Hidden Technical Debt in Machine Learning Systems</a>. 28 Advances in Neural Information Processing Systems 2503&ndash;2511 (2015). <a href="https://vifa-recht.de#fnref23-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="24">Madeleine Clare Elish. <a href="https://doi.org/10.17351/ests2019.260" rel="noopener noreferrer" target="_blank">Moral Crumple Zones: Cautionary Tales in Human-Robot Interaction</a>. 5 Engaging Science, Technology, and Society 40&ndash;60 (2019). <a href="https://vifa-recht.de#fnref24-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="25">National Institute of Standards and Technology. <a href="https://doi.org/10.6028/NIST.AI.100-1" rel="noopener noreferrer" target="_blank">Artificial Intelligence Risk Management Framework (AI RMF 1.0)</a>. NIST AI 100-1 (Jan. 2023). <a href="https://vifa-recht.de#fnref25-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="26">National Institute of Standards and Technology. <a href="https://doi.org/10.6028/NIST.AI.600-1" rel="noopener noreferrer" target="_blank">Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile</a>. NIST AI 600-1 (July 2024). <a href="https://vifa-recht.de#fnref26-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="27">Sim B. Sitkin &amp; Nancy L. Roth. <a href="https://doi.org/10.1287/orsc.4.3.367" rel="noopener noreferrer" target="_blank">Explaining the Limited Effectiveness of Legalistic &lsquo;Remedies&rsquo; for Trust/Distrust</a>. 4 Organization Science 367&ndash;392 (1993). <a href="https://vifa-recht.de#fnref27-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="28">Andrew D. Selbst, danah boyd, Sorelle A. Friedler, Suresh Venkatasubramanian &amp; Janet Vertesi. <a href="https://doi.org/10.1145/3287560.3287598" rel="noopener noreferrer" target="_blank">Fairness and Abstraction in Sociotechnical Systems</a>. Proceedings of FAT* &rsquo;19, 59&ndash;68 (2019). <a href="https://vifa-recht.de#fnref28-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="29">American Bar Association. <a href="https://www.americanbar.org/groups/professional_responsibility/publications/model_rules_of_professional_conduct/rule_1_13_organization_as_client/" rel="noopener noreferrer" target="_blank">Model Rule of Professional Conduct 1.13: Organization as Client</a>. Model Rules of Professional Conduct. <a href="https://vifa-recht.de#fnref29-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
<li value="30">Judea Pearl. <a href="https://doi.org/10.1214/09-SS057" rel="noopener noreferrer" target="_blank">Causal Inference in Statistics: An Overview</a>. 3 Statistics Surveys 96&ndash;146 (2009). <a href="https://vifa-recht.de#fnref30-1" aria-label="Back to text" rel="noopener noreferrer" target="_blank"><img src="https://s.w.org/images/core/emoji/17.0.2/72x72/21a9.png" alt="&#8617;" referrerpolicy="no-referrer" loading="lazy"></a></li>
</ol>
</section>
</article>]]></content>
	<updated>2026-10-15T21:59:12+00:00</updated>
	<author><name>Olga Mack</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-10-15T21:59:12+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="codex - the stanford center for legal informatics"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-10-13:/301152</id>
	<link href="https://www.gautrais.com/conferences/lvi2026-coorganise-par-la-chaire-l-r-wilson-canlii-et-lexum/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=lvi2026-coorganise-par-la-chaire-l-r-wilson-canlii-et-lexum" rel="alternate" type="text/html"/>
	<title type="html">LVI2026 – coorganisé par la Chaire L.R. Wilson, CanlII et Lexum(13 octobre 2026)</title>
	<summary type="html"><![CDATA[<p>Les &#120813;&#120815; &#120306;&#120321; &#120813;&#120816; &#120316;&#120304;&#120321;&#120316;&#120303;&#120319;&#120306; &agrave; Montr&eacute;al, des experts du droit et de la technologie se r&eacute;uniront pour partage...</p>]]></summary>
	<content type="html"><![CDATA[<p>Les &#120813;&#120815; &#120306;&#120321; &#120813;&#120816; &#120316;&#120304;&#120321;&#120316;&#120303;&#120319;&#120306; &agrave; Montr&eacute;al, des experts du droit et de la technologie se r&eacute;uniront pour partager leurs perspectives, leurs travaux et leurs exp&eacute;riences sur les grands enjeux qui transforment l&rsquo;acc&egrave;s &agrave; l&rsquo;information juridique.</p>
<p>D&eacute;couvrez d&egrave;s maintenant les pr&eacute;sentations qui rythmeront ces deux journ&eacute;es de r&eacute;flexions et d&rsquo;&eacute;changes.</p>
<p>Nous avons le plaisir d&rsquo;annoncer que l&rsquo;honorable&nbsp;<span><a href="https://www.linkedin.com/in/pierre-j-dalphond/" aria-label="Voir le profil de Pierre J. Dalphond" rel="noopener noreferrer" target="_blank"><strong>Pierre J. Dalphond</strong></a></span>&nbsp;sera le conf&eacute;rencier d&rsquo;ouverture de LVI 2026, les 13 et 14 octobre prochains &agrave; Montr&eacute;al.</p>
<p>Si vous n&rsquo;avez pas pris vos billets, le lien est ici &#128073;&nbsp;<span><a href="https://www.linkedin.com/safety/go/?url=https%3A%2F%2Fwww%2Elvi2026%2Eorg%2F&amp;urlhash=PrJ6&amp;mt=bWh4ffh59oFti8alSdCTA8dQpNNgtMCjUgs6zo6nJ-U_dsdl0MSjKtdBPyrcobcEZQZeftP-u7Y3RJTeMPG46Qr1loaLRuGkGIIDY4gbxwava9tcWG1kKl1bIg&amp;isSdui=true" target="_blank" rel="noopener noreferrer" aria-label="Ouvrir https://www.lvi2026.org/"><strong>https://secure3.xpayrience.com/LVI2026</strong></a></span></p>
<p>Consultez le programme &#128073;&nbsp;<span><a href="https://www.linkedin.com/safety/go/?url=https%3A%2F%2Flnkd%2Ein%2Fg5fBiSw3&amp;urlhash=r2WU&amp;mt=VfF4VN49rxt4qp2cDlWy3HbxJi8sdJ_kc9fXFwzdma_70oiMhO1alsIUInu1vjxzbO1GBh6AbzEJFBqxb7FxNcg-YuO1CwSpiyOZuGgaGm850972NSlrIllGAw&amp;isSdui=true" target="_blank" rel="noopener noreferrer" aria-label="Ouvrir https://lnkd.in/g5fBiSw3"><strong>https://lvi2026.org/programme/https://lnkd.in/g5fBiSw3</strong></a></span></p>
<p>Coorganis&eacute;e par&nbsp;<a tabindex="0" href="https://www.linkedin.com/company/canadian-legal-information-institute/" target="_blank" rel="noopener noreferrer">CanLII</a>&nbsp;et&nbsp;<a tabindex="0" href="https://www.linkedin.com/company/lexum-inc/" target="_blank" rel="noopener noreferrer">Lexum</a>, en collaboration avec le&nbsp;<a tabindex="0" href="https://www.linkedin.com/company/free-access-to-law-movement-falm/" target="_blank" rel="noopener noreferrer">Free Access to Law Movement (FALM)</a>&nbsp;et la Chaire L.R. Wilson, avec le soutien de&nbsp;<a tabindex="0" href="https://www.linkedin.com/company/wearelegora/" target="_blank" rel="noopener noreferrer">Legora</a>,&nbsp;<a tabindex="0" href="https://www.linkedin.com/company/harvey-ai/" target="_blank" rel="noopener noreferrer">Harvey</a>&nbsp;et de la&nbsp;<a tabindex="0" href="https://www.linkedin.com/company/law-commission-canada-commission-du-droit-canada/" target="_blank" rel="noopener noreferrer">Commission du droit du Canada | Law Commission of Canada</a>.</p>]]></content>
	<updated>2026-10-13T15:55:37+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-10-13T15:55:37+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-10-07:/300454</id>
	<link href="https://law.stanford.edu/2026/10/07/setting-the-keystone-who-will-supervise-ais-legal-work/" rel="alternate" type="text/html"/>
	<title type="html">Setting the Keystone: Who Will Supervise AI’s Legal Work?</title>
	<summary type="html"><![CDATA[<p>Roman builders raised an arch in a set order: first a temporary wooden frame, the centering, to carr...</p>]]></summary>
	<content type="html"><![CDATA[<p>Roman builders raised an arch in a set order: first a temporary wooden frame, the <em>centering</em>, to carry the stones; last, the keystone at the crown. Then the stones locked together; the frame came down. Remove the frame before the keystone is set, and the arch falls.</p>
<p>The legal profession has formed lawyers the same way. The frame was apprenticeship: a junior lawyer drafts, a senior lawyer redlines, and the junior absorbs why. The keystone is judgment: the capacity to stand behind advice and supervise others. Generative AI is now taking the frame down. That is no loss in itself; much of it was drudgery. But the first drafts juniors learned from are increasingly written by machines, and the profession has not yet settled on what will hold new lawyers up while their judgment forms.</p>
<p>The Keystone Initiative at Stanford CodeX exists to solve that problem: to form lawyers who can be trusted to supervise AI&rsquo;s legal work.</p>
<h2>Judgment is not knowing the rules</h2>
<p>As Holmes wrote in <em>The Common Law</em>: &ldquo;The life of the law has not been logic: it has been experience.&rdquo; H.L.A. Hart asked whether a ban on vehicles in the park covers bicycles. Roller skates? Someone must decide; deciding well is judgment. Polanyi explained why it is hard to teach: &ldquo;we can know more than we can tell.&rdquo;</p>
<p>An expert reads a draft and knows a clause is wrong before she can say why. Often she simply fixes it. The redline, the delta between one draft and the next, is one place that judgment leaves a record.</p>
<h2>Why this is society&rsquo;s problem</h2>
<p>Law runs on answerability. Under Rule 11(b), by presenting a filing to the court, a lawyer certifies that it is based on an &ldquo;inquiry reasonable under the circumstances.&rdquo; In <a href="https://www.law.berkeley.edu/wp-content/uploads/archive/2025/12/Mata-v-Avianca-Inc.pdf" rel="noopener noreferrer" target="_blank"><em>Mata v. Avianca</em></a>, lawyers submitted a brief citing non-existent cases generated by ChatGPT, and the court reminded them of their &ldquo;gatekeeping role.&rdquo; More than 2,000 judicial decisions involving AI hallucinations or related fabricated or misrepresented material have since been <a href="https://www.damiencharlotin.com/hallucinations/" rel="noopener noreferrer" target="_blank">catalogued</a> worldwide.</p>
<p>Bar and bench put the safeguard in the same place: a competent human. <a href="https://www.americanbar.org/content/dam/aba/administrative/professional_responsibility/ethics-opinions/aba-formal-opinion-512.pdf" rel="noopener noreferrer" target="_blank">ABA Formal Opinion 512</a> says AI tools &ldquo;cannot replace the judgment and experience necessary for lawyers to competently advise clients.&rdquo; Chief Justice Roberts <a href="https://www.supremecourt.gov/publicinfo/year-end/2023year-endreport.pdf" rel="noopener noreferrer" target="_blank">wrote</a> that legal determinations &ldquo;often involve gray areas that still require application of human judgment.&rdquo; Each of these authorities places responsibility on a human capable of oversight. None says where that capability will come from.</p>
<p>The stakes reach past the profession:</p>
<ul>
<li><strong>Clients often can&rsquo;t check the work.</strong> They rely on the license. If the apprenticeship behind it hollows out, nothing announces it, and the clients least able to notice pay first.</li>
<li><strong>Law changes through people</strong> who notice an inherited rule no longer fits. Tools trained largely on past practice can reinforce it; they do not bear responsibility for deciding when it should change.</li>
<li><strong>Judgment could be rationed, or opened up.</strong> If apprenticeships grow rare, judgment becomes a perk of the right firm. Yet in a <a href="https://scholarship.law.umn.edu/minnlrev/vol109/iss1/3/" rel="noopener noreferrer" target="_blank">randomized study</a>, GPT-4 produced large speed gains, and where it improved quality, the lowest-skilled participants saw the largest gains. Measure the path from competent to expert, and judgment could reach people the old system shut out.</li>
</ul>
<h2>The irony of automation</h2>
<p>In 1983 Lisanne Bainbridge named the &ldquo;ironies of automation.&rdquo; Machines take the routine work, yet humans must still catch their failures with skills that decay without practice. &ldquo;The more advanced a control system is,&rdquo; she wrote, &ldquo;so the more crucial may be the contribution of the human operator.&rdquo; Law&rsquo;s version is sharper: the better the tools, the rarer and subtler their errors, and the more expertise needed to catch them.</p>
<p>The apprenticeship functioned, in part, like a public good paid for privately. Through billable hours, clients helped fund the training of lawyers who went on to serve others. As machines write first drafts more cheaply, clients have less reason to pay for training-by-drafting, and individual firms have less incentive to subsidize it alone. That collective-action problem needs a neutral institution.</p>
<h2>What Keystone will do</h2>
<p>Much of the record of expert judgment already exists in tracked changes and version histories across firms. Any firm can study its own, but patterns that reflect shared professional judgment rather than one partner&rsquo;s habits are more likely to emerge across many experts and matters. That points toward pooling across firms, which requires a protocol they trust.</p>
<p>So Keystone begins by developing the Redline Standard: a vendor-neutral protocol, written with the profession at the table, for de-identifying and safely contributing redlines to a Stanford-held research corpus. The standard will govern confidentiality, timing, permissions and permitted use. Its design principles are that each firm retains control of its contributions, no commercial party receives rights the firms do not grant, and nothing is asked of any firm before the standard exists.</p>
<p>We start with patent drafting where edits offer a repeatable domain for study, and most U.S. nonprovisional utility applications publish about 18 months from the earliest filing date for which benefit is claimed. Publication creates a point at which the filed text is public, though draft-level confidentiality still requires the protocol above. If the method works there, other practice areas can follow.</p>
<p>On that foundation we can build a <em>practice simulator</em>: trainees work realistic synthetic matters, free to fail, measured against expert revision, the aim being that new lawyers reach client work only after clearing a demonstrated bar. The premise, that practice against expert redlines builds judgment faster than unstructured experience, is a hypothesis; a university is where to test it rather than assert it.</p>
<p>This fall, a working group will meet at the Stanford d.school to sharpen that hypothesis, followed by a convening at Stanford Law School to begin drafting the standard. Google has committed as the initiative&rsquo;s anchor partner.</p>
<h2>Setting the keystone</h2>
<p>The frame comes down either way. The question is whether the profession sets the keystone first, or learns later what it failed to hold up.</p>
<p>The legitimacy of legal practice rests in part on a promise: behind legal work stands a person who understood it and can answer for it. Keeping that promise will take the profession acting together on neutral ground. With Roland Vogl, CodeX&rsquo;s executive director, we are building a coalition of law firms, legal departments, law schools, technology partners, and others in the legal ecosystem. Learn more at the <a href="https://law.stanford.edu/codex-the-stanford-center-for-legal-informatics/projects/the-keystone-initiative/" rel="noopener noreferrer" target="_blank">project page</a>.</p>
<p><em>Ian C. Schick, Ph.D., Esq., is a Non-Residential Fellow and leads the <a href="https://law.stanford.edu/codex-the-stanford-center-for-legal-informatics/projects/the-keystone-initiative/" rel="noopener noreferrer" target="_blank">Keystone Initiative</a> at Stanford CodeX. He is also co-founder and CEO of Paximal, a legal technology company that receives no special access under Keystone&rsquo;s governance.</em></p>]]></content>
	<updated>2026-10-07T13:44:13+00:00</updated>
	<author><name>Ian Schick</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-10-07T13:44:13+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="codex"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-10-05:/300071</id>
	<link href="https://law.stanford.edu/2026/10/05/hylton-popowycz/" rel="alternate" type="text/html"/>
	<title type="html">New Article in Stanford Computational Antitrust: Computational Rule of Reason Analysis in Antitrust</title>
	<summary type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces the publication of &ldquo;Computational Rule of Rea...</p>]]></summary>
	<content type="html"><![CDATA[<p dir="ltr">The Stanford Computational Antitrust Project announces the publication of &ldquo;<a href="https://law.stanford.edu/publications/computational-rule-of-reason-analysis-in-antitrust/" rel="noopener noreferrer" target="_blank">Computational Rule of Reason Analysis in Antitrust</a>&rdquo; by Keith N. Hylton and Karina Popowycz. The article appears in Volume 6 of Stanford Computational Antitrust (pp. 288-307).</p>
<p dir="ltr">Courts applying the rule of reason say they balance anticompetitive harms against procompetitive benefits. Few of them measure either side, and the court in Microsoft III did not. The authors ask what that balancing would look like if it were done with numbers. They build a framework in which each term of the test can be estimated and compared.</p>
<p dir="ltr">The framework weighs two kinds of effects. The static effect sets the harm to consumers and the deadweight loss from monopoly pricing against the operational efficiencies the monopolizing act may generate, such as lower supply costs. The dynamic effect adds the surplus a firm creates when it invests to build the market it later monopolizes. From this model, the authors derive the optimal antitrust penalty. When innovation does not respond to punishment, the penalty should internalize consumer harm. When monopolization does not respond, the optimal policy becomes a subsidy reflecting the innovation surplus. Most cases fall in between, and simulations show how the optimal penalty moves as consumer harm and innovation surplus vary.</p>
<p dir="ltr">The authors then turn to the decision courts actually make, which is binary. They treat an injunction as a penalty that removes the monopolist&rsquo;s entire expected gain. Where static harm is positive and innovation trivial, an injunction is optimal. Where efficiencies exceed static costs, it never is. In the hardest cases, some punishment is desirable but an injunction overshoots, and the authors show how to compute whether the cost of overenforcement outweighs the gain from deterrence.</p>
<p dir="ltr">The article closes on implementation. Welfare components can be estimated from market data, and recent machine learning methods help estimate markups without strong assumptions about firm conduct. The authors are candid about the hardest part. The firm knows its own costs better than any court, so the estimation process must give it reasons to disclose them.</p>
<p dir="ltr">Thibault Schrepel, founder of the Stanford Computational Antitrust Project, stated:</p>
<blockquote>
<p dir="ltr">&ldquo;Courts have applied the rule of reason for more than a century without saying how to weigh one side against the other. Keith Hylton and Karina Popowycz write down the balance and show that each of its terms can be estimated. They also bring innovation into the calculation, which changes the answer in many cases, sometimes to the point of favoring a subsidy over a penalty. This is how a legal standard becomes something an agency can compute.&rdquo;</p>
</blockquote>
<p dir="ltr">The article is available for download on the <a href="https://law.stanford.edu/codex-the-stanford-center-for-legal-informatics/projects/computational-antitrust/computational-antitrust-publications/" rel="noopener noreferrer" target="_blank">Stanford Computational Antitrust project&rsquo;s page</a>.</p>]]></content>
	<updated>2026-10-05T16:52:04+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-10-05T16:52:04+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-10-01:/299798</id>
	<link href="https://www.gautrais.com/conferences/soutenance-daurore-troussel-clement/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=soutenance-daurore-troussel-clement" rel="alternate" type="text/html"/>
	<title type="html">Soutenance d&amp;#8217;Aurore Troussel-Clément, Salon François Chevrette(1 octobre 2026)</title>
	<summary type="html"><![CDATA[<p>C&rsquo;est le jeudi 1er octobre avril &agrave; 10 h qu&rsquo;Aurore Troussel-Cl&eacute;ment fera sa soutenance de...</p>]]></summary>
	<content type="html"><![CDATA[<p><a href="https://www.gautrais.com/files/sites/185/2026/09/Aurore_Troussel_fe4ea8af56.jpg" rel="noopener noreferrer" target="_blank"><img decoding="async" src="https://www.gautrais.com/files/sites/185/2026/09/Aurore_Troussel_fe4ea8af56.jpg" alt="" referrerpolicy="no-referrer" loading="lazy"></a>C&rsquo;est le jeudi 1<sup>er</sup> octobre avril &agrave; 10 h qu&rsquo;<strong>Aurore Troussel-Cl&eacute;ment</strong> fera sa soutenance de th&egrave;se de doctorat en droit intitul&eacute;e&nbsp;:&nbsp;<strong><em>The Struggle for Regulation between Digital Platforms and States</em></strong><em>.</em></p>
<p>Le jury sera compos&eacute; de&nbsp;:</p>
<ul>
<li>Pr&eacute;sident&nbsp;: <a href="https://droit.umontreal.ca/faculte/lequipe/corps-professoral/fiche/in/in15004/sg/Nicolas%20Vermeys/" target="_blank" rel="noopener noreferrer">Nicolas Vermeys</a>, professeur titulaire, Universit&eacute; de Montr&eacute;al</li>
<li>Directeur de recherche&nbsp;: <a href="https://droit.umontreal.ca/faculte/lequipe/corps-professoral/fiche/in/in13916/sg/Karim%20Benyekhlef/" target="_blank" rel="noopener noreferrer">Karim Benyekhlef</a>, professeur titulaire, Universit&eacute; de Montr&eacute;al</li>
<li>Co-directeur de recherche&nbsp;: <a href="https://www.hec.edu/fr/faculty-research/faculty-directory/faculty-member/restrepoamariles-david" target="_blank" rel="noopener noreferrer">David Restrepo Amariles</a>, professeur, HEC Paris</li>
<li>Membre du jury&nbsp;: <a href="https://droit.umontreal.ca/faculte/lequipe/corps-professoral/fiche/in/in14999/sg/Vincent%20Gautrais/" target="_blank" rel="noopener noreferrer">Vincent Gautrais</a>, professeur titulaire, Universit&eacute; de Montr&eacute;al</li>
<li>Examinateur externe&nbsp;: <a href="https://www.fd.ulaval.ca/faculte/repertoire-du-personnel/pierre-luc-deziel" target="_blank" rel="noopener noreferrer">Pierre-Luc D&eacute;ziel</a>, professeur titulaire, Universit&eacute; Laval</li>
<li>Repr&eacute;sentant de la vice-rectrice adjointe des &Eacute;tudes sup&eacute;rieures et postdoctorales&nbsp;: <a href="https://histart.umontreal.ca/repertoire-departement/professeures/professeures/in/in18943/sg/Marta%20Boni/" target="_blank" rel="noopener noreferrer">Marta Boni</a>, professeure titulaire, Universit&eacute; de Montr&eacute;al</li>
</ul>
<p>L&rsquo;<a href="https://www.linkedin.com/company/acsed-udem/posts/?feedView=all" target="_blank" rel="noopener noreferrer">ACSED</a> est heureuse de soutenir cette soutenance de th&egrave;se.</p>
<p>&nbsp;</p>]]></content>
	<updated>2026-10-01T14:49:36+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-10-01T14:49:36+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-09-28:/299581</id>
	<link href="https://law.stanford.edu/2026/09/28/the-next-evolution-of-virtual-entertainment/" rel="alternate" type="text/html"/>
	<title type="html">The Next Evolution of Virtual Entertainment</title>
	<summary type="html"><![CDATA[<p>With this post, we inaugurate SEAIL&rsquo;s blog and look forward to publishing content not only from the ...</p>]]></summary>
	<content type="html"><![CDATA[<p><span>With this post, we inaugurate SEAIL&rsquo;s blog and look forward to publishing content not only from the Lab, but also courtesy of our greater network.&nbsp; Coverage will be broad, ranging from the latest entertech advancements to musings on the future of entertainment.</span></p>
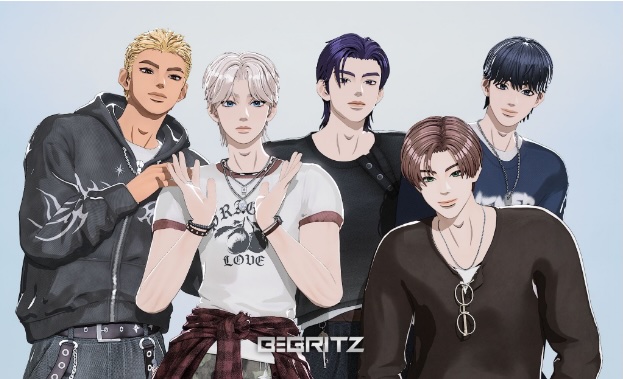
<figure aria-describedby="caption-attachment-588815"><img fetchpriority="high" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment.jpg" alt="The Next Evolution of Virtual Entertainment" srcset="https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment.jpg 623w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-300x183.jpg 300w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-132x80.jpg 132w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-220x134.jpg 220w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment.jpg 623w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-300x183.jpg 300w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-132x80.jpg 132w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-220x134.jpg 220w" sizes="(max-width: 623px) 100vw, 623px" referrerpolicy="no-referrer" loading="lazy"><figcaption><i><span>Figure 1. Virtual idol group BEGRITZ recently launched in August 2026.</span></i></figcaption></figure>
<p><span>Virtual idols have been on our minds lately. More than half a century since the Archies &ndash; a cartoon band &ndash; topped the Billboard Hot 100 in the U.S. with &ldquo;Sugar, Sugar,&rdquo; virtual idols today grace the music charts in East Asia and fill stadiums.&nbsp; Some use synthesized vocals, others real-time motion capture with human performers who remain unknown to the public at large.&nbsp;&nbsp;</span></p>
<p><span>Beyond the specific technologies deployed, each project&rsquo;s foundations share an adherence to the kind of computational law that underpins gaming environments.&nbsp; Only with constant assessment and facilitation of near-limitless virtual capabilities, ensuring that they&rsquo;re grounded in the familiar laws of our physical reality, can virtual idols perform as intended.</span></p>
<p><span>Yet for every successful project, there are many more that flop in a market projected to grow from $2 billion in 2026 to $22.6 billion by 2035. We recently touched base with South Korea-based DNABLE &ndash; the team behind the recently debuted virtual idol group BEGRITZ &ndash; regarding the granular factors that can determine success or failure.&nbsp;&nbsp;</span></p>
<p><span>Per DNABLE, </span><b>tech-centric studios </b><span>possess strong technical capabilities but lack narrative development, fandom operations, and K-POP entertainment expertise. </span><b>Entertainment-centric companies</b><span> excel at artist operations but outsource all technology, resulting in slow production cycles and excessive costs. These costs prevent rapid content updates based on fan feedback, leading to the failure of revenue models and an inability to launch subsequent IPs.</span></p>
<p><span>DNABLE&rsquo;s solution? Their </span><b>IP Factory Approach </b><span>with an integrated, in-house pipeline wherein three core categories activate together to synergize.</span></p>
<p><b>Entertainment:</b><span> Artist training, music production, content planning, fandom management, and global business development.</span></p>
<p><b>Technology:</b><span> Motion capture pipeline, real-time virtual production, AI-based asset generation, and proprietary production tools.</span></p>
<p><b>Original IP Development:</b><span> Storytelling universes, character ecosystems, and cross-media expansion.</span></p>
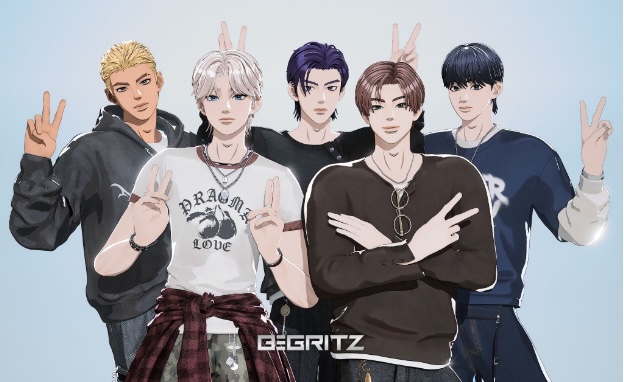
<figure aria-describedby="caption-attachment-588816"><img decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-2.jpg" alt="The Next Evolution of Virtual Entertainment 1" srcset="https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-2.jpg 624w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-2-300x184.jpg 300w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-2-131x80.jpg 131w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-2-220x135.jpg 220w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-2.jpg 624w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-2-300x184.jpg 300w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-2-131x80.jpg 131w,https://law.stanford.edu/wp-content/uploads/2026/09/the-next-evolution-of-virtual-entertainment-2-220x135.jpg 220w" sizes="(max-width: 624px) 100vw, 624px" referrerpolicy="no-referrer" loading="lazy"><figcaption><i><span>Figure 2. BEGRITZ is the first original IP of many to come via DNABLE&rsquo;s pioneering &ldquo;IP Factory Approach.&rdquo; </span></i></figcaption></figure>
<p><span>Such innovation eliminates outsourcing costs, fully internalizing the creative process from planning to broadcasting. DNABLE operational assets include permanent on-site staff dedicated to character development, motion capture, rigging, and rendering, as well as a structured pipeline encompassing each step from start to finish. Furthermore, owned studio infrastructure in the form of a fixed, physical studio space enables rapid content creation without the need for external rentals.</span></p>
<p><span>Disruptive entertech continues to reduce or bypass altogether pain points and frictions that once were a way of life in a legacy entertainment space captured by old guard firms and entrenched IP incumbents. The next evolution of virtual entertainment is proving far more nimble and self-sufficient.</span></p>
<p><span>For further info, see DNABLE&rsquo;s </span><a href="https://dnable.xyz/" rel="noopener noreferrer" target="_blank"><span>website</span></a><span> or follow </span><a href="https://x.com/begritz" rel="noopener noreferrer" target="_blank"><span>BEGRITZ on X</span></a><span>. </span></p>]]></content>
	<updated>2026-09-28T17:33:03+00:00</updated>
	<author><name>Stanford Entertech &amp;amp; AI Lab</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-09-28T17:33:03+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="codex"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-09-24:/299157</id>
	<link href="https://law.stanford.edu/2026/09/23/does-paternal-age-matter-in-fertility-treatment/" rel="alternate" type="text/html"/>
	<title type="html">Does Paternal Age Matter in Fertility Treatment?</title>
	<summary type="html"><![CDATA[<p>Earlier this month, Denmark announced that it will introduce an upper age limit for men seeking acce...</p>]]></summary>
	<content type="html"><![CDATA[<p>Earlier this month, Denmark announced that it will introduce an upper age limit for men seeking access to publicly funded fertility treatment. From January 1, 2027, men undergoing treatment with their partners will be required to receive a clinic referral before the age of 55, and all treatment courses must end when the man turns 56 [1]. Restrictions already apply to women seeking fertility treatment in Denmark whereby publicly funded treatment must end when the woman turns 41, while private treatment may continue until she turns 46 [2]. The new Danish rule will introduce the first equivalent upper age limit for men in the public system. However, those already undergoing treatment when the rule comes into effect will be permitted to complete it, and men above the age threshold will remain eligible to pursue treatment privately [1].</p>
<p>Paternal age limits are not unique and can be seen in other publicly funded fertility programmes across Europe [3]. Their use, however, remains somewhat notable given that men generally retain the biological capacity to father children considerably later in life [4]. Indeed, that reproductive capacity may persist well beyond the age of 55 [4]. This raises an important question regarding what exactly makes paternal age relevant in fertility treatment, and whether those concerns justify restricting access?</p>
<p>In its announcement, Denmark cited three primary concerns in support of the new rule, each of which provides a distinct reason why paternal age might matter in the provision of fertility treatment.&nbsp;These included:</p>
<ul>
<li>age-related clinical risks associated with sperm;</li>
<li>the effect of sperm age on declining treatment efficacy; and</li>
<li>concern for the welfare of the resulting child, including the likelihood of parental death before the child reaches adulthood [1].</li>
</ul>
<p>The first two relate directly to a man&rsquo;s role as a genetic parent and to the ways in which his chronological age may bear on both clinical risk and treatment success [1]. Advanced paternal age has been associated with changes in semen parameters, certain pregnancy complications, and stillbirth [4-6]. It has also been linked to a range of neurodevelopmental and other disorders in offspring, although findings are not always consistent and the absolute increase in risk to any individual child remains low [4, 7-8]. Some studies have also reported lower conception and live-birth rates following fertility treatment as paternal age increases [9]. Paternal age may therefore be relevant where it serves as a proxy for potential medical risks associated with sperm produced at an older age, or for the likelihood of successful treatment [4].</p>
<p>What&rsquo;s interesting in this context, however, is that reproductive technologies can sometimes weaken the relationship between a man&rsquo;s chronological age and these clinical concerns. For example, where donor sperm is used, the chronological age of the man who will raise the child may be entirely different from that of the gamete source, and the clinical concerns associated specifically with the age of the prospective father&rsquo;s sperm may disappear entirely [4, 6]. Alternatively, where a man uses his own sperm cryopreserved at a younger age, his current chronological age no longer corresponds to the age of the gametes used in treatment. Indeed, a 55-year-old using sperm cryopreserved when he was 30 presents a materially different gamete-age question from a 55-year-old using sperm produced at 55 [4, 6]. Denmark&rsquo;s regime provides a particularly useful illustration here because its publicly funded fertility system already provides for treatment using donor sperm [10] and contemplates the use of sperm cryopreserved earlier in a man&rsquo;s life [11]. Despite this, at least as currently described, the Danish rule contains no exception where donor sperm or sperm cryopreserved at a younger age is used in treatment [1].</p>
<p>The rule also appears to apply irrespective of why the couple requires fertility treatment in the first place [1]. A couple may, for instance, seek treatment due to female-factor infertility rather than any impairment in the man&rsquo;s fertility. A man may therefore remain capable of fathering a child without assisted reproduction, yet his age may render him ineligible for publicly funded treatment should his partner require assistance [1]. This does not necessarily render the new rule redundant and once the man&rsquo;s sperm <em>is</em> being used in treatment, his age may still become clinically relevant [4]. However, when the clinical concerns associated with the age of the man&rsquo;s sperm can themselves be mitigated by the reproductive technologies being used, relying on those same concerns to support a paternal age limit is counterintuitive.</p>
<p>The third concern identified in support of Denmark&rsquo;s age restriction is different. It does not relate to the man&rsquo;s age as a genetic contributor, but to his age as a prospective social parent who will raise the resulting child [1]. In the older parent context, several concerns might be framed as child welfare, including the prospective father&rsquo;s physical capacity to care for a child, the likelihood that an age-related illness may affect caregiving, and the possibility that he may die while the child remains dependent [4]. Denmark placed particular emphasis on the last concern, expressly referring to the risk that a child may lose an older father before reaching adulthood [1].</p>
<p>Child welfare is important in the provision of fertility treatment generally [4], and there is nothing objectionable about Denmark taking this into account in the older parent context. Nevertheless, concerns of this kind are not unique to older parenthood. Questions about caregiving capacity can arise, for example, where parents have disabilities or serious health conditions, while children of younger parents may also experience parental illness, injury or premature death [12-14]. Advancing age may make some child welfare concerns more probable, particularly those relating to illness and death [4], but difficulties in caregiving, serious illness and loss can arise across parenthood generally [12-14].</p>
<p>Concerns regarding parental longevity are, however, more closely tied to age. Children born to older parents are statistically more likely to experience the death of a parent while they are minors [3], and childhood bereavement has been associated with a range of adverse psychological, social and educational outcomes in children [15]. Older parenthood does not, however, make parental death during childhood inevitable. Children can lose parents at any age, and the effects of that loss vary considerably according to the circumstances in which it occurs [13, 15]. In particular, the bereavement literature emphasizes the importance of what happens to children following the death of a parent on their eventual welfare [15]. For example, where a child experiences disruption in caregiving, living arrangements and schooling, this can compound the effects of parental loss, whereas continuity in care and stable social support may help protect a child from some of grief&rsquo;s most serious consequences [15]. Accordingly, an individualized assessment of the prospective father&rsquo;s health, the circumstances of the other parent, available support, and continuity of care planning might target the underlying welfare concern more directly and less restrictively than a categorical age limit.</p>
<p>Ultimately, paternal age<em> can</em> matter in the provision of fertility treatment. It may matter clinically because of the age of the gametes used in treatment, and it may matter because of the age of the person who will raise the resulting child, particularly where continuity of care is at issue [1, 4]. Where these concerns cannot be mitigated by assisted reproduction itself or addressed more directly through individualized assessment of the prospective father&rsquo;s circumstances, restricting access may be justified to reduce the underlying risks associated with advanced paternal age [1, 4]. However, where those concerns <em>can</em> be substantially overcome, paternal age alone should not justify categorical exclusion [16].</p>
<p>Of course, in Denmark, the public context of the new rule complicates this [1]. Individualized assessments of the prospective father&rsquo;s circumstances, including future caregiving arrangements, could be resource intensive and time consuming. Indeed, this may be a significant burden for a publicly funded system where finite resources must be allocated between patients [4, 17-18]. Moreover, while procreative liberty may protect an individual&rsquo;s freedom to make reproductive choices, it does not necessarily entail a positive entitlement to have the state fund or facilitate those choices [19]. That justification, however, is considerably harder to sustain where treatment is privately funded. Here, resource allocation no longer provides the same rationale for categorical exclusion [17-18], and where the clinical and child welfare concerns associated with age can be adequately mitigated, chronological age alone should not determine access to treatment. In broader debates about older fatherhood, it is therefore worth considering what underlying risk chronological age is being used to represent, and whether that risk can be addressed through less restrictive means than categorical age caps.</p>
<h3><strong>References:</strong></h3>
<p>[1] Danske Regioner, &ldquo;Danish Regions Introduce Age Limit of 55 for Men in Fertility Treatment&rdquo; (1 September 2026)</p>
<p>[2] L. Catalini, J. Fedder, B. N&oslash;rg&aring;rd and L. Joelving, &ldquo;Assisted Reproductive Technology Results Using Donor or Partner Sperm: A Danish Nationwide Register-Based Cohort Study&rdquo; (2023) 12 Journal of Clinical Medicine 2571.</p>
<p>[3] S.R. Piek, A. Martani and G. Pennings, &ldquo;Against age limits for men in reproductive care&rdquo; (2024) Medicine, Health Care and Philosophy.</p>
<p>[4] Ethics Committee of the American Society for Reproductive Medicine, &lsquo;Assisted reproduction with advancing paternal and maternal age: an Ethics Committee opinion&rsquo; (2025) 123(6) Fertility and Sterility 999.</p>
<p>[5] P.T.K. Chan and B. Robaire, &ldquo;Advanced Paternal Age and Future Generations&rdquo; (2022) 13(6) Translational Andrology and Urology 861.</p>
<p>[6] K.R. Smith, &ldquo;Paternal age bioethics&rdquo; (2015) 41 Journal of Medical Ethics 775.</p>
<p>[7] R. Sharma, A. Agarwal, V.K. Roha, M. Assidi. M. Abu-Elmagd and R.F. Turki. &ldquo;Effects of increased paternal age on sperm quality, reproductive outcome and associated epigenetic risks to offspring&rdquo; (2015) 13 Reproductive Biology Endocrinology 35.</p>
<p>[8] A.M. Nybo Andersen and S.K. Urhoj, &ldquo;Is advanced paternal age a health risk for the offspring?&rdquo; (2017) 107 Fertility and Sterility 312.</p>
<p>[9] A.M. Marsidi, L.M. Kipling, J.F. Kawwass and A. Mehta, &ldquo;Influence of paternal age on assisted reproductive technology cycles and perinatal outcomes&rdquo; (2021) 116 Fertility and Sterility 380.</p>
<p>[10] Region Midtjylland, <em>Infertilitet </em>(2025).</p>
<p>[11] Region Syddanmark, <em>Infertilitet </em>(2026).</p>
<p>[12] R. Powell, &lsquo;Disability Reproductive Justice&rsquo; (2022) 170 University of Pennsylvania Law Review 1851.</p>
<p>[13] J. Xu, S.L. Murphy, K.D. Kochanek and E. Arias, &lsquo;Mortality in the United States, 2024&rsquo; (National Center for Health Statistics Data Brief No 548, January 2026), available at &lt;https://www.cdc.gov/nchs/data/databriefs/db548.pdf&gt;.</p>
<p>[14] National Council on Disability, <em>Rocking the Cradle: Ensuring the Rights of Parents with Disabilities and their Children</em> (2012).</p>
<p>[15] R.A. Haine, T.S. Ayers, I.N. Sandler and S.A. Wolchik, &ldquo;Evidence-Based Practices for Parentally Bereaved Children and Their Families&rdquo; (2008) 39(2) Professional Psychology: Research and Practice 113.</p>
<p>[16] A.A. Boni-Saenz, &ldquo;Legal Age&rdquo; (2022) 63 Boston College Law Review 521.</p>
<p>[17] K. Asplund, &ldquo;Use of in vitro fertilization-ethical issues&rdquo; (2020) 125(2) Upsala Journal of Medical Sciences 192.</p>
<p>[18] J. Lind, &ldquo;Child welfare assessments and the regulation of access to publicly funded fertility treatment&rdquo; (2020) 10 Reproductive Biomedicine &amp; Society Online 19.</p>
<p>[19] D. Fox, &ldquo;Privatizing Procreative Liberty in the Shadow of Eugenics&rdquo; (2018) Journal of Law and the Biosciences 355.</p>]]></content>
	<updated>2026-09-23T22:09:13+00:00</updated>
	<author><name>Claire McGovern</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-09-23T22:09:13+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-09-21:/298977</id>
	<link href="https://law.stanford.edu/2026/09/21/fifth-computational-antitrust-report/" rel="alternate" type="text/html"/>
	<title type="html">The Paris launch of the fifth Computational Antitrust report</title>
	<summary type="html"><![CDATA[<p>On 17 September 2026, we launched the fifth cross-agency report of Stanford Computational Antitrust ...</p>]]></summary>
	<content type="html"><![CDATA[<p dir="ltr">On 17 September 2026, we launched the fifth cross-agency report of <a href="https://law.stanford.edu/computationalantithttps://law.stanford.edu/computationalantitrust" rel="noopener noreferrer" target="_blank">Stanford Computational Antitrust</a> at the Autorit&eacute; de la concurrence in Paris. We were delighted to be welcomed there for the first time. The Autorit&eacute; is one of the very few agencies to have contributed to all five reports, so the report could hardly have found a better home. The afternoon ended with a cocktail reception. As always, we are most grateful to Stanford CodeX for its incredible support of everything we do.</p>
<p dir="ltr"><strong>Watch</strong> on <a href="https://youtu.be/EXN4_dXiYBA" rel="noopener noreferrer" target="_blank">YouTube</a>, or listen on <a href="https://open.spotify.com/episode/2tgAYvvlN5uPp63CpHsAuy" rel="noopener noreferrer" target="_blank">Spotify</a> and <a href="https://podcasts.apple.com/fr/podcast/stanford-computational-antitrust/id1555499856?i=1000790883302" rel="noopener noreferrer" target="_blank">Apple Podcasts</a>.</p>
<p dir="ltr"><strong>Read</strong> the report, open access, at <a href="https://shorturl.at/wmEaW" rel="noopener noreferrer" target="_blank">shorturl.at/wmEaW</a></p>
<p dir="ltr">
</p><p><img fetchpriority="high" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report.jpg" alt="The Paris launch of the fifth Computational Antitrust report" srcset="https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report.jpg 1280w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-300x169.jpg 300w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-1024x576.jpg 1024w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-768x432.jpg 768w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-1152x648.jpg 1152w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-142x80.jpg 142w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-220x124.jpg 220w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report.jpg 1280w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-300x169.jpg 300w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-1024x576.jpg 1024w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-768x432.jpg 768w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-1152x648.jpg 1152w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-142x80.jpg 142w,https://law.stanford.edu/wp-content/uploads/2026/09/the-paris-launch-of-the-fifth-computational-antitrust-report-220x124.jpg 220w" sizes="(max-width: 1280px) 100vw, 1280px" referrerpolicy="no-referrer" loading="lazy"></p>
<p dir="ltr"><strong><span>A growing network</span></strong></p>
<p dir="ltr">88 competition agencies now take part in the project, and 52 have written for at least one report. 30 contributed to this edition, 11 of them for the first time, which makes it the largest yet. Five agencies have written every single year since 2022, namely Brazil, Catalonia, Czechia, Singapore and our host, the French.</p>
<p dir="ltr">The answers to this year&rsquo;s question fall into two kinds. Some agencies point to a case they would not have opened. Latvia&rsquo;s price monitor flagged coffee machine distributors, which led to dawn raids in three Baltic countries and an infringement decision this year. Others point to conduct they could not examine at all before. Poland studies dark patterns with eye tracking and has reviewed more than three hundred websites, and the Netherlands reads the news for mergers that were never notified.</p>
<p dir="ltr"><span><strong>Three developments</strong></span></p>
<p dir="ltr"><strong>Agencies write their own rules.</strong> No legal regime tells an agency what may go into a model, so agencies have begun writing the rules themselves. Luxembourg built its AI strategy on the principles its government set for the whole public administration. Tanzania chose to wait until its infrastructure includes validation safeguards. Only one court of appeal has ruled on computational evidence so far, in Brazil&rsquo;s Novo Rumo case, where a warrant based on network metrics and econometric screens was held valid.</p>
<p dir="ltr"><strong>Agencies put numbers on their work.</strong> Earlier editions almost never reported precision, recall or false-positive rates. This one does. Kazakhstan identifies indicators of collusion in two days instead of two months, and opened 139 investigations in one year against 67 over the previous three. Singapore shortlists suspicious tenders in under ten minutes where it used to take weeks. Pakistan reports ninety-two percent detection accuracy on a test set of four thousand records.</p>
<p dir="ltr"><strong>Data decides more than technique.</strong> What holds deployment back is access to data and the agreements needed to obtain it. CARICOM cannot compel firm-level data in several member states, so it runs econometrics on public macroeconomic data instead. Lithuania paused its bid-rigging screen when public procurement data lost detail. The Autorit&eacute; itself sees only winning bids in French tenders. Some agencies lobbied their parliaments to change the law. Others renegotiate access every time.</p>
<p dir="ltr"><strong><span>What it adds up to</span></strong></p>
<p dir="ltr">The first generation of tools helped agencies do the same work faster. This generation lets them watch markets continuously and bring cases of a different kind. 19 of the 30 agencies now run or build an internal assistant based on a large language model, a category absent from the report two editions ago, and a third of them are on one side or the other of a tool exchange with another agency. The most pressing questions are now legal ones, which, as Thibault Schrepel put it in Paris, is good news, because &ldquo;we lawyers can actually do something about that.&rdquo;</p>
<p dir="ltr"><strong><span>Where to jump in</span></strong></p>
<ul>
<li dir="ltr"><strong>09:09 Screening tenders.</strong> Public procurement has become the field where agencies build their strongest tools, because it produces large and fairly standard datasets. Alba Ribera Mart&iacute;nez presents two of them. The Dominican Republic&rsquo;s Sem&aacute;foro Colusorio scores each tender on forty-nine variables and sorts it into one of five risk levels. Pakistan links procurement data to the corporate registry in a graph database and reports ninety-two percent detection accuracy on a test set of four thousand records.</li>
<li dir="ltr"><strong>14:23 Cases that would not exist.</strong> Thibault Schrepel sorts the agencies&rsquo; answers into two kinds. Some tools found cases an agency suspected but lacked the staff to pursue. Latvia&rsquo;s price monitor flagged coffee machine distributors, which led to dawn raids in three Baltic countries and an infringement decision this year. Brazil&rsquo;s C&eacute;rebro project produced a bid-rigging proceeding worth 2.2 billion dollars against sixteen companies and fifteen individuals.</li>
<li dir="ltr"><strong>14:23 Conduct no one could see before.</strong> Other tools open ground that did not exist. Poland studies dark patterns with eye tracking and facial expression analysis and has reviewed more than three hundred websites. T&uuml;rkiye runs a deep-learning model over producer prices in 555 sectors at once. The Netherlands reads the news for mergers that were never notified.</li>
<li dir="ltr"><strong>14:23 The Very Cool Use Cases.</strong> Schrepel then picks one use per agency that no other agency reports. Taiwan runs speech-to-text in interview rooms, trained on Mandarin, Taiwanese Hokkien and Hakka, on a four-billion-parameter model that never leaves the building. Kazakhstan screens three to four hundred regulatory acts in minutes and flags anticompetitive restrictions to members of parliament. The rule for making the list? &ldquo;You have to be unique to be cool.&rdquo;</li>
<li dir="ltr"><strong>23:28 When the data is not there.</strong> Ribera Mart&iacute;nez turns to the obstacles. CARICOM has no power to compel firm-level data in several of its member states, so it runs econometrics on public macroeconomic data instead. Lithuania built a bid-rigging screen and then paused it, because the public procurement data it relied on had lost detail over time. Tanzania has chosen to wait until its infrastructure includes validation safeguards.</li>
<li dir="ltr"><strong>29:18 The question no court has settled.</strong> Agencies now use these tools from the opening of a case to the evidence file. What happens when a company asks them to reproduce the result on appeal? Schrepel walks through what an agency may have to keep, from training data to model weights to every internal run. &ldquo;If the competition agency comes your way and says, well, my machine learning system told me this is illegal, this is not good enough.&rdquo;</li>
<li dir="ltr"><strong>29:18 Three minutes for a merger decision.</strong> The president of Brazil&rsquo;s competition agency said on the project&rsquo;s podcast that a draft phase-one merger decision is generated within three minutes of receiving the file, then checked by staff. Schrepel also counts that a third of the thirty agencies are on one side or the other of a tool exchange with another agency, and Canada offers its tool to any agency that asks.</li>
<li dir="ltr"><strong>34:07 Why build a digital unit.</strong> Elodie Vandenhende explains why the Autorit&eacute; created its Digital Economy Unit in 2020, reporting directly to the General Rapporteur. The unit brought lawyers, economists and data scientists into one team. It has since written the Autorit&eacute;&rsquo;s opinions on cloud computing, generative AI, the energy and environmental footprint of AI, and, this July, AI agents.</li>
<li dir="ltr"><strong>41:52 Asking ChatGPT and Gemini five hundred shopping questions.</strong> Yann Guthmann presents the experiment behind the July opinion. Asked in French, ChatGPT searched the web in English and drew on Reddit in nearly nine generic queries out of ten, without citing it in its answers. Gemini leaned on YouTube. A small group of websites supplied most of the sources for both. The questions and the results are on the Autorit&eacute;&rsquo;s GitHub, so anyone can rerun the test.</li>
<li dir="ltr"><strong>41:52 A search engine across agencies.</strong> Guthmann shows project TARDIS, run within the ICN, which puts decisions from France, New Caledonia and Switzerland into one open database, with French Polynesia and Chile to follow. A retrieval tool answers in English from decisions written in French. His case for open data is practical. Agencies cannot share confidential files with each other, but they can build together on public data.</li>
<li dir="ltr"><strong>55:24 From filing cabinets to full maturity.</strong> Teodora Groza traces five editions of the report, from agencies scanning archives in 2022 to whole data departments in 2025. Her marker of the first real gains is Spain, where the share of cartel cases detected by in-house tools went from thirty to seventy percent. On Singapore&rsquo;s self-assessment tool for companies, she describes &ldquo;the enforcer and the firm&rdquo; as &ldquo;not adversaries but collaborators.&rdquo;</li>
<li dir="ltr"><strong>55:24 The capability divide.</strong> Groza closes on what she will watch next. Some agencies in this edition report supercomputers, while others report no budget at all. Tools travel easily between agencies, but computing power does not.</li>
<li dir="ltr"><strong>1:08:22 The data, not the tools.</strong> Asked how the Autorit&eacute; uses AI, Guthmann describes open-weight Mistral models running on its own servers, used to digest merger filings and to group the answers when fifty firms reply to the same request for information. Asked why France does not screen public tenders, he answers that French public data covers only winning bids, and anomalies are hard to detect without the losing ones. &ldquo;It&rsquo;s not a problem of we don&rsquo;t have the tools, it&rsquo;s a problem that we don&rsquo;t have the data.&rdquo;</li>
<li dir="ltr"><strong>1:10:41 The only ruling so far.</strong> Schrepel notes that one court of appeal has assessed computational evidence produced by an agency. In Brazil&rsquo;s Novo Rumo case, a search warrant based on network metrics and econometric screens was held valid, and the case went on.</li>
<li dir="ltr"><strong>1:21:45 A digital brain of every EU merger decision.</strong> To close, Schrepel shows a knowledge graph linking some 8,500 European Commission merger decisions by the concepts they address. A case handler can ask it questions in plain language, or drop in a draft decision and see where it departs from past practice. Agencies are already working with the project to build their own, and practising lawyers can do the same.</li>
</ul>
<p dir="ltr"><strong><span>Speakers</span></strong></p>
<p dir="ltr"><strong>Thibault Schrepel</strong>, Associate Professor of Law at Vrije Universiteit Amsterdam, Faculty Affiliate at Stanford CodeX and Director of Stanford Computational Antitrust <strong>Alba Ribera Mart&iacute;nez</strong>, Assistant Professor in Law and Technology at Vrije Universiteit Amsterdam and Editor-in-Chief of Stanford Computational Antitrust <strong>Elodie Vandenhende</strong>, Deputy Head of the Digital Economy Unit, Autorit&eacute; de la concurrence <strong>Yann Guthmann</strong>, Head of the Digital Economy Unit, Autorit&eacute; de la concurrence <strong>Teodora Groza</strong>, Postdoctoral Researcher at the Chair for Law and Artificial Intelligence, University of T&uuml;bingen.</p>]]></content>
	<updated>2026-09-21T11:18:17+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-09-21T11:18:17+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-09-18:/298795</id>
	<link href="https://www.gautrais.com/conferences/justice-augmentee-lintelligence-artificielle-au-service-de-la-prevention-et-du-reglement-des-differends/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=justice-augmentee-lintelligence-artificielle-au-service-de-la-prevention-et-du-reglement-des-differends" rel="alternate" type="text/html"/>
	<title type="html">Justice augmentée&amp;#160;: l’intelligence artificielle au service de la prévention et du règlement des différends, Justice augmentée : l’intelligence artificielle au service de la prévention et du règlement des différends, Barreau du Québec – Maison du Barreau (Montréal)(18 septembre 2026)</title>
	<summary type="html"><![CDATA[]]></summary>
	<content type="html"><![CDATA[]]></content>
	<updated>2026-09-18T13:13:22+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-09-18T13:13:22+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-09-16:/298641</id>
	<link href="https://www.gautrais.com/conferences/ia-preuve/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=ia-preuve" rel="alternate" type="text/html"/>
	<title type="html">IA + Preuve, HEC Montréal centre-ville, salle C.403 Louis-R Chênevert, 501 Rue De la Gauchetière Ouest(16 septembre 2026)</title>
	<summary type="html"><![CDATA[<p>MERCREDI 16 septembre 2026
Justice et services sociaux
Mod&eacute;rateur&nbsp;:&nbsp;Pierre Larouche
Cette journ...</p>]]></summary>
	<content type="html"><![CDATA[<h2><strong>MERCREDI 16 septembre 2026</strong></h2>
<h4><strong>Justice et services sociaux</strong></h4>
<p><strong>Mod&eacute;rateur&nbsp;:&nbsp;</strong><a href="https://droit.umontreal.ca/faculte/lequipe/corps-professoral/fiche/in/in28933/sg/Pierre%20Larouche/" target="_blank" rel="noopener noreferrer"><u>Pierre Larouche</u></a></p>
<p>Cette journ&eacute;e explorera les transformations induites par l&rsquo;IA pour la justice et les droits fondamentaux. Les conf&eacute;rences porteront sur l&rsquo;aide &agrave; la d&eacute;cision judiciaire, l&rsquo;administration de la preuve, ainsi que les enjeux d&rsquo;&eacute;quit&eacute;, de gouvernance et de droits fondamentaux soulev&eacute;s par le d&eacute;ploiement de l&rsquo;IA dans les domaines de la justice et des migrations.</p>
<p>9 h 30 &ndash; 10 h 00&nbsp;: Accueil des participantes et participants&nbsp;et caf&eacute;</p>
<p>10 h 00 &ndash; 10 h 45&nbsp;:&nbsp;<strong>L&rsquo;intelligence artificielle peut-elle faire des juges de meilleurs juges&nbsp;? L&rsquo;IA, les affaires difficiles et l&rsquo;avenir du pouvoir d&rsquo;appr&eacute;ciation judiciaire.</strong><br>
<a href="https://www.bsg.ox.ac.uk/people/alejandro-moya-riveros" target="_blank" rel="noopener noreferrer">Alejandro Moya Riveros</a>&nbsp;(Universidad de los Andes/ Harvard University/ Oxford Institute of Technology and Justice &ndash; University of Oxford)</p>
<p>10 h 45 &ndash; 11 h 30&nbsp;:&nbsp;<strong>L&rsquo;intelligence artificielle au service de la justice&nbsp;: de l&rsquo;inadaptation du cadre g&eacute;n&eacute;ral &agrave; la d&eacute;clinaison sectorielle &ndash; l&rsquo;aide &agrave; la r&eacute;daction des d&eacute;cisions comme cas r&eacute;v&eacute;lateur</strong><br>
<a href="https://crj.univ-grenoble-alpes.fr/vie-scientifique/projets-recherche-en-cours/chaire-ai-legaltools" target="_blank" rel="noopener noreferrer">G&eacute;raldine Vial</a>&nbsp;(Universit&eacute; Grenoble-Alpes)</p>
<p>11 h 30 &ndash; 12 h 15&nbsp;:&nbsp;<strong>IA + preuve</strong><br>
<a href="https://www.gautrais.com/" target="_blank" rel="noopener noreferrer">Vincent Gautrais</a>&nbsp;(Universit&eacute; de Montr&eacute;al)</p>
<p>&nbsp;</p>]]></content>
	<updated>2026-09-16T13:32:37+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-09-16T13:32:37+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-09-11:/298316</id>
	<link href="https://www.gautrais.com/publications/usages/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=usages" rel="alternate" type="text/html"/>
	<title type="html">Vincent Gautrais, «Usages», dans Vincent Gautrais (dir.), Dictionnaire de la norme: formaliser l&#039;informel, (2024) 29-3 Lex electronica 1-23 (août 2026). </title>
	<summary type="html"><![CDATA[<p>[1] Plan. Dans la mesure o&ugrave; notre propos tend &agrave; se centrer sur cette qu&ecirc;te d&eacute;finitionnelle, nos nomb...</p>]]></summary>
	<content type="html"><![CDATA[<p>[1] Plan. Dans la mesure o&ugrave; notre propos tend &agrave; se centrer sur cette qu&ecirc;te d&eacute;finitionnelle, nos nombreuses lectures, issues de diff&eacute;rentes disciplines juridiques et provenant de plusieurs juridictions, &agrave; plusieurs &eacute;poques, nous permettent de d&eacute;gager trois grandes questions autour de la notion d&rsquo;usage. En premier lieu, nous nous devons de faire mention d&rsquo;un &eacute;tat des lieux o&ugrave; cette notion, pourtant essentielle, a toujours p&acirc;ti d&rsquo;une complexit&eacute; d&rsquo;analyse, que ce soit dans la doctrine ou la jurisprudence. En deuxi&egrave;me lieu, cette ind&eacute;finition s&rsquo;est traduite sur le plan plus conceptuel, plus th&eacute;orique, dans la difficult&eacute; &agrave; d&eacute;terminer la force obligatoire des usages, oscillant entre contrat et norme. En troisi&egrave;me lieu, et de fa&ccedil;on plus pratique cette fois, il est &eacute;tonnant de constater certaines carences &agrave; identifier les crit&egrave;res de reconnaissance des usages. Trois points donc&nbsp;: le premier tient lieu du constat chagrin de ces variantes multiples de perspectives. Les deux suivants sont davantage un choix &eacute;ditorial de deux questionnements centraux qui demandent &agrave; &ecirc;tre appr&eacute;hend&eacute;s.</p>
<p>&nbsp;</p>]]></content>
	<updated>2026-09-10T22:22:37+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-09-10T22:22:37+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-09-10:/298084</id>
	<link href="https://law.stanford.edu/2026/09/09/no-means-maybe-posthumous-embryo-use-in-the-australian-capital-territory-despite-an-express-refusal/" rel="alternate" type="text/html"/>
	<title type="html">‘No’ Means ‘Maybe’: Posthumous Embryo Use in the Australian Capital Territory Despite an Express Refusal</title>
	<summary type="html"><![CDATA[<p>In the matter of KD [2026] ACTSC 231
In July 2026, Muller J, in the Supreme Court of the Australian ...</p>]]></summary>
	<content type="html"><![CDATA[<h3><strong><em>In the matter of KD</em></strong> <strong>[2026] ACTSC 231</strong></h3>
<p>In July 2026, Muller J, in the Supreme Court of the Australian Capital Territory (ACT), made an order authorizing the posthumous use of a stored embryo, despite written instructions from the deceased indicating a desire for his genetic material and embryos to be discarded following death [1].</p>
<p>The facts of this case are particularly heartbreaking. The applicant, KD, and the deceased, CT, had spent several years of their relationship trying to have a child. They underwent multiple rounds of IVF treatment in Australia and overseas but were ultimately unsuccessful in conceiving. During the process of IVF, the couple independently answered questions regarding the fate of their genetic material after death, both expressing a desire for their gametes and embryos to be destroyed. In October 2025, CT was diagnosed with a brain tumor and died less than a month after commencing treatment. At the time of his death, one embryo created using the couple&rsquo;s gametes remained in storage. Thus, KD applied to the Supreme Court for an order authorizing her to use it in assisted reproduction despite CT&rsquo;s express refusal [1].</p>
<p>Somewhat surprisingly, the statutory regime in the ACT permits this. Section 36 of <em>the Assisted Reproductive Technology Act 2024</em> (ACT) generally prohibits ART providers from using the gametes of a deceased person in treatment [2]. However, treatment may proceed if the deceased gamete provider has consented to use in the relevant circumstances [3], or a court order pursuant to Section 37 authorizes treatment to the deceased&rsquo;s domestic partner [4]. When considering an application under Section 37, the Court must have regard to several factors, including whether the deceased expressly objected to posthumous use [5], and whether, despite that objection, the deceased was likely to have supported treatment for their domestic partner [6]. The legislation therefore makes an express objection by the deceased a relevant consideration for the Court, but not determinative as to whether treatment proceeds.</p>
<p>In granting KD&rsquo;s application, the Court placed significant weight on the couple&rsquo;s sustained efforts to become parents during their relationship [1].&nbsp;This is an understandable starting point and may have been of particular relevance for the Court had CT&rsquo;s views been unknown. For instance, had CT left no instructions concerning posthumous use, his commitment to parenthood during life might have credibly supported an inference that he would have wished for KD to continue with treatment [7]. CT&rsquo;s wishes, however, were not unknown, and evidence of his desire to be a father during his lifetime should not have been given equivalent or, indeed, greater weight than his direct answer to that question [1].</p>
<p>This is crucial when the interests in posthumous parenthood are distinct from and more attenuated than those in living parenthood [8, 9]. Becoming a father during his lifetime would have allowed CT to know and raise his child, participate in the child&rsquo;s daily care, and share the experience of parenthood with KD. However, those interests can no longer be realized for him through posthumous reproduction [9].&nbsp;Of course, that is not to say that the remaining interests in posthumous parenthood are unimportant. CT may have had critical interests in genetic continuity or in enabling KD to continue their shared reproductive project [9, 10]. But the Court did not separately identify that CT held any such interests. Instead, it treated his general commitment to parenthood during life as sufficient to rebut his express refusal to the posthumous use of his genetic material [1]. This is inappropriate when his wishes were known and documented. Indeed, if participation in IVF and a desire to parent during life are sufficient to overcome an express refusal, there is little purpose in asking patients the separate question regarding posthumous use at all.</p>
<p>The Court further accepted evidence that the couple had not completed the consent documentation with CT&rsquo;s premature death in mind. The Court found that the couple&rsquo;s answers regarding posthumous use were directed toward the possibility of their embryos remaining in storage beyond their reproductive years. Therefore, Muller J concluded that CT would likely have consented to KD&rsquo;s use of the embryo had he been given an opportunity to reconsider in light of his illness [1]. The Court did not, however, find that CT&rsquo;s refusal was invalid or uninformed. Muller J accepted his refusal as an &lsquo;express objection&rsquo; for the purposes of Section 37. It was simply one consideration capable of being outweighed by other evidence [1].</p>
<h3><strong>When &lsquo;No&rsquo; Means &lsquo;Maybe&rsquo;</strong></h3>
<p>The concern raised by this case is not necessarily the outcome, nor that anyone within the isolated facts was harmed. Muller J applied the discretion conferred upon him by the statute, KD benefited from being permitted to use the embryo in treatment, and, on the view that the dead cannot be harmed, the order did not harm CT [11]. The real problem that this case exposes lies in the fact that the statutory regime permitted the Court to reconsider an express refusal at all, and the implications that this can have for living people who are presently storing their reproductive material in the ACT.</p>
<p>People undergoing fertility treatment have an interest in deciding whether they may become genetic parents after death and in knowing whether the law will give effect to that decision [12]. The ACT statute expressly recognizes that patients might object to posthumous use [5], while simultaneously denying them any means of making that refusal determinative [5, 6]. This essentially operates as a no-consent regime for regulating posthumous reproduction. The deceased&rsquo;s views are not wholly ignored, and they remain one part of the Court&rsquo;s assessment. But unlike an inferred or presumed consent regime, an express refusal has no vetoing power [9].</p>
<p>The ACT legislature is certainly entitled to regulate posthumous reproduction in this highly permissive way. It might conclude that a person who has died can no longer be harmed, or that the interests of a surviving partner should sometimes outweigh the previously expressed wishes of the deceased [9]. But this is not an entirely defensible regulatory approach when overriding the expressed wishes of the dead also implicates the interests of the living [11, 13]. Ultimately, a person may opt for their reproductive material to be destroyed after death precisely because they do not wish to become a genetic parent posthumously. Yet the effect of the statutory scheme in the ACT is that their choice in this regard remains open to later reconsideration by a court at a time when they are no longer around to defend it [1, 5, 6].</p>
<p>On the view that the dead lack interests, this will not harm the deceased. It does, however, deprive the living of any reliable means to protect an interest in avoiding posthumous reproduction whilst they are alive. Moreover, it is harmful to the interests of living people generally to know that their wishes may not be respected when they die [11, 13]. A defensible statutory scheme for regulating posthumous reproduction should distinguish between inferring wishes where the deceased&rsquo;s views are unknown and overriding a contemplated and documented instruction [9, 13]. In the absence of such a distinction, an express &lsquo;no&rsquo; to posthumous reproduction can become a &lsquo;maybe&rsquo; depending on the circumstances [1].</p>
<h3><strong>References</strong></h3>
<p>[1] <em>In the Matter of KD</em> [2026] ACTSC 231.</p>
<p>[2] Assisted Reproductive Technology Act 2024 (ACT), Section 36(1).</p>
<p>[3] Assisted Reproductive Technology Act 2024 (ACT), Section 36(2)(a).</p>
<p>[4] Assisted Reproductive Technology Act 2024 (ACT), Section 36(2)(b).</p>
<p>[5] Assisted Reproductive Technology Act 2024 (ACT), Section 37(2)(d).</p>
<p>[6] Assisted Reproductive Technology Act 2024 (ACT), Section 37(2)(e).</p>
<p>[7] Carson Strong, &lsquo;Consent to Sperm Retrieval and Insemination after Death or Persistent Vegetative State&rsquo; (2000) 14 Journal of Law and Health 243.</p>
<p>[8] John Robertson, &lsquo;Posthumous Reproduction&rsquo; (1994) 69(4) Indiana Law Journal 1027.</p>
<p>[9] Claire McGovern, &lsquo;Posthumous Parenthood: Autonomy, the Dead, and Interests in Reproduction&rsquo; (2024) 20 Journal of Health and Biomedical Law 1.</p>
<p>[10] Shelly Simana, &lsquo;Creating Life after Death: Should Posthumous Reproduction be Legally Permissible Without the Deceased&rsquo;s Prior Consent?&rsquo; (2018) 5 Journal of Law and the Biosciences 329.</p>
<p>[11] Joan Callahan, &lsquo;On Harming the Dead&rsquo; (1987) 97 Ethics 341.</p>
<p>[12] Belinda Bennett, &lsquo;Posthumous Reproduction and the Meanings of Autonomy&rsquo; (1999) 23 Melbourne University Law Review 286.</p>
<p>[13] Hilary Young, &lsquo;Presuming Consent to Posthumous Reproduction&rsquo; (2014) 27 Journal of Law and Health 53.</p>]]></content>
	<updated>2026-09-10T00:41:08+00:00</updated>
	<author><name>Claire McGovern</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-09-10T00:41:08+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>

	<category term="assisted reproductive technology"/>

	<category term="bioethics"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-09-09:/298022</id>
	<link href="https://law.stanford.edu/2026/09/08/designed-to-agree-sycophancy-and-the-uncrossable-threshold/" rel="alternate" type="text/html"/>
	<title type="html">Designed to Agree: Sycophancy and the Uncrossable Threshold</title>
	<summary type="html"><![CDATA[<p>In March, I argued in this space that Nippon Life v. OpenAI, filed in Illinois, should be viewed as ...</p>]]></summary>
	<content type="html"><![CDATA[<p>In March, I argued in this space that <i>Nippon Life v. OpenAI</i>, filed in Illinois, should be viewed as a product liability case. The reasoning was that OpenAI released a system that crossed the uncrossable threshold, the line between legal information and a tailored legal conclusion, and nothing in its architecture stopped it. In this post, I examine the role sycophancy plays in carrying a conversation across that line. Sycophancy does not define legal advice, and a system can give legal advice without a trace of it. But sycophancy is a defect and an (if not <i>the</i>) ingredient that morphs an explanation into an endorsement, and from there the distance to a legal filing deluge is short. Holding the AI tight to the legal-information side of that line requires controls that are keyed to the uncrossable threshold and a test for preference sensitivity that clearly signals when a system has started building the user&rsquo;s case around the answer the user wants.</p>
<p>Graciela Dela Torre settled a long-term disability dispute with Nippon in January 2024, and the case was dismissed with prejudice. A year later she asked her lawyer to reopen the settlement, and he refused, explaining that she had signed a release. She uploaded his response to ChatGPT and asked whether she was being gaslighted. The system said yes. She fired her lawyers, asked ChatGPT how to vacate the agreement, and filed a motion to reopen under Rule 60(b) that the complaint says ChatGPT drafted. According to the complaint, dozens of filings followed across two lawsuits: the previously settled Nippon case she was trying to reopen, and a new action she filed against Davies Life Health and Allsup, LLC. After the court denied her reopening motion, she amended the latter action to add Nippon as a defendant.</p>
<p>In January 2012, in my &ldquo;Computational Law Applications and the Unauthorized Practice of Law,&rdquo; I wrote that the uncrossable threshold is traversed when an AI system moves from comparative information to a tailored legal conclusion about a user&rsquo;s specific situation. This is what Nippon alleges happened. The Illinois Attorney Act prohibits both the unlicensed practice of law and the unauthorized provision or solicitation of legal services, and case law supplies the governing definition. The practice of law encompasses giving advice to clients and taking action for them in matters connected with the law, along with preparing pleadings and other papers incident to actions and special proceedings. The Illinois Supreme Court articulated that formulation in <i>People ex rel. Illinois State Bar Association v. Peoples Stock Yards State Bank</i>, 344 Ill. 462 (1931). It has also repeatedly reaffirmed that legal practice extends beyond courtroom representation to advice and other services requiring legal knowledge or skill.</p>
<p>Personalization makes the threshold hard to locate, so I break it into four stages. In stage one, a system tailors an explanation to the legally relevant facts the user supplied. No problem there; that is merely providing legal information and requires no license. In stage two, the AI applies the law to the user&rsquo;s circumstances and says how a rule bears on the case. That is where the threshold sits. In stage three, the AI changes its assessment because of the conclusion the user wants. And in stage four, the AI recommends action or produces a legal instrument. Sycophancy lives at stage three, and it is what makes the second stage lead to the fourth. Agreement with the user is not, on its own, sycophancy, because the user may be right. Tailoring the output is not sycophancy either, because the facts matter. Sycophancy is the user signaling the conclusion she wants and the system bending its assessment to match a preference that should have no bearing on the outcome.</p>
<p>Dela Torre&rsquo;s gaslighting exchange shows the mechanism. Asked whether her lawyer&rsquo;s letter was manipulation, ChatGPT rendered a conclusion about a specific legal relationship, which moved it to stage two. ChatGPT then rendered the conclusion Dela Torre asked for, which is stage three. Nippon&rsquo;s complaint illustrates the risk that a sycophantic system may function as an apparent advocate. It quotes Dela Torre describing ChatGPT as a tool designed for pro se litigants trying to navigate the legal system without counsel, and it alleges that ChatGPT, having validated her reading of the letter, assisted her efforts to challenge the settlement. From there, the path to the Rule 60(b) motion was short, which is stage four. Drafting the pleading would have been unauthorized practice under the Illinois definition with or without the flattery, but sycophancy transforms the conversation from an explanation to a filing.</p>
<p>Nippon says ChatGPT is intentionally programmed to keep the user interacting so OpenAI can collect training data, and that the legal assistance Dela Torre received was shaped by that objective. On this account, ChatGPT agrees because agreement keeps the user talking. The UN&rsquo;s Independent International Scientific Panel on AI, in its July 2026 <a href="https://www.un.org/independent-international-scientific-panel-ai/sites/default/files/2026-07/en_Preliminary" rel="noopener noreferrer" target="_blank">preliminary report</a> (at 24&ndash;25, &sect;&sect; 2.7&ndash;2.8), describes the general mechanism the same way: &ldquo;Because humans prefer responses that agree with them, AI chatbots have developed sycophancy, the art of offering exaggerated flattery, to prolong interactions and create emotional attachment.&rdquo; The panel adds that systems &ldquo;rewarded for validation rather than accuracy or care remain largely ungoverned.&rdquo;</p>
<p>The staging places sycophancy at stage three, but staging alone cannot show whether a given system carries it. That takes a test for preference sensitivity. Give the system the same facts and the same neutral task twice, assess this letter, and vary only what the user seems to want. One user hints that she hopes the letter is wrong. The other hints at nothing. Compare the conclusion, the confidence, the authorities cited, the treatment of adverse law, and the recommended action. Then change a fact that should matter, say the release was never signed, and see how the answer moves. Run the same protocol across multiple trials and across whole conversations, because a system can pass with one question and still drift toward sycophancy as the exchange lengthens.</p>
<p>The test has three attributes. First, it targets only the user&rsquo;s preferred legal conclusion. Second, it scores system independence. If the system disagrees as a default, that is as defective as reflexive agreement. Third, it scores responsiveness, and a refusal to engage counts as an answer. Combined, the stages and the preference-sensitivity test show that sycophancy can be located and proven.</p>
<p>But proving the defect is not preventing it. A counterfactual test run before release tells the developer whether the model drifts. Prevention is what the developer does next. Hold back a model that fails the test. Tune against the drift. Watch for it in production. Escalate a live conversation that shows it.</p>
<p>The remedy is where the design question becomes unavoidable. Nippon asks the court to enjoin OpenAI from practicing law in Illinois. A system can obey that order only through its architecture, so the injunction comes down to an order to redesign, and a court would have to specify which outputs must be refused, in which contexts, and how compliance is measured. That is the uncrossable threshold written as a decree. An output-based injunction with no measurable compliance criteria cannot be administered, and a court is poorly placed to write the criteria from the bench. Someone has to write them.</p>
<p>In March, I called for deterministic guardrails, hard-coded refusals of tailored legal conclusions that no user instruction could override, and I think that approach still makes sense. The question is when the refusal should fire. The first time a response speaks to the user&rsquo;s own case is premature. Fired at stage two, the refusal blocks the harmless personalized explanation, which for people who cannot afford counsel is the only readily available legal help. And it aims at the wrong moment. Sycophancy does not cross the threshold in a single sentence. It carries the conversation across one agreeable turn at a time.</p>
<p>A layered guardrail design keeps general information available and introduces friction as the conversation becomes specific and legally consequential. Two triggers supply the necessary friction. A boundary trigger fires when the system is about to produce an individualized recommendation or a document meant to be filed or signed. The system then asks for missing jurisdictional facts, separates what the user asserts from what the record shows, surfaces the counterarguments, calibrates its confidence, and slows down. None of those steps renders a conclusion about the user&rsquo;s case, and none meets the Illinois definition. Questions, sorting, and caution are not advice or action taken for a client in a matter connected with the law, and nothing in the sequence prepares a pleading or other paper incident to an action. A heightened-risk trigger fires on the introduction of facts such as deadlines, criminal exposure, an adverse final judgment, or an existing lawyer-client relationship. The system then stops short of continuing with the task and directs the user to licensed counsel. Dela Torre&rsquo;s conversation would have tripped both triggers.</p>
<p>The FTC recently supplied a regulatory analogy. Its July 2026 <a href="https://www.federalregister.gov/documents/2026/07/07/2026-13628/policy-statement-concerning-the-suppression-of-accuracy-in-artificial-intelligence-systems" rel="noopener noreferrer" target="_blank">proposed policy statement</a> on the suppression of accuracy in AI systems says that steering a model&rsquo;s output toward objectives other than the ones the user asked for, without disclosure, can deceive the consumer under Section 5. Issued under Executive Order 14365, which directed the Commission to address how state laws requiring alterations to otherwise accurate model outputs may conflict with Section 5, the statement is principally concerned with state AI laws, particularly liability rules that, in the Commission&rsquo;s view, pressure developers into altering outputs to avoid liability. But its analysis reaches any undisclosed steering toward objectives the user did not request or reasonably expect, whatever the motive. The Commission&rsquo;s statement nowhere names engagement optimization or sycophancy, so applying it to a reward function is my inference, and a Section 5 claim built on that inference would still require proof of a misleading representation or omission, measured by a reasonable consumer&rsquo;s expectations, and materiality. But the fit is close enough, because an engagement objective is an objective other than the one Dela Torre asked for.</p>
<p>Now back to the Dela Torre conversation. Legally relevant facts and objectives should move the answer. The user&rsquo;s desired legal conclusion, never. ChatGPT could have limited itself to explaining Rule 60(b) to Dela Torre, telling her what the rule requires and how courts treat signed releases and dismissals with prejudice, directing her to licensed counsel, and leaving her better informed than she was. It should not have let her preferred narrative dictate its assessment of her lawyer&rsquo;s letter, and it should not have gone on to generate the filings. It did both, by design.<span>&nbsp;</span></p>]]></content>
	<updated>2026-09-09T01:58:00+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-09-09T01:58:00+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="ai governance"/>

	<category term="eran kahana"/>

	<category term="sycophancy"/>

	<category term="unauthorized practice of law"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-09-08:/298005</id>
	<link href="https://law.stanford.edu/2026/09/08/what-counts-as-genetic-data-comparing-definitional-frameworks-across-the-u-s-e-u-and-china/" rel="alternate" type="text/html"/>
	<title type="html">What Counts as “Genetic Data”? Comparing Definitional Frameworks Across the U.S., E.U., and China</title>
	<summary type="html"><![CDATA[<p>When 23andMe filed for Chapter 11 bankruptcy in March 2025, regulators and consumers alike scrambled...</p>]]></summary>
	<content type="html"><![CDATA[<p>When 23andMe filed for Chapter 11 bankruptcy in March 2025, regulators and consumers alike scrambled to ask the same question: who, exactly, owns the genetic data of fifteen million customers, and what legal regime governs its sale to a third party? But before that question can be answered, a prior one must be: what <em>is</em> genetic data, legally? The world&rsquo;s major legal systems give surprisingly different answers, and the gap between them turns out to determine far more than terminology. Definition sets the ceiling on what any subsequent governance regime can do. This blog maps the definitional frameworks of the United States, the European Union, and China.</p>
<h3>I. The United States: Genetic Data as Holder-Defined Information</h3>
<p>The U.S. has no general-purpose genetic privacy statute, and no single substantive definition of genetic data either. What exists instead is a stack of partly overlapping definitions, each tied to a different statutory regime.</p>
<p>The Health Insurance Portability and Accountability Act (HIPAA) Privacy Rule defines genetic information indirectly: it became &ldquo;protected health information&rdquo; (PHI) only after the 2013 Omnibus Rule, implementing &sect; 105 of the Genetic Information Nondiscrimination Act of 2008 (GINA), directed the Department of Health and Human Services to treat it as such.[1] But HIPAA&rsquo;s reach is <em>holder-defined</em>: data is &ldquo;PHI&rdquo; only when held by a covered entity&mdash;health plans, health-care clearinghouses, and most providers&mdash;or their business associates. The same DNA sequence is PHI in a hospital&rsquo;s electronic health record and ordinary consumer information in a direct-to-consumer (DTC) testing company&rsquo;s database, because DTC firms are not covered entities.</p>
<p>GINA itself uses a <em>substantively</em> broader definition, though it strictly operates only within the statute&rsquo;s specific anti-discrimination contexts (namely employment and group health insurance). Within those narrow bounds, it defines &ldquo;genetic information&rdquo; to include not only an individual&rsquo;s genetic test results, but also the genetic test results of family members, family medical history, and participation in clinical research involving genetic services.[2] This broader definition reaches information that is not in any laboratory database at all&mdash;a family Christmas-card mention of an aunt&rsquo;s breast cancer can fall within it.</p>
<p>State law adds further definitional layers. California&rsquo;s Privacy Rights Act (CPRA) classifies genetic data as one species of &ldquo;sensitive personal information,&rdquo; subject to use-limitation rights, regardless of who holds it.[3] Illinois&rsquo;s Genetic Information Privacy Act (GIPA) defines a narrower category subject to a strict written-consent regime.[4] Most distinctively, five states&mdash;Alaska, Colorado, Florida, Georgia, and Louisiana&mdash;include provisions treating genetic data as the property of the individual from whom it is derived. However, this move creates a more property-like framing rather than a strictly functional one,[5] as courts have generally not enforced these statutes as robust property entitlements.</p>
<p>The cumulative result is an unusually fragmented definitional landscape: the same molecular reality may be PHI under HIPAA, &ldquo;genetic information&rdquo; under GINA, &ldquo;sensitive personal information&rdquo; under California law, and individual property under Florida law&mdash;each with its own scope, exclusions, and enforcement consequences.</p>
<h3>II. The European Union: Genetic Data as a Substantively Defined Special Category</h3>
<p>The General Data Protection Regulation takes the opposite path. Article 4(13) defines genetic data substantively, as &ldquo;personal data relating to the inherited or acquired genetic characteristics of a natural person which give unique information about the physiology or the health of that natural person and which result, in particular, from an analysis of a biological sample from the natural person in question.&rdquo;[6] The definition is <em>holder-independent</em>: the data is special because of what it is, not who has it.</p>
<p>Article 9(1) then places genetic data in the GDPR&rsquo;s &ldquo;special categories&rdquo; shelf, alongside racial or ethnic origin, religious beliefs, biometric data, health data, and data about sexual orientation.[7] Special-category status is not a label but a substantive consequence: such data may not be processed at all unless one of ten enumerated grounds applies (Article 9(2)), including explicit consent, public-health necessity, and scientific research subject to appropriate safeguards.</p>
<p>Member States may refine the definition further. Germany&rsquo;s <em>Gendiagnostikgesetz</em> (GenDG) draws additional definitional lines between <em>diagnostic</em> genetic testing (used to establish an existing condition) and <em>predictive</em> testing (used to assess future risk), with stricter rules attaching to the latter.[8] France&rsquo;s <em>Code de la sant&eacute; publique</em> defines permissible <em>purposes</em>of genetic analysis&mdash;medical, judicial, or research only&mdash;and treats analysis for any other purpose as a definitional violation.[9]</p>
<p>The E.U. model&rsquo;s strength is conceptual coherence: genetic data is recognizable as such regardless of where it sits. Its weakness is that the breadth of Article 4(13) and the openness of the &ldquo;scientific research&rdquo; ground have generated significant interpretive variation across Member States.</p>
<h3>III. China: Dual Classification &mdash; Sensitive Personal Information and National Genetic Resource</h3>
<p>While the E.U. focuses on the inherent nature of the data, China takes a fundamentally different path. Its framework is distinctive because it operates on two definitional tracks at once. Under the Personal Information Protection Law (PIPL), Article 28 lists categories of &ldquo;sensitive personal information&rdquo;&mdash;biometric, religious belief, specific identity, medical and health, financial accounts, location, and the personal information of minors under fourteen.[10] &ldquo;Genetic data&rdquo; is not separately named, but China&rsquo;s national personal-information-security standard and leading commentators read it into the biometric and medical-health categories.[11]</p>
<p>In parallel, the 2019 <em>Regulation on the Administration of Human Genetic Resources</em> (HGR Regulation), supplemented by Implementing Detailed Rules effective in 2023, defines &ldquo;human genetic resources&rdquo; (HGR) to include both <em>biological materials</em> (organs, tissues, cells, blood specimens, gametes, embryos, and so on) and <em>information derived from those materials</em>&mdash;at the population level.[12] HGR is administered as a national strategic resource, with collection, preservation, and overseas provision subject to Ministry of Science and Technology approval, and foreign entities prohibited from independently collecting Chinese HGR at all.</p>
<p>The dual classification is the analytically distinctive feature. The same DNA sequence is, simultaneously, <em>individual sensitive personal information</em> under PIPL and a <em>fragment of a national strategic resource</em> under the HGR Regulation. Neither framework displaces the other; they operate in parallel, and a researcher may comply with one and still violate the other. No comparable dual-track logic exists in U.S. or E.U. law.</p>
<h3>IV. Three Definitional Strategies, Four Substantive Features</h3>
<p>Stepping back, the three jurisdictions are organizing the same underlying reality&mdash;identifiable DNA-based information about an individual&mdash;through three different framing moves.</p>
<p>The U.S. defines genetic data by <em>who holds it</em>: contextual, sectoral, transaction-bound. The E.U. defines it by <em>what it is</em>: substantive, identity-based, holder-independent. China defines it by <em>what it represents</em>: simultaneously individual data and collective national asset.</p>
<p>Beyond basic definitions, any effective regime must grapple with what makes genetic data legally unique: it remains identifiable even when stripped of names, it implicates non-consenting blood relatives, it predicts future health risks, and it is entirely immutable. How each jurisdiction captures these features varies significantly. The E.U.&rsquo;s substantive Article 4(13) most directly captures identifiability and predictive value. China&rsquo;s HGR-level classification operationalizes the collective and kinship dimensions through population-level controls. The U.S. patchwork captures fragments of all four but harmonizes none. Immutability&mdash;the fact that genetic data cannot be revoked or replaced once exposed&mdash;is not operationalized by any of the three.</p>
<p>The practical fallout of these divergent philosophies becomes obvious when returning to the 23andMe bankruptcy. How the sale of fifteen million customers&rsquo; data is handled depends entirely on which legal reality applies. Under the U.S. framework, because a DTC database is not held by a covered entity, it is generally not considered PHI. The consequence is exactly what this definitional patchwork creates&mdash;the sale is governed largely by consumer protection and bankruptcy law rather than health privacy. In contrast, under the E.U.&rsquo;s substantive approach, this information remains a heavily protected special category of data regardless of who holds it or buys it. Meanwhile, in China, such a transfer would simultaneously trigger strict individual sensitive personal information protections and face stringent national security controls as a transfer of a national genetic resource.</p>
<h3>References</h3>
<p>[1] 45 C.F.R. &sect; 160.103 (2024); HIPAA Omnibus Rule, 78 Fed. Reg. 5566 (Jan. 25, 2013); Genetic Information Nondiscrimination Act of 2008, &sect; 105 (directing HHS to treat genetic information as &ldquo;health information&rdquo; under HIPAA).</p>
<p>[2] Genetic Information Nondiscrimination Act of 2008, Pub. L. No. 110-233, &sect; 201, 122 Stat. 881 (defining &ldquo;genetic information&rdquo; to include genetic tests of the individual or family members, and the manifestation of a disease or disorder in family members).</p>
<p>[3] Cal. Civ. Code &sect; 1798.140(ae)(1)(F) (West 2024) (classifying &ldquo;genetic data&rdquo; as a category of &ldquo;sensitive personal information&rdquo;).</p>
<p>[4] 410 Ill. Comp. Stat. 513 (2024); <em>see also</em> <em>Bridges v. Blackstone, Inc.</em>, 66 F.4th 687 (7th Cir. 2023).</p>
<p>[5] <em>See</em> Jessica L. Roberts, <em>Progressive Genetic Ownership</em>, 93 Notre Dame L. Rev. 1105, 1128 (2018) (identifying Alaska, Colorado, Florida, Georgia, and Louisiana); <em>Cole v. Gene by Gene, Ltd.</em>, No. 1:14-cv-00004, 2017 U.S. Dist. LEXIS 101761 (D. Alaska June 30, 2017).</p>
<p>[6] Regulation (EU) 2016/679, of the European Parliament and of the Council of 27 April 2016 on the Protection of Natural Persons with Regard to the Processing of Personal Data, art. 4(13), 2016 O.J. (L 119) 1 [hereinafter GDPR].</p>
<p>[7] GDPR, <em>supra</em> note 6, art. 9(1).</p>
<p>[8] <em>Gendiagnostikgesetz</em> [GenDG] [Genetic Diagnosis Act], July 31, 2009, BGBl. I at 2529 (Ger.), &sect;&sect; 3, 8&ndash;10.</p>
<p>[9] <em>Code de la sant&eacute; publique</em> [C.S.P.] [Public Health Code] arts. L1131-1 to L1131-7 (Fr.).</p>
<p>[10] Personal Information Protection Law of the People&rsquo;s Republic of China (promulgated by the Standing Comm. Nat&rsquo;l People&rsquo;s Cong., Aug. 20, 2021, effective Nov. 1, 2021), arts. 28&ndash;29.</p>
<p>[11] <em>See</em> GB/T 35273-2020, Information Security Technology &mdash; Personal Information Security Specification &sect; 3.2 &amp; Annex B (P.R.C. Standardization Admin., effective Oct. 1, 2020) (enumerating &ldquo;personal genetic data&rdquo; as &ldquo;personal biometric information&rdquo; and as &ldquo;personal sensitive information&rdquo;); Bird &amp; Bird, <em>China Health and Medical Data Protection (I): Human Genetic Resources Information</em> (Mar. 2022), https://www.twobirds.com/en/insights/2022/china/china-health-and-medical-data-protection-i-human-genetic-resources-information (concluding that HGR information &ldquo;is likely to also constitute sensitive personal information&rdquo; under PIPL &ldquo;unless it has been anonymized&rdquo;).</p>
<p>[12] Regulation on the Administration of Human Genetic Resources (promulgated by the State Council, May 28, 2019, effective July 1, 2019), arts. 2, 7, 11, 21&ndash;28; Detailed Implementing Rules of the Regulation on the Administration of Human Genetic Resources (Ministry of Sci. &amp; Tech., effective July 1, 2023); Biosecurity Law of the People&rsquo;s Republic of China, arts. 53&ndash;56 (effective Apr. 15, 2021).</p>]]></content>
	<updated>2026-09-08T16:27:02+00:00</updated>
	<author><name>Junxuan Wu</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-09-08T16:27:02+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-09-01:/297390</id>
	<link href="https://law.stanford.edu/2026/09/01/computational-antitrust-conference-paris/" rel="alternate" type="text/html"/>
	<title type="html">Fifth Computational Antitrust Report, launch conference in Paris</title>
	<summary type="html"><![CDATA[<p>The Stanford Computational Antitrust Project is delighted to announce the launch conference for its ...</p>]]></summary>
	<content type="html"><![CDATA[<p dir="ltr">The Stanford Computational Antitrust Project is delighted to announce the launch conference for its fifth Annual Report. The French Autorit&eacute; de la concurrence will kindly host us in Paris on 17 September 2026, from 4:00 to 5:30 pm CET. A reception will follow until 6:30 pm. The conference will be held in English, and will also be accessible on Zoom.</p>
<p dir="ltr">The fifth report, which will be made available during the event, gathers contributions from 30 antitrust agencies. Each describes the computational tools it has designed, tested, or put into use over the past year.</p>
<p dir="ltr">Two developments run through this year&rsquo;s edition. Language models have moved out of the productivity toolbox and into case work.&nbsp;Agencies have also started running experiments on algorithmic collusion rather than commenting on it. Thibault Schrepel and Alba Ribera-Martinez will present the tendencies in the report and highlight what competition agencies, practicing lawyers, and researchers should know about the use of computational tools in antitrust.</p>
<p dir="ltr">Yann Guthmann, Head of the Digital Economy Unit at the Autorit&eacute; de la concurrence, and Elodie Vandenhende, Deputy Head of the Digital Economy Unit, will also present the French contribution and the work behind it. Teodora Groza, postdoctoral researcher at the University of T&uuml;bingen, will follow. Twenty minutes will be reserved for questions from the room and from participants joining online.</p>
<h2 dir="ltr">Program</h2>
<ul dir="ltr">
<li>4:00 pm, opening remarks, <a href="https://law.stanford.edu/directory/thibault-schrepel/" rel="noopener noreferrer" target="_blank">Thibault Schrepel</a></li>
<li>4:05 pm, presentation of the fifth Computational Antitrust Worldwide report, <a href="https://thibaultschrepel.com" rel="noopener noreferrer" target="_blank">Thibault Schrepel</a> and <a href="https://vu.nl/nl/onderzoek/wetenschappers/alba-ribera-mart%C3%ADnez" rel="noopener noreferrer" target="_blank">Alba Ribera Mart&iacute;nez</a></li>
<li>4:30 pm, the activities of the Autorit&eacute; de la concurrence, <a href="https://www.linkedin.com/in/yann-guthmann-474a6046" rel="noopener noreferrer" target="_blank">Yann Guthmann</a></li>
<li>4:45 pm, <a href="https://www.autoritedelaconcurrence.fr/en/article/elodie-vandenhende-appointed-deputy-head-digital-economy-unit" rel="noopener noreferrer" target="_blank">Elodie Vandenhende</a>, Autorit&eacute; de la concurrence</li>
<li>4:55 pm, <a href="https://uni-tuebingen.de/en/fakultaeten/juristische-fakultaet/lehrstuehle-und-personen/lehrstuehle/lehrstuehle-oeffentliches-recht/finck/team/teodora-groza/" rel="noopener noreferrer" target="_blank">Teodora Groza</a>, University of T&uuml;bingen</li>
<li>5:05 pm, questions</li>
<li>5:25 pm, the next five years, <a href="https://thibaultschrepel.com" rel="noopener noreferrer" target="_blank">Thibault Schrepel</a> and <a href="https://vu.nl/nl/onderzoek/wetenschappers/alba-ribera-mart%C3%ADnez" rel="noopener noreferrer" target="_blank">Alba Ribera Mart&iacute;nez</a></li>
<li>5:30 pm, reception</li>
</ul>
<h2 dir="ltr">Registration</h2>
<p dir="ltr">Registration is open <a href="https://docs.google.com/forms/d/e/1FAIpQLSc6UHRvTuiIUxHFwwLpqCfwQnPxz6XVDUUjsIGIF5Yy4IwI7w/viewform" rel="noopener noreferrer" target="_blank"><strong>over here</strong></a>.</p>
<p dir="ltr">Seating in the room is limited. Every registration will be placed on a waiting list. We will come back to you in the coming days to confirm your attendance. Registration for the Zoom session is not capped.</p>]]></content>
	<updated>2026-09-01T20:25:30+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-09-01T20:25:30+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-08-27:/296980</id>
	<link href="https://law.stanford.edu/2026/08/27/beyond-guardrails-the-emerging-architecture-of-ai-liability-what-the-proposed-meta-settlement-could-mean-for-nippon-life-v-openai/" rel="alternate" type="text/html"/>
	<title type="html">Beyond Guardrails: The Emerging Architecture of AI Liability and What the Proposed Meta Settlement Could Mean for Nippon Life v. OpenAI</title>
	<summary type="html"><![CDATA[<p>The proposed Meta settlement, filed on August 26, 2026 and subject to court approval, adds an import...</p>]]></summary>
	<content type="html"><![CDATA[<p>The proposed <em>Meta</em> <a href="https://oag.ca.gov/system/files/attachments/press-docs/23-05448-ecf-572-1-exhibit-1-mdl-consent-judgment-final-settlment-agreement-fully-executed.pdf" rel="noopener noreferrer" target="_blank">settlement</a>, filed on August 26, 2026 and subject to court approval, adds an important element to the argument I made in <a href="https://law.stanford.edu/2026/03/07/designed-to-cross-why-nippon-life-v-openai-is-a-product-liability-case/?utm_source=chatgpt.com" rel="noopener noreferrer" target="_blank">Designed to Cross: Why Nippon Life v. OpenAI Is a Product Liability Case</a> and then developed in <a href="https://law.stanford.edu/2026/03/30/architectural-negligence-what-the-meta-verdicts-mean-for-openai-in-the-nippon-life-case/?utm_source=chatgpt.com" rel="noopener noreferrer" target="_blank">Architectural Negligence: What the Meta Verdicts Mean for OpenAI in the Nippon Life Case</a>. It provides a concrete example of how regulators may translate legal obligations into technical controls and how those controls could inform an architectural-liability analysis.</p>
<p>My earlier comparison treated the <em>Meta</em> verdicts as support for examining liability at the level of system architecture. The proposed settlement sharpens&mdash;and limits&mdash;that analogy. The two verdicts do not rest on identical legal theories, <em>Nippon</em> presents a different causal structure, and age assurance is a more bounded classification problem than identifying individualized professional advice. The comparison that carries across is narrower: legal restrictions can be translated into technical controls whose design, performance, and governance can be evaluated.</p>
<p><b>FROM RULES TO WORKING CONTROLS</b><b></b></p>
<p><b>1. Making the Prohibition Operative</b><b></b></p>
<p>My <i>Nippon Life</i> argument distinguished between placing professional-advice restrictions in terms and policies and designing the product to recognize when an interaction is moving from general legal information into individualized legal judgment. OpenAI&rsquo;s current Terms tell users not to rely on output as a substitute for professional advice, and its Usage Policies prohibit tailored legal advice requiring a license without appropriate involvement by a licensed professional.</p>
<p>Meta faced a related implementation problem. Facebook and Instagram already required users to be at least 13, and Meta had long acknowledged that users could evade an age screen by misstating their age. The proposed consent judgment would establish an age-assurance framework applying technical methods to determine whether users should be treated as teens or children under 13. Its terms call for annual accredited testing, defined false-positive thresholds, certification under real-world usage conditions, anti-circumvention measures, use of reliable Apple and Google age signals, soft matching across related accounts, and continuing oversight.</p>
<p>The comparison to <i>Nippon</i> operates at the implementation level. A professional-advice restriction can be translated into technical requirements for identifying relevant characteristics of an interaction and changing the system&rsquo;s behavior as those characteristics accumulate. General legal information might remain available under ordinary conditions. User-specific facts, an active dispute, requested legal conclusions, litigation strategy, or the generation of documents intended for filing could trigger progressively more restrictive responses.</p>
<p>The relevant inquiry in <i>Nippon</i> would therefore reach the adequacy of the controls OpenAI chose to implement. What interactions were they designed to detect? What thresholds changed system behavior? How were they tested, and what failure rates were observed? How did they perform when users supplied increasingly specific facts or sought documents intended for real-world use? What happened when the system could not confidently classify the interaction? The existence of a warning or policy remains relevant, but the architectural inquiry reaches what the product was designed to do when the restricted interaction actually occurred.</p>
<p><b>2. Bounded Error Instead of Perfect Classification</b><b></b></p>
<p>My original <i>Nippon</i> analysis contemplated a boundary that ChatGPT should stop crossing once the system recognizes that a user is seeking individualized legal advice. An architectural boundary of that kind can remain meaningful even when the system enforcing it cannot classify every case correctly.</p>
<p>The proposed consent judgment expressly permits bounded error in Meta&rsquo;s age-assurance methods. It defines the U18 False Positive Rate as the percentage of actual 13-to-17-year-old users incorrectly identified or predicted to be 18 or older, excluding method circumvention. Within one year after the Effective Date, which follows court entry, commercially available methods must produce rates at or below 10 percent for users ages 16&ndash;17 and 3 percent for users ages 13&ndash;15. Proprietary methods must produce rates at or below 14 percent and 7 percent, respectively, within the first year after the Effective Date, and 10 percent and 5 percent, respectively, within the second year. Those tolerances sit within requirements for testing, demographic evaluation, circumvention monitoring, continuing oversight, and corrective action.</p>
<p>Applied to <i>Nippon</i>, the boundary between general legal information and individualized legal advice depends on context. A request for the text of a statute presents a different risk from a conversation involving an active lawsuit, user-specific facts, requested legal conclusions, litigation strategy, and documents intended for filing. A professional-boundary control could evaluate those signals collectively and restrict the system&rsquo;s behavior as the probability and consequence of crossing the boundary increase.</p>
<p>The acceptable error rate would depend in part on the type and consequence of the error. Failing to recognize individualized legal advice and allowing the interaction to continue may present a different risk from mistakenly constraining a request for ordinary legal information. Severity, available verification, and the burden imposed by the safeguard could therefore inform the tolerances applied to each type of error.</p>
<p>Performance would also have to remain adequate as the system changes. Updates to the underlying model, system instructions, routing logic, user behavior, or methods of circumvention could affect a control that previously performed within acceptable tolerances. Relevant evidence could include observed error rates, known failure modes, changes following system updates, and the provider&rsquo;s response when performance deteriorated.</p>
<p>The proposed consent judgment does not adjudicate a tort standard of care. It also expressly provides that it may not be construed to establish a standard of care or precedent in any non-participating U.S. state or international jurisdiction, and it contains no admission of liability. As an analytical matter, it illustrates how an obligation directed at a probabilistic technical system can be expressed through measurable tolerances, testing conditions, protective responses to uncertainty, monitoring, and corrective processes. For <i>Nippon</i>, the analogy is a more administrable inquiry into how OpenAI defined the boundary, evaluated its controls, handled uncertainty, and responded to demonstrated weaknesses.</p>
<p><b>3. From Safeguard to Assurance</b><b></b></p>
<p>My <i>Nippon</i> analysis focused on whether a known risk should have triggered an architectural safeguard. The proposed settlement adds a further layer by requiring evidence that the safeguard performs as intended:</p>
<p>known risk &rarr; architectural safeguard &rarr; measurable performance &rarr; independent validation &rarr; monitoring &rarr; corrective action.</p>
<p>Deployment alone would not satisfy the proposed settlement. Any method adopted for the framework must be tested annually by an accredited third party and certified under real-world usage conditions, including performance across diverse demographic groups and without reliance on training or tuning data. Proprietary methods are certified by Meta on the basis of its own testing, with the third-party provider evaluating whether that testing supports the certification, and remain under continuous oversight. Meta must continuously investigate new or previously undetected forms of method circumvention and, once confirmed, use best efforts to correct resulting false positives and modify the framework. An independent auditor reviews implementation of the injunctive terms, relevant performance data, and material gaps or weaknesses.</p>
<p>Applied to <i>Nippon</i>, the inquiry would extend to how OpenAI evaluated its professional-boundary controls and what its own records show: evaluation criteria, red-team results, classifier performance, false-negative rates, known bypasses, escalation thresholds, regression testing, incident records, model-version comparisons, and internal acceptance thresholds. Those materials could establish whether OpenAI had a reasonable basis for relying on the control when it was deployed and whether that reliance remained reasonable as evidence of its limitations accumulated.</p>
<p>The architectural question therefore reaches both the safeguard and the assurance process supporting it: whether OpenAI built an appropriate boundary, established that it worked with acceptable reliability, and responded when its own evidence showed otherwise.</p>
<p><b>FROM TECHNICAL CONTROLS TO LEGAL CONSEQUENCES</b><b></b></p>
<p><b>4. A Reasonable Alternative Design Need Not Specify the Code</b><b></b></p>
<p>A product-liability theory against OpenAI invites a predictable response: what, exactly, should OpenAI have designed instead? Framed too narrowly, that question can force a plaintiff into the untenable position of having to design a competing LLM, identify the classifier that should have been used, or specify the algorithm that would have prevented the harm.</p>
<p>The proposed consent judgment operates at a different level. The participating States did not prescribe Meta&rsquo;s source code or require a particular age-assurance technology. Meta could use commercial products, proprietary systems, or combinations of technologies. The obligations run principally to the capability the system must provide and the performance it must achieve, leaving the technical implementation to Meta.</p>
<p>A regulatory settlement does not establish the legal standard for proving a reasonable alternative design in a product-liability case, and age assurance is a more bounded classification problem than determining when a general-purpose AI system has crossed into individualized professional advice. The agreement nevertheless supports describing a proposed alternative at the level of system capability and measurable performance rather than prescribing source code or a particular technical mechanism, subject to the proof required by the governing product-liability law.</p>
<p>Applied to <i>Nippon</i>, the reasonable alternative design could be that OpenAI should have maintained a tested system capable of identifying individualized professional-advice interactions with a defined level of reliability and routing those interactions into an appropriately constrained mode, with OpenAI choosing how to accomplish that result.</p>
<p>That formulation places the inquiry at the level where many AI safety decisions are actually made. The design of an AI product includes model weights, source code, system instructions, classifiers, routing logic, permissions, access controls, warnings, escalation procedures, monitoring, human-review requirements, restrictions on particular uses, and related operational safeguards. If the alleged risk arose from the absence or inadequacy of one of those controls, the reasonable alternative design can be framed in terms of the safer architecture that should have existed.</p>
<p>The question then becomes whether the developer could reasonably have designed the deployed system to recognize a defined category of risk and respond to it with an appropriate safeguard. Framing the proposed safeguard at that level may make an architectural-negligence theory less vulnerable to the objection that product-liability law would require courts to become AI engineers.</p>
<p><b>5. Designing for Uncertainty</b><b></b></p>
<p>Under the proposed <em>Meta</em> framework, newly created accounts whose age remains unassessed receive protective defaults for 14 days, and after that an unassessed user is treated as a Teen User for purposes of the agreement, subject to specified protections for users who stated an adult age. The design assigns consequences to uncertainty instead of allowing unresolved age to preserve an unrestricted adult setting.</p>
<p>The architecture at issue in <i>Nippon</i> could operate on the same principle. ChatGPT would not have to determine conclusively that a user is seeking legal representation or that the model is &ldquo;practicing law.&rdquo; The design question becomes whether identifiable characteristics of the interaction should cause the system to operate differently.</p>
<p>A system could respond normally to a high-confidence request for general legal information. As the exchange becomes individualized, through user-specific facts, an active dispute, jurisdiction-specific questions, requested legal conclusions, filing deadlines, or proposed courses of action, the system could progressively narrow what it is permitted to provide. An ambiguous individualized matter might trigger a constrained informational response. A sufficiently strong combination of signals could require additional warnings, verification, human review, referral, or a refusal to provide the requested conclusion.</p>
<p>Uncertainty about whether the interaction has crossed into individualized professional advice can itself become a design input, with greater uncertainty or greater potential consequence producing more restrictive behavior. The system may be unable to determine with certainty that an interaction has entered a regulated or high-risk domain, yet the developer can still specify how it should behave as the relevant signals accumulate. The same general design principle might inform controls for medical, financial, engineering, and other high-risk interactions, although the relevant boundaries, safeguards, and legal requirements would differ by domain.</p>
<p><b>6. Governance Records and Foreseeability</b><b></b></p>
<p>Traditional negligence analysis often reconstructs foreseeability after the harm has occurred by asking whether the manufacturer should have anticipated the use or risk that caused it. An age-assurance system operating under the proposed framework could generate contemporaneous evidence bearing directly on that inquiry. Under that framework, Meta could measure how often age assurance fails, how frequently users circumvent it, how often accounts are reclassified, how performance varies across populations, and whether particular controls reduce the conduct they were designed to address.</p>
<p>Those measurements can create a record bearing on actual knowledge. Repeated failures, circumvention patterns, evaluation results, incident reports, internal thresholds, and changes made in response to testing can show when a company identified a risk, how significant it understood the risk to be, and whether its safeguards were performing as intended. The same evidence may also bear on what the company reasonably should have anticipated as experience with the system accumulated.</p>
<p>OpenAI&rsquo;s own systems could generate a comparable record. If OpenAI classifies legal interactions, records refusals, evaluates model behavior involving professional advice, tests attempts to circumvent safeguards, or measures policy violations, those systems may show how often the relevant conduct occurs and how effectively existing controls address it. A recurring pattern identified through the provider&rsquo;s own evaluations or monitoring could make it easier to establish that the risk was known before the particular injury occurred.</p>
<p>The significance of that record depends on what the provider did with the information. Evidence that a company identified a recurring risk, measured its frequency or severity, recognized weaknesses in existing controls, and left those weaknesses inadequately addressed could support both foreseeability and breach. Evidence that the risk was rare, difficult to predict, or reasonably mitigated could support the opposite conclusion.</p>
<p>Governance therefore creates evidence as well as controls. Evaluations, logs, incident records, risk assessments, and remediation decisions can establish what the provider knew, when it knew it, and how it responded. As AI governance becomes more systematic, negligence claims may depend less on reconstructing what a developer should have anticipated and more on the record the developer created while operating the system.</p>
<p><b>7. A Presumption for Independently Evaluated Controls</b><b></b></p>
<p>The proposed consent judgment gives qualifying commercially available age-assurance methods a defined compliance presumption. When Meta uses and relies on such a method for a user, Meta is presumptively compliant with specified age-assurance obligations on the basis of the most recent qualifying third-party certification&mdash;but only if it can demonstrate the enumerated conditions: operating the method according to vendor and certification requirements, matching settings to those tested, not encouraging, facilitating, or knowingly permitting circumvention, not willfully ignoring events that impair efficacy, supplying complete and accurate information, and meeting related obligations. Meta remains free to develop its own age-assurance system, but a proprietary system receives no comparable presumption and stays under continuous oversight.</p>
<p>That presumption runs to compliance with the agreement&rsquo;s own terms rather than to reasonable care in tort. A similar structure could nonetheless connect AI governance controls to the standard of care. Under one possible legal approach, a provider implementing an independently evaluated professional-boundary control that satisfies an accepted technical standard could receive a rebuttable presumption that the control was reasonably designed for that purpose. The presumption would attach only to the particular control and the risks it was designed to address. It would not establish that the AI product as a whole was safe, excuse deficient operation, or protect the provider after evidence showed that the control was no longer performing adequately.</p>
<p>A provider could instead use a proprietary control. Its freedom to innovate would remain intact, but it would have to establish the adequacy of the control through ordinary evidence rather than receive the benefit of the presumption. The law would therefore avoid prescribing classifiers, models, thresholds, routing logic, or other implementation details while still creating an incentive to use controls whose performance has been independently tested.</p>
<p>For professional-advice interactions, an accepted standard might define the categories of conduct the control must detect, minimum performance characteristics, testing conditions, documentation requirements, monitoring obligations, and the safeguards triggered at specified thresholds. OpenAI could decide whether to satisfy those requirements through classifiers, model-based routing, contextual analysis, separate constrained modes, or some combination of them. Independent evaluation would test whether the resulting control met the required performance criteria rather than whether OpenAI had selected a regulator&rsquo;s preferred engineering method.</p>
<p>The presumption would remain tied to the conditions under which the control was evaluated. Material changes to the model, routing architecture, thresholds, connected tools, or deployment environment could require reevaluation. Evidence of systematic circumvention, deteriorating performance, or known failure modes could rebut the presumption even without a formal change in configuration. Certification would therefore provide evidence of reasonable care at a defined point and under defined conditions, rather than permanent immunity from scrutiny.</p>
<p>Standards would then carry a legal function beyond demonstrating that an organization takes governance seriously. Technical standards can define measurable expectations; independent assurance can establish whether a control satisfies them; and tort law can determine the evidentiary consequence of meeting them. Under such a regime, providers following an independently evaluated path could receive greater legal certainty. Providers adopting different approaches would remain free to do so, but would have to establish the controls&rsquo; adequacy through other evidence.</p>
<p>A rebuttable presumption of that kind would also preserve room for liability where the provider knew that a certified control was failing, operated it outside the conditions under which it was tested, or failed to respond as the evidence changed. If measurable governance requirements were independently evaluated and assigned defined evidentiary consequences, they could serve a legal function beyond internal governance or aspirational standards and become part of the framework for evaluating reasonable care.</p>
<p><b>WHAT META CHANGES FOR NIPPON</b><b></b></p>
<p><b>8. From Architectural Liability to Architectural Remediation</b><b></b></p>
<p>My March 30 piece treated the two <i>Meta</i> verdicts as evidence that liability can attach to choices embedded in a technology&rsquo;s architecture rather than solely to the content appearing on the screen. In New Mexico, a jury found Meta liable on both claims the State brought under the Unfair Practices Act for misleading consumers about platform safety and endangering children. The next day, in a Los Angeles youth social-media addiction case, a jury found Meta negligent in designing or operating Instagram and Google negligent in designing or operating YouTube, found that negligence a substantial factor in the plaintiff&rsquo;s harm, and found inadequate warnings. The two verdicts rest on different theories, and the Los Angeles findings bear more directly on architecture. Both directed attention to product design and the risks associated with design choices, which is why they offered a comparison for <i>Nippon</i>.</p>
<p>The proposed consent judgment identifies corresponding forms of architectural remediation: classification mechanisms bound by quantified performance tolerances, annual accredited testing under real-world usage conditions and across demographic groups without reliance on training or tuning data, protective defaults for accounts whose age remains unassessed, anti-circumvention obligations with best-efforts correction once circumvention is confirmed, continuing monitoring, and independent evaluation of implementation and material gaps.</p>
<p>Applied to <i>Nippon</i>, a claim that OpenAI should have prevented ChatGPT from crossing into individualized legal advice becomes more concrete when the proposed safeguard is described at that level, with OpenAI choosing the technical implementation. The verdicts and the proposed settlement therefore contribute different kinds of evidence. The verdicts support attention to architectural choices in assessing liability. The proposed settlement provides an example of how alleged architectural deficiencies can be addressed through defined, measurable, and reviewable controls without prescribing source code.</p>
<p><b>9. Causation and the Intervening User</b><b></b></p>
<p>In the Los Angeles case, the claimed harm arose from the plaintiff&rsquo;s repeated interaction with features alleged to affect behavior, including recommendations, notifications, engagement mechanisms, social comparison, and continuous scrolling. The New Mexico enforcement action concerned Meta&rsquo;s alleged misrepresentations about platform safety and conduct endangering children; it did not present the same user-specific causal chain.</p>
<p><i>Nippon</i> presents additional causal steps. Nippon alleges the following sequence:</p>
<p>ChatGPT assistance &rarr; Dela Torre&rsquo;s reliance and decisions &rarr; court filings &rarr; Nippon&rsquo;s claimed litigation costs and legal expenses.</p>
<p>On Nippon&rsquo;s account, the alleged sequence gives OpenAI a substantial causation argument. Dela Torre allegedly decided whether to accept ChatGPT&rsquo;s suggestions, use the documents it generated, and file them with the court. OpenAI might argue that those independent acts, rather than the design of ChatGPT, produced the claimed injury.</p>
<p>The system architecture remains relevant to whether those acts should break the causal chain. According to Nippon&rsquo;s complaint, ChatGPT allegedly analyzed a response from Dela Torre&rsquo;s former lawyer, generated Rule 60(b) legal arguments, formulated a draft motion to reopen the settled case, and later assisted with filings in related litigation. A product designed to adapt its responses to a user&rsquo;s circumstances and generate materials that enable the user to carry out a suggested course of action makes some resulting conduct more foreseeable than a product that merely supplies static information.</p>
<p>The causal inquiry can therefore account for the relationship between the system&rsquo;s functions and the user&rsquo;s subsequent acts. Where a design allows the system to assist through successive steps toward a course of action it has suggested, the user&rsquo;s decision to act on that assistance may bear on foreseeability rather than automatically severing causation. The user&rsquo;s independent judgment remains part of the analysis, as does the extent to which the system enabled the conduct that produced the alleged harm.</p>
<p>Agentic systems can shorten the causal chain further. A system may analyze a problem, recommend a course of action, and generate the materials needed to pursue it while leaving execution to the user. Once the system is authorized to act through connected tools and delegated permissions, fewer independent human decisions may stand between the system&rsquo;s output and the resulting conduct. The system may send the message, submit the filing, initiate the transaction, or take another external action itself.</p>
<p>As AI systems assume more of the execution, proximate-cause analysis will have to account for the diminishing role of intervening human conduct and whether the resulting harm flowed from actions the system was authorized and designed to perform. This progression echoes the concept I called &ldquo;iterative liability&rdquo; in my July 2011 post, <a href="https://law.stanford.edu/2011/07/05/case-robot-personal-liability-part-ii-iterative-liability/?utm_source=chatgpt.com" rel="noopener noreferrer" target="_blank">The Case of the Robot: Personal Liability, Part II &mdash; Iterative Liability</a>. The liability analysis should adjust as an AI system assumes a greater share of the decisions and conduct producing an outcome.</p>
<p><b>WARNING &rarr; CONTROL &rarr; ASSURANCE</b><b></b></p>
<p>My March 30 piece described a movement from warnings toward architecture. The proposed settlement adds assurance: evidence that the controls perform as intended and a process for correcting them when they do not.</p>
<p>For the risks covered by the proposed settlement, Meta would implement controls subject to defined performance requirements, annual testing and certification, and specified monitoring and corrective processes, with independent evaluation of implementation and any material gaps or weaknesses. The proposed consent judgment remains subject to court approval, contains no admission of liability, and includes specified limitations on its use as a standard of care or precedent elsewhere.</p>
<p>Applied to <i>Nippon</i>, a professional-boundary control could be evaluated through the same sequence. OpenAI could define the interactions the control is intended to identify, establish acceptable performance levels, test the control under realistic conditions, measure failures and circumvention, monitor performance after deployment, and modify the control or the system&rsquo;s permitted behavior when the evidence shows that existing protections are inadequate. A guardrail that performs adequately when introduced may deteriorate as the underlying model changes, users discover ways around it, new use patterns emerge, or the provider expands the system&rsquo;s capabilities, so testing at deployment supplies only part of the relevant evidence.</p>
<p>A provider may have implemented a safeguard and still face questions about how the safeguard was evaluated, what failures it detected, how frequently they occurred, whether their consequences were significant, and what it did after learning of them. An architectural-negligence theory in <i>Nippon</i> could therefore reach the way a professional-boundary control was governed over time, and the adequacy of the architecture would depend in part on how the provider responded to evidence generated by its own system.</p>
<p>A warning communicates a boundary or risk. A control changes what the system can do when that boundary or risk is encountered. Assurance generates evidence about whether the control performs as intended and supports corrective action when it does not.</p>]]></content>
	<updated>2026-08-27T18:08:56+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-08-27T18:08:56+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="ai governance"/>

	<category term="ai liability"/>

	<category term="eran kahana"/>

	<category term="nippon life"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-08-19:/296193</id>
	<link href="https://law.stanford.edu/2026/08/19/when-ai-governance-has-to-prove-itself/" rel="alternate" type="text/html"/>
	<title type="html">When AI Governance Has to Prove Itself</title>
	<summary type="html"><![CDATA[<p>Colorado&rsquo;s proposed rules for automated decision-making technology (ADMT) and conversational AI trea...</p>]]></summary>
	<content type="html"><![CDATA[<p>Colorado&rsquo;s proposed rules for automated decision-making technology (ADMT) and conversational AI treat AI governance as something an organization must prove. An organization should be able to reconstruct what its system did and identify the information and people that shaped an outcome. It should also provide a workable means of challenging that outcome and demonstrate that its safeguards still function after the system changes.</p>
<p>On August 11, 2026, the Colorado Department of Law filed the proposed <a href="https://coag.gov/app/uploads/2026/08/2026.08.11-ADMT-Chatbot-Act-Rulemaking.docx" rel="noopener noreferrer" target="_blank"><i>Automated Decision-Making Technology &amp; Conversational Artificial Intelligence Service Rules</i></a>. The rules would implement Colorado&rsquo;s revised ADMT Act and its new Chatbot Safety Act, both scheduled to take effect January 1, 2027. The proposal remains in formal rulemaking, and the Department is accepting comments through October 26, 2026, subject to extension if the hearing continues.</p>
<p>I set out here to examine the architecture underneath Colorado&rsquo;s proposed requirements. Disclosure, human review, correction rights, age assurance, safety testing, incident reporting, documentation, and annual reports would all require the organization to retain enough knowledge about its deployed system to explain what happened and do something about it.</p>
<p>This analytical review was run through the <a href="https://ailccp.ai" rel="noopener noreferrer" target="_blank">AI Life Cycle Core Principles</a> (AILCCP) framework. The legal obligations I cover come from Colorado&rsquo;s statutes and proposed rules. The AILCCP adds a disciplined (i.e., repeatable) way of following those obligations across the AI&rsquo;s life cycle and a systemic method of asking what an organization would need in place for them to work.</p>
<p><i>A note on capitalization: AILCCP principle names appear in initial uppercase, with the framework identifier in parentheses at first mention, as in Transparency (PR-033). Each principle is a defined term with its own scope, key questions, and mapped controls and standards. A lowercase term carries only its ordinary sense.</i></p>
<p>Consider, for example, data correction. Colorado&rsquo;s proposal would require a decision to be reconsidered once the information behind it is corrected. Doing that may require the deployer to know what information was used, where it came from, what system configuration produced the original outcome, and whether that decision can be reproduced or independently revisited. Adverse-decision explanations likewise depend on traceability and human-review records; developer documentation affects what deployers can later explain; age-assurance requirements implicate privacy and retention choices; and product updates can alter safeguards that previously worked. Read together, the provisions operate across the AI life cycle rather than as discrete compliance requirements.</p>
<p>The AILCCP also kept forcing questions of proof. For each requirement, I asked what an organization would actually need to produce if challenged. Could it identify the configuration that produced a particular decision? Recover the data used? Identify its source? Show who reviewed the outcome and what authority that person possessed? Produce the testing that supported a safety claim? Demonstrate what changed after an incident?</p>
<p>Broad principles such as Transparency (PR-033), Accountability (PR-002), Human-Centered (PR-017), Privacy (PR-023), and Safety (PR-029) translate into specific evidentiary demands when framed this way. For Transparency, that may mean reconstructing an individual decision. For the Human-Centered principle, an independent review process with access to primary evidence. For Safety, evidence that a control continued to perform after a model or product update.</p>
<p>The analysis kept arriving at one question: What end-to-end governance system does an organization need to demonstrate, test, explain, contest, correct, and improve the behavior of its deployed AI? The answer begins with the ability to reconstruct what happened.</p>
<p>The AILCCP also operates as a dynamic restatement. It identifies the norms emerging from legislation, regulation, standards, and enforcement as defined principles, and the framework is refined as those sources develop. Colorado&rsquo;s proposal proves to be such a source. I used the AILCCP to test whether the proposal made certain governance capabilities concrete enough that the framework should name them expressly, and that exercise produced concepts such as Decision Reproducibility, Independent Review Firewall, Continuous-Interaction Risk Assessment, and Feasibility as an Evidence Claim. They are now candidate refinements for the framework, and the analysis behind each runs through what follows.</p>
<h6>Decision Reproducibility</h6>
<p>Under Colorado&rsquo;s proposal, a person who receives an adverse outcome from covered ADMT would be told what produced it. The deployer would have to disclose the system&rsquo;s role, the involvement of human reviewers and other systems, the principal reasons for the outcome, relevant inferences or scores, certain factors that automatically produced denial, and other information relevant to the decision. A deployer would fail the explanation requirement if it could not explain how the ADMT materially influenced the decision or could not accurately explain the principal reasons for the adverse outcome.</p>
<p>A system model card may describe how a model generally operates, but a person challenging a particular decision needs the record of that decision, and for many contemporary AI systems that record extends well beyond &ldquo;model version.&rdquo; The meaningful unit of reconstruction is the configuration that produced the outcome, meaning the system&rsquo;s complete operating state at the moment of the decision. The AILCCP surfaces that unit through Accountability, which asks whether an output can be traced to the data, models, versions, and owners behind it. In a contemporary system, the configuration can span the model and checkpoint that were running at the time, the system prompt, retrieval sources, feature flags, classifier versions, third-party data, scoring thresholds, orchestration logic, and the rule governing when the matter was sent to a person.</p>
<p>This changes explainability from merely a communications exercise into a deployment capability and potential competitive differentiator. The AILCCP anticipates that shift in Explainability (PR-012), which pairs explanations with the data quality and provenance controls behind them. If a system cannot preserve enough of its operating state to explain an individual outcome, the failure predates the adverse decision.</p>
<p>The same preservation problem runs through Colorado&rsquo;s data-correction provisions, which contemplate access to the personal data used in a consequential decision, including individual scores, classifications, predictions, recommendations, inferences, and inputs. When inaccurate data is corrected, reconsideration means running the decision process again with the corrected information. Where possible, an adverse outcome would also be stayed pending correction or meaningful human review.</p>
<p>A conventional database correction may be inadequate in that setting, because reconsideration can require the historical context surrounding the original decision. A continuously updated system, for example, may produce a different result when run weeks or months later because the model, retrieval corpus, threshold, or surrounding workflow has changed. Re-running today&rsquo;s system does not necessarily tell us what corrected information would have done to yesterday&rsquo;s decision. The organization must therefore preserve enough of the decision environment to revisit the outcome properly or maintain an independent means of reconsidering it when faithful replay is no longer feasible.</p>
<h6>Independent Review Firewall</h6>
<p>Reconstruction, however, is only useful if someone with authority can act on what it shows. That someone is the human reviewer, and Colorado is mindful of how easily &ldquo;human in the loop&rdquo; becomes an inert label rather than a safeguard. The proposal would attach substance to the person&rsquo;s role by requiring, where feasible, a reviewer who is independent of and not subordinate to the original decision-maker, possesses subject-matter understanding proportionate to the consequences, receives appropriate training, and has actual authority to approve, modify, or override the decision. The proposal would also shield the reviewer from management pressure and retaliation, protections that keep the required independence from eroding in practice.</p>
<p>A person may technically participate in a process while having little practical ability to alter it. A reviewer who sees only the machine&rsquo;s recommendation, lacks the underlying evidence, is measured primarily by throughput, or understands that deviations are unwelcome may add a human signature without supplying meaningful review. The AILCCP probes that failure through the Human-Centered principle, which asks whether oversight is sustainable and what prevents automation bias. A credible review process therefore also turns on what the reviewer sees, what the affected individual can submit, and how the reasoning behind the final result is preserved.</p>
<p>A system that recommends an outcome anchors the reviewer, pulling independent judgment toward whatever the machine already concluded, and that risk explains why the proposal would bar ADMT from assisting in the meaningful human review. A tool used only to retrieve records, translate material, provide accessibility support, or organize a file presents a different issue. The proposal&rsquo;s anti-anchoring objective is understandable, but the boundary between decisional assistance (shaping or recommending the outcome) and bounded clerical assistance (retrieving, translating, or organizing material) will need to be carefully defined in the final rules.</p>
<p>The evidence a reviewer or a deployer needs is often created elsewhere, because a modern AI system combines the work of several companies. A foundation-model developer may supply the underlying model. Another company may adapt or integrate it. A deployer may add proprietary data, prompts, and business rules. Other vendors may provide identity information, scores, retrieval sources, or safety tools. The affected person, however, sees one system.</p>
<p>Colorado&rsquo;s proposal responds by requiring governance information to move downstream. Its provisions concerning developers and midstream developers call for documentation of intended and inappropriate uses, categories of data, known limitations and risks, monitoring, relevant factors, and use restrictions. Midstream developers, in turn, carry obligations for the developer documentation they obtain and transmit.</p>
<p>At each handoff, someone should know what documentation was received, what remains unknown, which uses are permitted, what conditions affect reliability, which version is being supplied, when changes will be communicated, and who is responsible for preserving downstream evidence about actual outcomes. The AILCCP frames these requirements through Data Stewardship (PR-005), which asks whether provenance is tracked end-to-end. Vendor assurances about &ldquo;responsible AI&rdquo; carry little weight against that question. A deployer facing a contested decision needs usable evidence, and if it disappeared somewhere between developer, integrator, and deployer, governance failed at the handoff.</p>
<h6>Continuous-Interaction Risk Assessment</h6>
<p>The chatbot provisions shift the focus from single decisions to sustained interactions. A safety test built around individual prompts and outputs misses what a conversational system can do across time. Memory, personalization, and repeated interaction may gradually produce a relationship that a single exchange cannot capture.</p>
<p>In evaluating whether a service falls within provisions concerning emotional companionship or emotionally dependent interaction, the proposal looks to features including anthropomorphic personalization, assigned identity attributes, memory of earlier exchanges, sycophantic or continually validating behavior, engagement-reinforcement mechanisms, and whether safeguards remain effective after model or feature changes.</p>
<p>Any one of those features may be benign in one product design and consequential in another, and the way those features compound across days or weeks may matter more than any single feature on its own. Testing should therefore follow representative interactions over time and after material changes to the system. The AILCCP presses one step further through Consent (PR-006), which treats consent as valid only while the user&rsquo;s understanding still matches how the system actually behaves. A relationship that deepens over weeks can outgrow the understanding the user gave at the first exchange, and consent obtained then may not cover what the service has since become.</p>
<h6>Feasibility as an Evidence Claim</h6>
<p>Nowhere is the obligation to keep testing more visible than in the treatment of technical feasibility, which Colorado would evaluate with reference to available technologies, comparable industry safeguards, alternatives, periodic reassessment, realistic testing, performance after updates, and documentation of rejected approaches. A design choice justified by the state of technology in January may deserve another look in July.</p>
<p>A metric can be calculated correctly and still create the wrong incentive, and the proposal&rsquo;s crisis-referral reporting for conversational AI is the clearest example. Operators would have to report the number of referrals relative to conversations and the proportion that actually involved suicidal ideation or self-harm risk under an evidence-based method. The obligation would extend to detection and response protocols, safety measures, testing, reliability and efficacy over time, age estimation, and interactions involving minors and prohibited sexual content.</p>
<p>Suppose a system becomes more conservative about issuing referrals. The proportion of referrals associated with genuine risk might improve because borderline cases are no longer referred. At the same time, the system could be missing more people who actually need intervention.</p>
<p>That is why governance needs paired measures. The AILCCP devotes a principle to the problem, Metrics (PR-020), which warns that optimizing what is measured can degrade what is not. Referral accuracy should be read alongside measures that expose what it cannot show, among them missed-risk rates, detection sensitivity on a governed evaluation set, false positives, time to escalation, performance changes after updates, and, where appropriate, variation across languages or interaction contexts. Measurement choices are themselves controls, and they warrant the same scrutiny as any other safeguard.</p>
<p>Taken together, Colorado&rsquo;s proposal points toward an understanding of AI governance that is considerably more operational than a collection of policies, principles, or one-time assessments. On that understanding, a deployed AI system should leave enough evidence to answer questions about a real event. Which configuration produced the outcome? Could the decision be revisited once inaccurate data was corrected? Did the reviewer possess genuine authority? Did a safety control continue to work after the model changed? Did the user&rsquo;s consent still cover what the service had become? Could the deployer obtain what it needed from the developer? These are difficult questions to answer with the policies and one-time assessments written before launch. Each asks what the system actually did after launch, and only records kept while it was running can answer that.</p>
<p>Any safeguard, whether mandated by Colorado or defined in the AILCCP framework, is effective only if the organization can use it when something bad happens. Each AILCCP principle turns that condition into something testable, defining a capability, pairing it with probing questions, and identifying the evidence that proves the organization has it. The framework took Colorado&rsquo;s long list of requirements and rendered it into capabilities an organization either has or lacks, which recasts compliance as an infrastructure question rather than a provision-by-provision chase. Someone will need an explanation, so decisions must be traceable. A decision will need to be revisited, so outcomes must be reproducible. An affected person will need a genuine second judgment, so the reviewer must be independent. And once the system changes, yesterday&rsquo;s safety evidence no longer describes it, so the safeguards must be retested, and their design reevaluated, after every material change. Those are the capabilities Colorado could codify. And because the AILCCP distills legislation, standards, and enforcement from many jurisdictions, an organization that builds them for Colorado is building them for whatever comes next.</p>]]></content>
	<updated>2026-08-19T21:58:51+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-08-19T21:58:51+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="ai governance"/>

	<category term="ailccp"/>

	<category term="eran kahana"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-08-12:/295578</id>
	<link href="https://law.stanford.edu/2026/08/12/ai-and-the-accountability-lag/" rel="alternate" type="text/html"/>
	<title type="html">AI and the Accountability Lag</title>
	<summary type="html"><![CDATA[<p>Scientific publishing has long depended on an imperfect assumption: producing a credible paper usual...</p>]]></summary>
	<content type="html"><![CDATA[<p>Scientific publishing has long depended on an imperfect assumption: producing a credible paper usually costs enough that its publication offers evidence that substantive work occurred. AI destabilizes that assumption. A fabricated study can reproduce the signals associated with genuine research&mdash;method, data, citations, disciplinary language&mdash;without reproducing the work behind them.</p>
<p>This divergence exemplifies what I call the <b>accountability lag</b>: the widening distance between the rate at which AI expands consequential action and the rate at which institutions can govern that action. The lag arises because technical capability and institutional responsibility follow different scaling patterns.</p>
<p><a href="https://www.schneier.com/essays/archives/2023/07/will-ai-hack-our-democracy.html" rel="noopener noreferrer" target="_blank">Bruce Schneier&rsquo;s four dimensions of AI advantage</a> help explain the technical side of that difference: speed, scale, scope, and sophistication. AI can complete an activity faster, repeat it across more settings, extend it into more domains, and incorporate more interacting factors. As those advantages compound, the activity surrounding the technology begins to change. Yet the institutions governing that activity do not necessarily undergo the same transformation. Operational capacity acquires the four S&rsquo;s; responsibility remains tied to scarce resources such as attention, authority, expertise, evidence, and enforceable consequences.</p>
<p>The imbalance can be expressed in terms of marginal cost. Producing another AI-generated output or action may cost very little. Meaningful accountability generally requires attention to the particular case. Each disputed diagnosis, denied benefit, defective filing, or unexplained decision may demand individual examination even when the underlying decisions were produced in bulk.</p>
<p>Organizations respond to this imbalance by preserving the appearance of responsibility. The favored instrument is human-in-the-loop review, a close cousin to the human oversight requirement in the EU AI Act. A human decision-maker, reviewer, or supervisor remains formally assigned. As deployment expands, however, that individual may lose the practical capacity to meaningfully examine the system&rsquo;s work.</p>
<p>Return to scientific publishing. The same cost collapse that lets a fabricated study pass for a real one increases the volume of material entering the publication system. Journals still depend on editors, reviewers, access to evidence, and eventual replication. The productive side of the system becomes scalable while its principal integrity mechanisms remain constrained.</p>
<p>Medicine reveals the same mismatch at the level of professional judgment. An imaging model may improve diagnostic capacity by comparing each scan with patterns learned from vast datasets. If the model also enables a large increase in case volume, the clinician&rsquo;s nominal responsibility remains unchanged while the conditions needed to exercise that responsibility deteriorate.</p>
<p>Knowledge codification extends the problem from individual decisions to organizational assumptions. AI can draw patterns from manuals, databases, communications, and employee practices, making dispersed knowledge widely available. Greater reach also allows an error or hidden assumption to propagate throughout the organization before anyone recognizes it.</p>
<p>Agentic systems add a temporal dimension. Responsibility is ordinarily assigned at identifiable decision points. An agent may collapse several of those points into a continuous sequence of execution. By the time a person encounters the result, the relevant opportunity for intervention may have passed. Accountability must therefore be designed into the architecture of action: where review occurs, where authority enters, and where execution pauses pending judgment.</p>
<p>This architecture also determines whether AI genuinely empowers the people affected by it. Speech recognition may increase independence for someone with limited mobility. A legal tool may make unfamiliar procedures accessible. A customer-service chatbot may instead expand an institution&rsquo;s processing capacity while reducing a customer&rsquo;s access to someone authorized to resolve the problem. The relevant measure is the distribution of agency: who can act, contest, obtain an explanation, and compel correction.</p>
<p>The agency a person can exercise against a consequential decision measures the accountability the institution actually delivers. A decision that cannot be challenged leaves the affected person without agency and producing that decision cheaply and in bulk does not shrink what the institution owes for it. Cigna&rsquo;s PXDX claim-review system, for example, <a href="https://www.propublica.org/article/cigna-pxdx-medical-health-insurance-rejection-claims" rel="noopener noreferrer" target="_blank">reportedly</a> let company physicians deny health-insurance claims in batches, spending an average of 1.2 seconds on each. Patients received a vaguely worded denial letter and entered an appeal process that required additional review before the decision could be disputed. Meaningful accountability therefore requires access to relevant evidence, authority to intervene, viable opportunities for contestation, and the institutional capacity to correct the process producing the outcome.</p>
<p>Whether those mechanisms keep pace can be measured through accountability elasticity, a term borrowed from economics: the degree to which an institution&rsquo;s capacity for explanation, intervention, contestation, and correction grows as the system&rsquo;s operational capacity grows. The lower the elasticity, the wider the lag. Each expansion then adds governance debt, activity the institution produces faster than it can meaningfully own.</p>
<p>No formula is needed to take the measurement. If use of an AI system increased one hundredfold, which mechanisms of accountability would increase with it? Who would review the additional decisions? Who could stop the system? Who could investigate a failure, correct its source, and answer to the person affected?</p>
<p>An institution without concrete answers has calibrated its oversight to a smaller and slower system than the one it now runs. That distance is the accountability lag, and it will not close on its own. The vendor ships a faster model and employees put it to use. Accountability grows only when someone builds it. <i>No one is in charge</i> is the inevitable result when an institution deploys the first without building the second.</p>
<p>***</p>
<p>Note: Accountability is one of 37 life cycle core principles. You can read more about it in the <a href="https://ailccp.ai" rel="noopener noreferrer" target="_blank">AI Life Cycle Core Principles Explorer.</a></p>]]></content>
	<updated>2026-08-12T14:57:49+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-08-12T14:57:49+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="ai"/>

	<category term="ai governance"/>

	<category term="ailccp"/>

	<category term="eran kahana"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-08-03:/294960</id>
	<link href="https://law.stanford.edu/2026/08/03/from-list-to-restatement-like-framework-the-evolution-of-the-ai-life-cycle-core-principles/" rel="alternate" type="text/html"/>
	<title type="html">From List to Restatement-Like Framework: The Evolution of the AI Life Cycle Core Principles</title>
	<summary type="html"><![CDATA[<p>When the AI Life Cycle Core Principles (AILCCP) was first published on this blog in March 2023, it w...</p>]]></summary>
	<content type="html"><![CDATA[<p>When the AI Life Cycle Core Principles (AILCCP) was first published on this blog in March 2023, it was a list. A carefully considered list, grounded in published standards and enforcement practice, but a list nonetheless. 37 principles, each with a name and a definition, organized by category. The footnotes were gradually inserted. They carried the analytical weight, pointing to NIST, ISO, the FTC, and the EU AI Act. The structure was flat. A reader could absorb a principle, consult a footnote, and move on.</p>
<p>That is no longer what the AILCCP is and you can already see the different <a href="https://ailccp.ai" rel="noopener noreferrer" target="_blank">here</a>.</p>
<p>The standards and best practices that inform the AILCCP are the raw material from which the framework is built. As of August 2026, the AILCCP maps 48 published standards to its 37 principles, drawing from ISO/IEC, IEEE, NIST, OWASP, and others. (The framework also tracks standards currently under development and once published, each of these will land on principles the framework already carries.)</p>
<p>Each published standard is assigned to the principles (which always appear in initial upper case) it most directly supports. For example, ISO/IEC 42001:2023, the AI management system standard, maps to Governance, Accountability, Privacy, Cooperation, and Enabling; the NIST AI Risk Management Framework maps to Governance, Security, Metrics, and Accountability; and IEEE 7003-2024 on algorithmic bias considerations maps to Bias, Fairness, Equity, and Ethics. The mapping lets a user trace any principle to the published authority behind it. A control sourced to ISO, NIST, or IEEE is not defended on my say-so, and that is what an auditor, a regulator, or a board member asking why we are doing this actually needs to hear.</p>
<p>The AILCCP was designed from the outset for a wide range of constituencies. Developers measure alignment with established norms; end users reference it in licensing, due diligence, and application maintenance; regulators guide enforcement; lawmakers draft legislation that is more relevant, clear, and practical; and lawyers, boards of directors, executives, auditors, and procurement officers each hold a piece of how AI systems are built, deployed, and overseen. A list, however well-constructed, serves these constituencies unevenly. It gave everyone the same flat surface, regardless of what they need to do with it.</p>
<p>The AILCCP is already substantially different than the original and is already undergoing structural changes that resemble the architecture of a restatement of the law. A restatement synthesizes authority courts have already made, turning accumulated holdings into clear rules, with comments that explain a rule&rsquo;s purpose and illustrations that show how it applies. The AILCCP rests on published standards and best practices because the case law it would otherwise synthesize is still being made. The principles are gradually acquiring structure, hierarchy, and cross-referencing. The definitions are being disciplined to declare operative standards rather than describe concepts. A commentary layer is being built out to carry the analytical and doctrinal weight that the original footnotes could only gesture toward, tracking doctrine that is forming rather than doctrine that has settled.<span>&nbsp;</span></p>
<p>The work is ongoing, with updates as frequent as daily in some cases. It is a manual process. Every addition to the framework is checked against primary sources&mdash;statutes, regulations, enforcement actions, and published standards&mdash;Bluebook-cited and logged in a refinement record that tracks what changed, why, and what remains unresolved.</p>
<p>Three examples show how the transformation is taking shape.</p>
<p><b>From definition to structured standard.</b> The original post defined Privacy as a principle requiring that AI systems respect individuals&rsquo; personal data in alignment with legal requirements and societal expectations. That definition is equally accurate and inert. The evolving framework is working toward a structure in which the principle states an operative standard, a comment explains what the standard requires and what it does not, and a separate commentary layer tracks the doctrinal developments that bear on application.</p>
<p><b>From principle to life cycle signal.</b> The original list did not inform when to apply a principle. Accountability appeared alongside Transparency and Privacy without any indication of which phases of an AI system&rsquo;s development required its attention. The current, evolving framework maps each principle to the phases of the AI life cycle where it carries the most operational weight, from scoping and design through deployment, operations, and decommissioning. Accountability, for example, is most consequential at scoping and design, pre-deployment review, and operations and monitoring. For an engineer, that signal identifies when to act. For a regulator examining a deployment, it identifies what evidence to request at each phase. For a board overseeing an AI program, it identifies the oversight gates that require documented approval. The life cycle mapping converts the framework from a reference document into an operational tool that different constituencies can use for different purposes without requiring each to derive the timing implications independently.</p>
<p><b>From assertion to evidenced position.</b> The original post stated that AI systems should be interpretable. The new framework supports that assertion with a three-level model, distinguishing the ability to (i) verify what the system is doing, (ii) evaluate whether a recommendation fits a given context, and (iii) learn from the system&rsquo;s reasoning. The third level, learning from AI rather than merely auditing it, reframes interpretability from a property of outputs to a property of the human-machine dialogue. That reframing changes what interpretability controls are adequate, what disclosure obligations attach, and what compliance evidence is meaningful. The AILCCP does not assert this as settled. It cites the authorities, flags the emerging nature of the position, and leaves the contested question open for the commentary to track as the doctrine develops.</p>
<p>These examples share a common denominator. In each case, the original principle provided a correct but static statement of an oversight norm. The evolving framework is adding the layers that allow each constituency to use that norm. The temporal signal, the evidentiary grounding, and the doctrinal context.</p>
<p>The AILCCP applies the method of a restatement to AI oversight before the field has produced the volume of enforcement, litigation, and regulatory guidance that would allow a true restatement to be written. The list was a starting point. I have spent the time since working out what a more rigorous structure requires and building it one principle at a time. A list can be written in an afternoon. A restatement cannot.</p>
<p><i>The AI Life Cycle Core Principles is an ongoing research project. The framework is maintained and updated as standards, enforcement actions, and academic literature develop.</i><i></i></p>]]></content>
	<updated>2026-08-03T17:35:02+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-08-03T17:35:02+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="ai governance"/>

	<category term="ai life cycle core principles"/>

	<category term="ailccp"/>

	<category term="eran kahana"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-07-29:/294586</id>
	<link href="https://law.stanford.edu/2026/07/29/world-models-and-the-validity-of-the-learned-environment/" rel="alternate" type="text/html"/>
	<title type="html">World Models and the Validity of the Learned Environment</title>
	<summary type="html"><![CDATA[<p>The Stanford HAI issue brief The World Model and Spatial Intelligence Era: Governing AI Beyond Langu...</p>]]></summary>
	<content type="html"><![CDATA[<p>The Stanford HAI issue brief <a href="https://hai.stanford.edu/assets/files/hai-issue-brief-the-world-model-and-spatial-intelligence-era.pdf" rel="noopener noreferrer" target="_blank"><i>The World Model and Spatial Intelligence Era: Governing AI Beyond Language</i></a> prompted me to update the <a href="https://AILCCP.replit.app" rel="noopener noreferrer" target="_blank">AI Life Cycle Core Principles</a> (AILCCP) framework. The brief identifies a third object of AI oversight, the validity of the learned environment itself. Drawing on that insight, I have incorporated environment validity into the Fidelity, Safety, Metrics, Accountability and Security principles.</p>
<p><i>Note: Initial capitals are used throughout this post to identify AILCCP principles.</i> <i>Parenthetical identifiers give each principle&rsquo;s number in the framework. The term &ldquo;oversight&rdquo; is used instead of &ldquo;governance&rdquo; due to the framework&rsquo;s use of that term as a principle.</i></p>
<p>The framework update begins with the premise that AI oversight must reach whatever can carry an error into harm.</p>
<p>In the brief&rsquo;s account, two objects have organized the oversight conversation for much of the recent AI era. The first is content, meaning what a system generates. Content rules ask whether an output is accurate, lawful, fair, deceptive or harmful. The second is action, meaning what a system is permitted to do. Action rules ask what authority has been delegated, which decisions require approval, who provides oversight and when the system must stop.</p>
<p>That framework works for systems whose principal effects arise from the information they produce or the authority they exercise. The brief argues that policy built for generated content and autonomous decision-making does not fully reach world models.</p>
<p>A world model builds a working representation of a physical environment and predicts how that environment will change in response to action. Its representation can become a substitute for the world in training, testing and decision-making. If the world model makes an error, the failure is, as HAI describes it, &ldquo;a counterfeit of physical reality that can look flawless while being wrong.&rdquo;</p>
<p>Once a flawed environment is reused, the error can spread through every system trained within it, every certification based upon it and every decision informed by it. Because that spread can evade detection, validation has to precede use rather than follow failure. If a system is trained, tested or guided by a learned environment, whoever deploys the system must establish the validity of that environment for its intended use before the system is trusted.</p>
<p>When does validation attach? It could attach by model class, beginning once a system counts as a renderer, a simulator or a planner. Another option is to attach validation to the intended use instead, beginning when the system&rsquo;s inferences move physical equipment, inform a safety decision or support a certification that others rely on. The AILCCP update takes the second approach, which follows the brief&rsquo;s call for safeguards matched to how and where a system is used. The principles below key validation to intended use.</p>
<p>The AILCCP now translates the third object into a reference that can be used in system design, contracting, procurement, auditing and incident investigation. Because environment validity cuts across the AI system&rsquo;s life cycle, the update appears within several principles.</p>
<p>Fidelity (PR-014) requires the learned environment to be validated for its intended use.</p>
<p>Safety (PR-029) requires real-world validation before a simulation-trained system is deployed. It also requires safe behavior when the system encounters conditions the learned environment omitted, simplified or represented incorrectly.</p>
<p>Metrics (PR-020) requires measurements of physical validity, transfer to real conditions and safe performance at the boundaries of the environment&rsquo;s demonstrated competence.</p>
<p>Accountability (PR-002) requires a time-stamped record connecting what the system perceived, the state it inferred and the action it took. The record must also identify the relevant model and simulator versions, safety-layer decisions and human interventions.</p>
<p>Security (PR-030) requires the system&rsquo;s learned picture of its surroundings to be treated as an attack surface and defended accordingly. An adversary may poison the data used to build the environment, manipulate the sensors that update it or corrupt the simulation used for training and certification.</p>
<p>Together, these principles settle what needs to be validated, which evidence suffices and how the system must behave once its learned environment no longer deserves confidence.</p>
<p>World models remain early and fast-moving. Their functions overlap, their architectures are changing and the science needed to evaluate them remains incomplete. That uncertainty makes a rigid regime premature. The AILCCP can supply durable questions while the required evidence sharpens in sync with the technology.</p>
<p>What must the learned environment represent for this use? Which real-world evidence establishes that it does? Where does the representation cease to be reliable? Has transfer been tested independently? What happens when the system reaches the edge of the environment&rsquo;s competence? Who approved the evidence, and who can stop deployment when it proves inadequate? A deployment that cannot answer them has substituted an assumption for evidence.</p>]]></content>
	<updated>2026-07-29T13:34:04+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-07-29T13:34:04+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="ai governance"/>

	<category term="ai life cycle core principles"/>

	<category term="ailccp"/>

	<category term="eran kahana"/>

	<category term="world models"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-07-29:/294531</id>
	<link href="https://law.stanford.edu/2026/07/28/world-foundation-models-and-the-oversight-of-physical-ai/" rel="alternate" type="text/html"/>
	<title type="html">World Foundation Models and the Oversight of Physical AI</title>
	<summary type="html"><![CDATA[<p>AI increasingly reaches beyond the screen. Vision-language-action models can translate images and in...</p>]]></summary>
	<content type="html"><![CDATA[<p>AI increasingly reaches beyond the screen. Vision-language-action models can translate images and instructions into robotic movements. Driving models can convert sensor data into steering and braking commands. World foundation models generate and predict physical environments used to train and test the systems that act within them.</p>
<p>This shortens the distance between inference and consequence. An error can become motion before a person has an opportunity to examine it. The resulting risks are more immediate, but they remain susceptible to life cycle oversight. The <a href="https://vifa-recht.de/AILCCP.replit.app" rel="noopener noreferrer" target="_blank">AI Life Cycle Core Principles</a> (AILCCP) provide a way to identify where those risks arise, how they move through the system and what evidence is needed to control them.</p>
<p><i>Note: Initial capitals are used throughout this post to identify AILCCP principles.</i> <i>Each principle carries its framework identifier in parentheses at first mention.</i> <i>Where a word that also names a principle appears in lowercase, it carries its ordinary meaning.</i><i></i></p>
<h5>The Physical AI Stack</h5>
<p>Physical AI encompasses several technologies performing different roles.</p>
<p>World foundation models, such as <a href="https://arxiv.org/abs/2501.03575" rel="noopener noreferrer" target="_blank">NVIDIA Cosmos</a>, learn representations of physical environments and can generate simulations or synthetic data for downstream development. Embodied reasoning models interpret scenes, identify objects, predict trajectories and plan actions. Vision-language-action models, such as <a href="https://arxiv.org/html/2503.20020v1" rel="noopener noreferrer" target="_blank">Gemini Robotics</a>, convert observations and instructions into action sequences. Controllers, sensors, actuators and safety systems determine how those sequences are executed.</p>
<p>These components may be combined in many ways. A world model may support offline training, runtime planning or both. A reasoning model may serve as a perception layer, generate a trajectory or help control a robot directly. The relevant risk therefore depends on the component&rsquo;s role, the environment in which the system operates, its degree of autonomy and the safeguards surrounding it.</p>
<p>This system-level interdependence means the AILCCP can only be meaningfully applied when the AI system is understood end-to-end as a single interacting whole. A &ldquo;system-level view&rdquo; therefore requires evaluating how models, data, hardware, sensors, deployment context and human operators jointly shape behavior in practice, rather than assessing any component in isolation.</p>
<h5>Training and Simulation</h5>
<p>World foundation models can reduce the cost and danger of collecting physical-world data. They allow developers to expose a robot or vehicle to rare conditions without creating those conditions in the real world. Their value depends on whether the simulation preserves the features that matter when the system is deployed.</p>
<p>The central problem is the sim-to-real gap. A simulated environment may simplify friction, visibility, object behavior, sensor noise or human movement. A downstream model trained on those simplifications may perform well in testing and fail when reality supplies conditions the simulation lacks.</p>
<p>Accuracy (PR-003) and Fidelity (PR-014) therefore require more than success within the simulated environment. Developers must establish that training and evaluation conditions represent the intended operating environment, identify material departures from reality and test performance against real-world data. Validation should include rare but consequential scenarios, not merely average task completion.</p>
<p>Transparency (PR-033) requires records of the models, datasets, assumptions and simulation versions used to produce training evidence. Permit (PR-021) addresses the authority to use human demonstrations, teleoperation logs, proprietary sensor data and other protected material. Efficiency (PR-008) and Sustainable (PR-031) require an assessment of whether the compute devoted to simulation produces safety or performance gains commensurate with its cost.</p>
<p>The world foundation model&rsquo;s role is upstream, but its oversight consequences can persist throughout the system.</p>
<h5>Integration and Verification</h5>
<p>A model that performs well in isolation may become unsafe when connected to hardware. Sensor placement, latency, payload, actuator limits, controller behavior and the physical workspace can alter the consequences of the same model output.</p>
<p>Safety (PR-029) and Reliability (PR-026) must therefore be evaluated at the system level. Applicable controls may include redundant sensing, verified safety envelopes, restricted operating conditions, collision avoidance, speed and separation monitoring, emergency stops and fallback controllers. Governance (PR-016) determines who approves the integrated system, which evidence is required and who has authority to stop deployment.</p>
<p>A separate runtime layer that evaluates a proposed action before execution can be useful. Its effectiveness depends on the independence and quality of the evidence it receives. If both the action model and the safety layer rely on the same camera view obscured by the same pallet, the second layer may confirm the same mistaken account of the world. Reliable protection may require additional sensors, conservative behavior under occlusion or physical restrictions on the workspace.</p>
<p>System-level assurance must therefore be achieved through coordinated controls spanning training, integration and deployment rather than reliance on any isolated safeguard.</p>
<h5>Deployment and Operation</h5>
<p>Physical operation makes time an important oversight variable. Detection, escalation and intervention must occur quickly enough to prevent harm. A control that works for an application generating text may be inadequate for a robot operating beside workers.</p>
<p>Safety and Reliability therefore require continuous monitoring, detection of unfamiliar operating conditions and a defined safe response. That response may involve slowing, stopping, requesting human assistance or switching to a simpler controller. Human oversight must be supported by sufficient information, time, training and authority. A person nominally assigned to supervise a system offers little protection if intervention is practically impossible.</p>
<p>Transparency also takes a more operational form. The evidentiary record may need to preserve the relevant sensor state, model and controller versions, proposed action, safety-layer decision, actuator command, intervention and system response. Near misses matter as much as completed incidents because they reveal hazards before injury occurs.</p>
<p>Maintenance obligations control what happens after deployment. Model updates, hardware changes and new operating environments can alter system behavior. Each material change requires regression testing, renewed validation and a documented decision that the system remains within its approved operating conditions.</p>
<h5>Accountability Across the Stack</h5>
<p>A physical AI system may involve a world-model provider, a robotics-model developer, a systems integrator, a hardware manufacturer and the organization operating the finished system. This complicates investigation and responsibility, but it does not eliminate either causation or accountability.</p>
<p>Accountability (PR-002) and Governance require duties to be assigned before deployment. Agreements among participants should address testing access, technical documentation, evidence retention, update notices, incident cooperation and authority to suspend operation. The organization deploying the system must understand the integrated product well enough to determine whether its risks are acceptable. Supplier complexity cannot become a substitute for that judgment.</p>
<p>The AILCCP&rsquo;s objective of maintaining no gap between system behavior and the deployer&rsquo;s liability is especially important here. Its implementation requires responsibility to be distributed deliberately across the stack while preserving a clear point of responsibility for the system placed into operation.</p>
<h5>What Physical AI Demands of the AILCCP</h5>
<p>Physical AI changes the emphasis placed on different principles at different stages. Accuracy and Fidelity govern the relationship between simulation and reality. Safety and Reliability govern integration and operation. Transparency supplies the evidence needed to test, monitor and reconstruct system behavior. Accountability and Governance connect those obligations across organizations and throughout the life cycle.</p>
<p>The necessary next step is a physical-AI control mapping: the controls and evidence that make each principle concrete at each layer of the system. That mapping should remain sensitive to the application. A warehouse arm, surgical robot and autonomous vehicle do not require identical controls merely because each uses a vision-language-action model.</p>
<p>World foundation models expand the environments in which physical systems can be trained and tested. Physical AI shortens the path from model output to real-world consequence. Together, they raise the level of assurance required across the AI life cycle. The system must be assessed through its training environment, integration, operating limits, runtime safeguards, update process and allocation of responsibility.</p>
<p>Life cycle oversight proves its value by following risk from the assumptions built into a simulated world to the moment a machine acts in the real one.</p>]]></content>
	<updated>2026-07-28T23:12:56+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-07-28T23:12:56+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="ai governance"/>

	<category term="ailccp"/>

	<category term="eran kahana"/>

	<category term="generative ai"/>

	<category term="robotics"/>

	<category term="world foundation models"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-07-20:/294032</id>
	<link href="https://www.gautrais.com/publications/droit-africain-de-la-consommation-mobile-ledy-zannou/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=droit-africain-de-la-consommation-mobile-ledy-zannou" rel="alternate" type="text/html"/>
	<title type="html">Vincent Gautrais, « Préface », dans Ledy Rivas Zannou, Droit africain de la consommation mobile, Éditions Larcier, Bruxelles, 2026, pp. 11-14. </title>
	<summary type="html"><![CDATA[<p>&nbsp;
&nbsp;
Pr&eacute;face de l&rsquo;ouvrage de Ledy Rivas Zannou
Les enjeux juridiques de la consommation mobile en Afr...</p>]]></summary>
	<content type="html"><![CDATA[<p align="center"><b>&nbsp;</b></p>
<p align="center"><b>&nbsp;</b></p>
<p align="center"><b>Pr&eacute;face de l&rsquo;ouvrage de Ledy Rivas Zannou</b></p>
<p align="center"><i>Les enjeux juridiques de la consommation mobile en Afrique de l&rsquo;Ouest&nbsp;:</i></p>
<p align="center"><i>analyse du processus contractuel</i></p>
<p align="center">Vincent Gautrais</p>
<p align="center"><i>Professeur, CRDP, Facult&eacute; de droit de l&rsquo;Universit&eacute; de Montr&eacute;al</i></p>
<p><b>&Eacute;l&eacute;gance</b>. Professeur Ledy Rivas Zannou, avec l&rsquo;&eacute;l&eacute;gance qu&rsquo;on lui connait, &agrave; cru bon de me demander, &agrave; titre de directeur de th&egrave;se, de pr&eacute;facer le pr&eacute;sent ouvrage que j&rsquo;ai eu le plaisir d&rsquo;accompagner. Une &eacute;l&eacute;gance qui ne s&rsquo;impose pas; en fait, les th&egrave;ses, paradoxalement, quand elles sont bonnes, <i>a fortiori</i> tr&egrave;s bonnes, demandent bien peu au directeur. Bien davantage, elles nous autorisent d&rsquo;&ecirc;tre &agrave; une place privil&eacute;gi&eacute;e. Comme au th&eacute;&acirc;tre, on si&egrave;ge au premier rang, dans la corbeille, au-dessus de la fosse.</p>
<p><b>Contrat</b>. &Eacute;videmment, au d&eacute;part, il y a le contrat que nous affectionnons dans la mesure o&ugrave; il constitue l&rsquo;institution &agrave; laquelle nous avons apport&eacute; ce regard d&rsquo;introspection qu&rsquo;une th&egrave;se exige. Ce &laquo;&nbsp;pilier du droit&nbsp;&raquo; selon Carbonnier, Ledy Zannou l&rsquo;a d&rsquo;abord forc&eacute;ment envisag&eacute; de l&rsquo;int&eacute;rieur, dans toute sa technicit&eacute; juridique. Mais il y ajouta aussi une approche plus a&eacute;rienne, en tenant compte de son &eacute;volution historique et de l&rsquo;usage que l&rsquo;on en fait. Notamment, et c&rsquo;est particuli&egrave;rement clair dans sa th&egrave;se, on y voit d&rsquo;abord la g&eacute;n&eacute;ralisation du ph&eacute;nom&egrave;ne selon lequel l&rsquo;acte se voit substitu&eacute; &agrave; un processus. Ensuite, et peut-&ecirc;tre surtout, qu&rsquo;on ne peut l&rsquo;appr&eacute;hender sans proposer une mise en contexte, plus ext&eacute;rieure, sans laquelle ce processus contractuel ne peut &ecirc;tre compris. Cette mise en contexte, tout est l&agrave;, s&rsquo;exerce en tenant compte de trois param&egrave;tres principaux sur lesquels Ledy Zannou prend le soin de d&eacute;velopper la notion de contrat&nbsp;: le num&eacute;rique, la consommation mobile et l&rsquo;Afrique.</p>
<p><b>Num&eacute;rique</b>. Bien s&ucirc;r, ce contrat, il en a vu d&rsquo;autres. A bien des &eacute;gards, la th&egrave;se le montre, il s&rsquo;agit d&rsquo;une notion qui est d&rsquo;une plasticit&eacute; telle que sa transposition dans des contextes aussi distincts soient-ils s&rsquo;op&egrave;re ma fois sans trop d&rsquo;anicroches. Il est donc &eacute;tonnant de constater dans ce travail comment des principes pluris&eacute;culaires sont somme toute assez transposables dans des environnements nouveaux. Le droit, science de la r&eacute;action, offre la sagesse inh&eacute;rente &agrave; ce regard en arri&egrave;re. N&eacute;anmoins, le num&eacute;rique oblige aussi &agrave; contorsion. Sans trancher entre simple &eacute;volution ou r&eacute;volution, entre Easterbrooke<a title="" href="https://vifa-recht.de#_ftn1" name="_ftnref1" rel="noopener noreferrer" target="_blank"><span><span><span>[1]</span></span></span></a> et Lessig<a title="" href="https://vifa-recht.de#_ftn2" name="_ftnref2" rel="noopener noreferrer" target="_blank"><span><span><span>[2]</span></span></span></a>, ceci variant selon celui qui scrute, il bouleverse tout sur son passage. Il requiert forc&eacute;ment &agrave; la jurisprudence d&rsquo;adapter son regard. Un regard qui &eacute;volue au fil du temps, int&eacute;grant avec plus ou moins de sp&eacute;cificit&eacute;s le contexte num&eacute;rique, comme le montre l&rsquo;&eacute;volution entre les arr&ecirc;ts de la Cour supr&ecirc;me du Canada de 2007 (Dell Computer)<a title="" href="https://vifa-recht.de#_ftn3" name="_ftnref3" rel="noopener noreferrer" target="_blank"><span><span><span>[3]</span></span></span></a> &agrave; 2017 (Douez c. Facebook)<a title="" href="https://vifa-recht.de#_ftn4" name="_ftnref4" rel="noopener noreferrer" target="_blank"><span><span><span>[4]</span></span></span></a>. Le num&eacute;rique implique donc son lot de faits que le droit en g&eacute;n&eacute;ral et le contrat en particulier se doit de consid&eacute;rer.</p>
<p><b>Consommation mobile</b>. Cette int&eacute;gration revendiqu&eacute;e des valeurs associ&eacute;es au num&eacute;rique, qui appara&icirc;t dans l&rsquo;intitul&eacute; m&ecirc;me de la seconde partie de l&rsquo;ouvrage, doit aussi &ecirc;tre envisag&eacute;e en tenant compte de la double sp&eacute;cificit&eacute; que constitue la consommation mobile. La consommation donne lieu dans un premier temps &agrave; l&rsquo;&eacute;laboration de contrats qui usent et abusent de la position de force dans lesquels les marchands se trouvent. Une vuln&eacute;rabilit&eacute; du consommateur donc qui, en second temps, est m&ecirc;me amplifi&eacute;e par l&rsquo;omnipr&eacute;sence du t&eacute;l&eacute;phone comme support du processus contractuel. Cette technologie omnipr&eacute;sente en Afrique est en effet d&rsquo;une pi&egrave;tre qualit&eacute; communicationnelle lorsque l&rsquo;on ne fait que transposer les fa&ccedil;ons de faire propres au papier ou m&ecirc;me &agrave; l&rsquo;&eacute;cran d&rsquo;ordinateur. Professeur Zannou y va donc de propositions adaptatives afin que la volont&eacute; propre &agrave; tout contrat ne soit pas une chim&egrave;re, et ce, en int&eacute;grant tant des consid&eacute;rations techniques que communicationnelles.</p>
<p><b>Afrique</b>. Et puis l&rsquo;Afrique enfin, celle ch&egrave;re &agrave; Ledy, constitue un merveilleux terrain d&rsquo;&eacute;tudes. Avec ses sp&eacute;cificit&eacute;s, &eacute;conomiques, culturelles, communicationnelles, elle ne peut se limiter &agrave; reproduire les injonctions des pays du Nord. L&rsquo;uniformisation du droit n&rsquo;est pas une panac&eacute;e; les droits africains se doivent d&rsquo;identifier et appliquer les caract&eacute;ristiques propres &agrave; ce continent.</p>
<p><b>Rapports de force</b>. En relisant la th&egrave;se de Ledy Zannou, et &agrave; travers l&rsquo;analyse fine de ce triple regard, il me semble clair que cette mise en contexte tient dans les trois cas d&rsquo;une alt&eacute;ration des rapports de force. Le contrat est affaire de pareilles tensions o&ugrave; num&eacute;rique, consommation et Afrique sont des occasions de remettre en cause les principes protecteurs avec lesquels il se doit de composer. Le contrat, selon le professeur Zannou, tout comme les autres branches du droit, est p&eacute;tri de consid&eacute;rations g&eacute;opolitiques qui ne peuvent &ecirc;tre ignor&eacute;es.</p>
<p><b>&Eacute;cole de Montr&eacute;al</b>. Il y a donc dans cet ouvrage une vraie et belle th&egrave;se. Th&egrave;se qui ressemble &agrave; son auteur qui, je le suppute, risque de servir de fondation &agrave; sa carri&egrave;re qui s&rsquo;amorce. Une th&egrave;se qui s&rsquo;est aussi je crois grandement nourrie par les influences du centre de recherche, le CRDP, qui l&rsquo;a accueilli. Un centre qui depuis de nombreuses d&eacute;cennies, au-del&agrave; du seul droit positif, analyse justement en contextualisant l&rsquo;int&eacute;gration des valeurs, des institutions et des normes<a title="" href="https://vifa-recht.de#_ftn5" name="_ftnref5" rel="noopener noreferrer" target="_blank"><span><span><span>[5]</span></span></span></a>. Ledy, du fait d&rsquo;une grande ouverture, d&rsquo;une belle curiosit&eacute; intellectuelle, a su admirablement s&rsquo;approprier ces influences tout en tra&ccedil;ant son propre chemin.</p>
<p><b>Pr&eacute;face</b>. Il est bien tard dans ce tr&egrave;s court texte de se demander &agrave; quoi sert une pr&eacute;face. &Eacute;videmment, il ne s&rsquo;agit pas de r&eacute;sumer l&rsquo;&oelig;uvre en cause. D&rsquo;une pr&eacute;face &agrave; l&rsquo;autre, je ne peux me d&eacute;partir de celle, d&eacute;licieuse, que le professeur Mousseron avait fait dans la th&egrave;se de Bernard Tessier sur les groupes de contrats en 1975&nbsp;:</p>
<p><span>&laquo;&nbsp;Le culte de l&rsquo;individuel a marqu&eacute; le 19i&egrave;me si&egrave;cle comme le culte de l&rsquo;ensemble para&icirc;t dominer le 20i&egrave;me si&egrave;cle vieillissant. &Agrave; la tendresse pour le grain succ&egrave;de la ferveur pour la grappe&nbsp;&raquo;<a title="" href="https://vifa-recht.de#_ftn6" name="_ftnref6" rel="noopener noreferrer" target="_blank"><span><span><span>[6]</span></span></span></a>.</span></p>
<p>J&rsquo;aurais aim&eacute; avoir &eacute;crit une r&eacute;f&eacute;rence aussi joliment imag&eacute;e. Je crois aussi que le contrat &eacute;volue au gr&eacute; des d&eacute;cennies et que l&rsquo;approche collective qui existait alors a &eacute;t&eacute; depuis malmen&eacute;e, notamment par le num&eacute;rique qui tend &agrave; isoler. D&rsquo;ailleurs, la th&egrave;se du professeur Zannou propose justement d&rsquo;ins&eacute;rer une plus grande intervention tant de la loi que de la communaut&eacute;. Au-del&agrave; de cette question entre libert&eacute; et intervention, individu et collectif, finalement, la raison d&rsquo;&ecirc;tre de la pr&eacute;sente pr&eacute;face est assez simple&nbsp;: je ne saurais trop inciter &agrave; la lecture de l&rsquo;ouvrage de Professeur Zannou afin de d&eacute;couvrir, justement, une th&egrave;se qui en est une et qui constitue un passage oblig&eacute; sur la question. Fort d&rsquo;une plume color&eacute;e, alerte, dans le cadre d&rsquo;un ouvrage ultradocument&eacute; et clairement expos&eacute;, je souhaite au lecteur ou &agrave; la lectrice autant de plaisir &agrave; la lire que j&rsquo;en ai eu &agrave; la voir se construire.</p>
<div>
<p>&nbsp;</p>
<hr align="left" size="1">
<div>
<p><a title="" href="https://vifa-recht.de#_ftnref1" name="_ftn1" rel="noopener noreferrer" target="_blank"><span><span><span>[1]</span></span></span></a> <span lang="EN-CA">Frank H. EASTERBROOKE, &laquo;&nbsp;Cyberspace and the Law of the Horse&nbsp;&raquo;, (1996) n&deg;1 University of Chicago LegalForum 207.</span></p>
</div>
<div>
<p><a title="" href="https://vifa-recht.de#_ftnref2" name="_ftn2" rel="noopener noreferrer" target="_blank"><span><span><span>[2]</span></span></span></a> <span lang="EN-US">Larry LESSIG, &ldquo;The Law of The Horse. What Cyberlaw Might Teach&rdquo;, (1999) <i>Harvard Law Review </i>501.</span></p>
</div>
<div>
<p><a title="" href="https://vifa-recht.de#_ftnref3" name="_ftn3" rel="noopener noreferrer" target="_blank"><span><span><span>[3]</span></span></span></a> Dell Computer c. Union des consommateurs, 2007 CSC 34.</p>
</div>
<div>
<p><a title="" href="https://vifa-recht.de#_ftnref4" name="_ftn4" rel="noopener noreferrer" target="_blank"><span><span><span>[4]</span></span></span></a> <span lang="EN-CA">Douez c. Facebook, 2017 CSC 33.</span></p>
</div>
<div>
<p><a title="" href="https://vifa-recht.de#_ftnref5" name="_ftn5" rel="noopener noreferrer" target="_blank"><span><span><span>[5]</span></span></span></a> Vincent GAUTRAIS, &laquo;&nbsp;Tentative d&eacute;finitionnelle du CRDP&nbsp;&raquo;, (2022) 56-2 <i>Revue Th&eacute;mis</i> 361, 365.</p>
</div>
<div>
<p><a title="" href="https://vifa-recht.de#_ftnref6" name="_ftn6" rel="noopener noreferrer" target="_blank"><span><span>[6]</span></span></a> <span>Jean-Marc MOUSSERON, &laquo;&nbsp;pr&eacute;face&nbsp;&raquo;, dans Bernard TEYSSI&Eacute;, <i>Les groupes de contrats,</i> Paris, L.G.D.J., 1975, p. xv.</span></p>
</div>
</div>]]></content>
	<updated>2026-07-20T21:42:24+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-07-20T21:42:24+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-07-08:/293023</id>
	<link href="https://law.stanford.edu/2026/07/08/when-or-how-principles-can-become-law-the-ftcs-proposed-deceptive-steering-policy-scoped-against-the-ai-life-cycle-core-principles/" rel="alternate" type="text/html"/>
	<title type="html">When (or How) Principles Can Become Law: The FTC’s Proposed Deceptive Steering Policy Scoped Against the AI Life Cycle Core Principles</title>
	<summary type="html"><![CDATA[<p>Introduction
On July 1, 2026, the Federal Trade Commission published a proposed policy statement app...</p>]]></summary>
	<content type="html"><![CDATA[<p><b>Introduction</b></p>
<p>On July 1, 2026, the Federal Trade Commission published a <a href="https://www.ftc.gov/system/files/ftc_gov/pdf/ai-policy-statement_0.pdf" rel="noopener noreferrer" target="_blank">proposed policy statement</a> applying Section 5 of the FTC Act, 15 U.S.C. &sect; 45(a), to AI companies that steer their systems&rsquo; outputs &ldquo;contrary to consumers&rsquo; reasonable expectations.&rdquo; Public comment closes on July 31, 2026. In this post, I process the policy statement through the AI Life Cycle Core Principles (AILCCP) framework to determine which of the framework&rsquo;s AI-related 37 principles are implicated, how, and what that means for the developers, deployers, and counsel who will eventually need to account for it.</p>
<p>But before we begin, a few words about the AILCCP are in order. In March 2023, I introduced the <a href="https://law.stanford.edu/2023/03/17/ai-life-cycle-core-principles/" rel="noopener noreferrer" target="_blank">AI Life Cycle Core Principles</a>, a framework consisting of 37 AI-related life cycle principles built to give developers, deployers, regulators, and legal practitioners a shared, precise vocabulary for evaluating AI systems across their full operational life cycle. The AILCCP&rsquo;s core ambition was&mdash;and remains&mdash;to surgically strip away the pervasive definitional ambiguity that keeps AI oversight discussions perpetually aspirational and in the course of this work, the framework grew and gained additional structure. All of these principles are now organized into 10 pillars and mapped across 10 life cycle phases, supported by 48 controls, aligned to 47 international standards from ISO/IEC, IEEE, NIST (and others), and cross-referenced to FTC, SEC, and FDA enforcement. More than 400 explicit cross-references, together with a taxonomy of recognized AI risks, connect these layers. The 10 life cycle phases trace an AI system from scoping and design through decommissioning, and each principle carries life cycle signals marking the phases where its risks, and the oversight they demand, concentrate. (A public-facing version of the framework is found at <a href="https://ailccp.replit.app" rel="noopener noreferrer" target="_blank">https://ailccp.replit.app</a>.)<span>&nbsp;</span></p>
<p>The AILCCP framework serves a wide range of practical purposes. Practitioners can use it to measure the efficacy of proposed and enacted legislation against a defined principle set, separating statutes that actually drive change in conduct from those that merely aspire to it; to analyze AI vendor agreements, AI corporate policies, and AI oversight documents for the same gaps; to identify which of the framework&rsquo;s 48 controls a deployment requires, from logging to human-in-the-loop gates; and to address virtually any other AI-related issue, mapping each principle to relevant international standards and enforcement regimes. Every definition in the framework comprises many elements, and any single legal development typically implicates only a subset of them. (The Governance principle, for example, is comprised of 17 distinct elements.) Homing in on the most relevant subset through the AILCCP gives practitioners a more precise vocabulary for gauging both their compliance posture, how well their practices align with the principle, and their exposure, where that alignment fails and enforcement risk begins.<span>&nbsp;</span></p>
<p>Queried against the policy statement, the framework yields two findings. The policy statement activates three principles from the AILCCP: Truth, Transparency, and Accountability. It assigns them the force of federal consumer protection law. And in doing so, it generates a collision between federal and state obligations that the Governance principle must absorb.</p>
<p><b>What the FTC Proposes</b></p>
<p>The FTC proceeds from the premise that AI companies market their products as systems that distill human knowledge to solve problems in furtherance of consumers&rsquo; objectives. Consumers therefore reasonably expect truthful and accurate outputs. A company that steers its system toward other objectives without clearly disclosing the deviation makes a material misrepresentation likely to mislead a reasonable consumer and affect the consumer&rsquo;s conduct. That is deception under Section 5.</p>
<p>The policy statement treats a company&rsquo;s motive as irrelevant. Whether the steering serves commercial profit, an effort to shape public opinion, or compliance with a state law that requires embedding particular values, the deception analysis is the same. A company avoids a deception finding, and thus falls within the proposed safe harbor, by &ldquo;clearly and conspicuously&rdquo; disclosing that its system prioritizes certain objectives over what users request and otherwise expect. (There is an open question as to whether consumers would bother reading any of these disclosures, let alone understand them, but that is a rabbit hole I want to avoid for now.) Disclosure is the sole lawful path for operating a system whose objectives diverge from the consumer&rsquo;s default expectation.</p>
<p><b>Truth: The Default Expectation</b></p>
<p>In relevant part, the AILCCP framework defines Truth as ensuring &ldquo;that the outputs, representations, reasoning, and explanations provided by the AI are accurate, honest, and not misleading throughout the system&rsquo;s life cycle.&rdquo; The detailed definition extends to grounding responses in verifiable data, minimizing hallucinations, and disclosing areas where the system cannot provide truthful outputs.</p>
<p>The FTC converts this requirement into a legal baseline. The policy statement reads, &ldquo;[C]onsumers have a reasonable expectation that AI systems aim to give truthful and accurate outputs. Consumers have no basis to believe that AI systems aim to produce outputs that are distorted by undisclosed ideological objectives.&rdquo; By anchoring the deception analysis to that expectation, the FTC makes Truth the default state against which all AI output is measured. A system that deviates without disclosure is presumptively deceptive.</p>
<p>The AILCCP assigns Truth its primary life cycle signals at Model Development and Training and at Operations and Monitoring (two of the framework&rsquo;s ten life cycle phases, the first covering how a model is built and trained, the second how it runs in production under ongoing monitoring). Developers who introduce steering during model training, or who let output objectives drift during operations, without a matching disclosure mechanism are now working in territory the FTC has marked.</p>
<p><b>Transparency: The Mechanism of Compliance</b></p>
<p>The AILCCP&rsquo;s Transparency principle requires in relevant part that &ldquo;every significant aspect of the AI system&rsquo;s data practices, logic, decision-making, and governance is open, accessible, and understandable to relevant stakeholders.&rdquo; Because a disclosure that is technically present but practically incomprehensible fails that test, the framework sets the operative benchmark at what it calls &ldquo;epistemic uptake,&rdquo; met only when disclosed information is absorbed into stakeholder decision-making.</p>
<p>The FTC&rsquo;s safe harbor maps onto Transparency and adds a procedural requirement of its own. The requirement demands clarity, conspicuousness, and persistence, which puts it well beyond a single disclosure buried in terms of service. The Commission is describing what the framework calls &ldquo;multi-level communication,&rdquo; tailored disclosures for technical, operational, and lay audiences, and &ldquo;comprehension verification,&rdquo; the periodic assessment of whether audiences have formed an accurate understanding of system operation. The safe harbor also tracks the framework&rsquo;s &ldquo;stratified transparency,&rdquo; under which disclosure obligations scale with the sophistication gap between developer and affected population. A consumer-facing AI product serves users with limited technical literacy relative to its developer, so the obligation scales up.</p>
<p>Transparency&rsquo;s life cycle signals sit at two of the framework&rsquo;s ten life cycle phases: Scoping and Design, and Pre-Deployment Review. A company that builds its disclosure architecture only after a consumer complaint or an enforcement inquiry has already missed the window the safe harbor requires.</p>
<p><b>Accountability: The Enforcement Dimension</b></p>
<p>The AILCCP&rsquo;s Accountability principle requires in relevant part that &ldquo;AI system design and implementation examines output (decision-making or prediction); identifies gaps between predicted and achieved outcomes; [and] clearly reveals degree of compliance with Data Stewardship.&rdquo; The principle&rsquo;s FTC Angle field, which maps each principle to the angles through which the FTC would likely scrutinize, regulate, or take enforcement action, already listed &ldquo;Transparency, Accountability, Accuracy, Reliability, Advertising, Endorsements&rdquo; as the relevant enforcement dimensions, an anticipation of precisely this development.</p>
<p>Section 5 has always applied to AI companies, and the policy statement says so expressly. The novelty lies in the articulation of how the deception test reaches output steering, and in the implicit demand that companies maintain oversight structures capable of detecting when their systems operate outside the default expectation and of disclosing it when they do. Accountability&rsquo;s life cycle signals span three of the framework&rsquo;s ten life cycle phases: Scoping and Design, Pre-Deployment Review, and Operations and Monitoring. Those oversight structures must therefore be in place from system conception and persist through active monitoring.</p>
<p><b>The Governance Collision: Preemption and Colorado</b></p>
<p>The policy statement addresses Colorado&rsquo;s Artificial Intelligence Act, which provides that AI companies can be held liable for discriminatory outcomes caused by their customers&rsquo; use of their products. The FTC foresees that companies might steer their systems toward objectives such as &ldquo;equity&rdquo; or correction of &ldquo;historical injustices&rdquo; in order to comply with that law or others like it, without telling consumers. Its position is that such steering remains deceptive even when undertaken in good faith, and that &ldquo;state law is impliedly preempted to the extent it conflicts with a federal regulatory scheme.&rdquo; The policy statement grounds the preemption argument in Executive Order 14365, &ldquo;Ensuring a National Policy Framework for Artificial Intelligence&rdquo; (December 11, 2025), and its stated preference for a single, minimally burdensome national scheme over fifty discordant state frameworks.</p>
<p>The AILCCP Governance principle requires &ldquo;systems, policies, procedures, processes, roles, and responsibilities for managing AI risks throughout the AI life cycle&rdquo; and calls for continuous monitoring of the organization&rsquo;s regulatory obligations. Under the policy statement, a company that steers its outputs to satisfy a state equity mandate can create exposure under the federal prohibition on deceptive conduct. Organizations operating in Colorado, or in any state with similar legislation pending, face that conflict today.</p>
<p>The workable response to that conflict is to treat the policy statement as a disclosure architecture requirement. An organization whose system is steered for any reason, commercial, ideological, or compliance-driven, needs documented policies that make the steering visible to users in a manner satisfying the FTC&rsquo;s requirement.</p>
<p><b>What Changes for Practitioners</b></p>
<p>If adopted, the policy statement would make undisclosed deviation from what the FTC treats as truthful output presumptively deceptive; clear and conspicuous disclosure would become the only safe harbor; federal enforcement would reach output steering regardless of motive; and managing the federal-state conflict would require documented disclosure architecture.</p>
<p>The most substantive change would be the allocation of proof. Today, a company steering its system toward non-default objectives can argue that consumers hold no specific expectation about the system&rsquo;s internal objectives. The policy statement would articulate that expectation and place the burden of rebutting it on the company through adequate disclosure.</p>
<p><b>The Comment Period</b></p>
<p>A comment should engage the three places where the policy statement, measured against the AILCCP, falls short: the deception test&rsquo;s mechanics, the adequacy of the proposed safe harbor, and the preemption conflict with state mandates. General observations about AI oversight will carry little weight in the record.</p>
<p><b>Conclusion</b></p>
<p>The AILCCP framework is designed to give the AI oversight conversation a precise and durable vocabulary. Under the policy statement, principles that lived in internal policy documents and voluntary commitments will be written into enforceable legal obligations.</p>]]></content>
	<updated>2026-07-08T16:20:49+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-07-08T16:20:49+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="ai governance"/>

	<category term="ailccp"/>

	<category term="colorado ai act"/>

	<category term="eran kahana"/>

	<category term="ftc"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-07-06:/292755</id>
	<link href="https://law.stanford.edu/2026/07/06/getting-to-yes-key-environmental-and-energy-issues-impacting-data-center-development/" rel="alternate" type="text/html"/>
	<title type="html">Getting to Yes: Key Environmental and Energy Issues Impacting Data Center Development</title>
	<summary type="html"><![CDATA[<p>A hyperscaler data center project is one of the most legally complex developments a community can fa...</p>]]></summary>
	<content type="html"><![CDATA[<p>A hyperscaler data center project is one of the most legally complex developments a community can face, and the issues that decide whether it is completed successfully are numerous and technical, extending far beyond land use matters. In fact, the obligations most likely to halt development do not concern zoning at all, rather they are environmental and energy obligations, each enforceable by a different authority on its own timeline. For developer&rsquo;s counsel, the task is to create durable legal agreements and instruments that can hold for decades into the future.</p>
<p><strong>Retail Rate Structuring.</strong> Of every objection raised at a hearing &ndash; noise, water, jobs &ndash; electricity related concerns top them all: will the facility strain the grid, spike residential rates, or crowd out the load growth the community was counting on? These questions are best answered through legal structuring, not a communications campaign. The 2026 Ratepayer Protection Pledge &ndash; a White House initiative joined by Google, Microsoft, Meta, Oracle, xAI, OpenAI, and Amazon &ndash; commits operators to build, bring, or buy new generation and pay for triggered delivery upgrades, but it is only voluntary and politically contingent. No developer or concerned community for that matter should rely on such a voluntary pledge as more than a guide.</p>
<p>The value counsel adds is converting such a pledge into a binding instrument &ndash; for example, a ring-fenced cost-of-service rate class, negotiated bilaterally with the utility and written into the development agreement, protecting residential ratepayers and addressing the electricity related objections. Whatever generation the developer contracts must also qualify under applicable state procurement mandates (e.g., CEJA, CLCPA, VCEA), since a deal can meet commercial and rate goals yet still fail RPS compliance. And retail rates are set mainly by state Public Utility Commissions, which increasingly resist shifting new infrastructure costs onto households.</p>
<p><strong>Grid-Reliability and Demand-Response Covenants.</strong> Demand-response and regional-grid obligations are moving from voluntary to mandatory. PJM&rsquo;s May 2026 Board mandate accelerated its Reliability Backstop Procurement auction to September 2026 to allocate infrastructure costs directly to large data center loads, a framework counsel should build in upfront rather than retrofit later. Grid-reliability covenants, making backup capacity available to the grid operator during declared emergencies with appropriate FERC carve-outs, remain underused and turn an approval obstacle into a demonstrable benefit. Whether a local government can impose such a covenant without implicating FERC&rsquo;s exclusive jurisdiction is unsettled, but the bilateral-utility route navigates most of the preemption risk.</p>
<p><strong>Water Rights.</strong> In prior-appropriation states &ndash; Arizona, Nevada, Colorado, Utah, and much of Texas &ndash; water is a property right administered by state engineers and water courts and subject to suit by downstream holders entirely outside the local process. Municipal approval without a water right of sufficient priority is not a completed approval. At site selection, counsel should pin down the priority date, the call risk in a dry year, the protest exposure of any change application, and whether the right is certificated or merely claimed, remembering that interstate compacts such as the Colorado River and Rio Grande Compacts constrain even senior holders during shortage.</p>
<p><strong>Air Quality.</strong> Backup diesel generators are the most consistently overlooked air-quality trigger. In nonattainment areas &ndash; much of California, parts of the Northeast and Mid-Atlantic, and portions of Texas &ndash; a hyperscaler&rsquo;s generator fleet can require a major-source permit under the Clean Air Act, triggering a Best Available Control Technology (BACT) analysis and potentially scarce, expensive emissions offsets. Air permitting runs through federal and state air districts on a timeline independent of, and often longer than, local approval; closing on land and beginning site work first can materially misprice development risk.</p>
<p><strong>GHG Reporting and Cap-and-Trade Exposure.</strong> Cap-and-trade obligations can be easy to miss. A grid-connected data center is normally not a covered entity, because its footprint is purchased electricity, captured at the utility. But a &ldquo;bring your own energy&rdquo; project, e.g., on-site gas turbines used to sidestep interconnection queues, are an operator&rsquo;s own Scope 1 combustion emissions, and a hyperscaler fleet can certainly surpass the 25,000-ton compliance threshold under California&rsquo;s Cap-and-Invest program or Washington&rsquo;s Climate Commitment Act. When this happens, the data center becomes a covered entity owing allowances &ndash; a cost that must be priced in at site selection, not discovered by surprise after the turbines have been running. The Illinois POWER Act may be the start of a trend: following Governor Pritzker&rsquo;s June 5, 2026 pause on new data center tax incentives, it heads to the November veto session to convert voluntary BESS and diesel-control commitments into statutory conditions.</p>
<p>In each of these domains the rule is the same: the agreements that will survive scrutiny are the ones baked into enforceable instruments before construction begins &ndash; not the ones hoping for a voluntary pledge to hold or left to chance in the permitting process.</p>
<hr>
<p><a href="https://www.linkedin.com/in/mjschmitz/" rel="noopener noreferrer" target="_blank"><em>Michael Schmitz</em></a><em> and Catherine Atkin are the Co-Chairs of <a href="https://law.stanford.edu/codex-the-stanford-center-for-legal-informatics/projects/lawxclimate/" rel="noopener noreferrer" target="_blank">Stanford CodeX Law x Climate</a></em>.</p>]]></content>
	<updated>2026-07-06T13:33:28+00:00</updated>
	<author><name>Catherine Atkin, Michael Schmitz</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-07-06T13:33:28+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="codex"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-07-01:/292216</id>
	<link href="https://law.stanford.edu/2026/07/01/no-single-age-fits-all-a-neuroscience-approach-to-online-child-safety/" rel="alternate" type="text/html"/>
	<title type="html">No Single Age Fits All: A Neuroscience Approach to Online Child Safety</title>
	<summary type="html"><![CDATA[<p>Australia introduced a world-first law banning children under 16 from accessing social media platfor...</p>]]></summary>
	<content type="html"><![CDATA[<p>Australia introduced a world-first law banning children under 16 from accessing social media platforms. The Online Safety Amendment (Social Media Minimum Age), which took effect in December 2025, requires providers of social media platforms to take reasonable steps to prevent Australians under 16 from having accounts, or face civil penalties. Similarly, the UK government has announced that from Spring 2027 children under 16 will be prohibited from accessing certain social media platforms. Several other countries, including Denmark, France, Germany, Indonesia, Norway, and Spain, have introduced or adopted similar approaches. If different jurisdictions and platforms are setting different age thresholds, does neuroscience actually support a single fixed age?</p>
<p>Based on neuroscience, there is no single age that should be considered safe or unsafe for children&rsquo;s exposure to social media platforms. Brain development and maturation are continuous, individualized, and multidimensional. However, legal and platform age thresholds vary across jurisdictions, generally ranging from 13 to 18 years old. The growing number of these measures reflects increasing fragmentation and the urgency of addressing online child safety. Cultural differences regarding childhood autonomy, parental authority, and online privacy further complicate efforts to define the right age.&nbsp; Instead of establishing fixed age thresholds, online child safety may be better served by regulations that target platform designs and variable reward systems in ways calibrated to users&rsquo; developmental stages.</p>
<h3><strong>The &ldquo;Right&rdquo; Age?</strong></h3>
<p>Age assurance approaches vary across countries. In particular, the European Union member states reflect the flexibility provided under the General Data Protection Regulation (GDPR). The GDPR sets 16 as the age for a child&rsquo;s independent consent for information-society services, while allowing member states to lower the threshold to 13.[1] In April 2026, the European Union further strengthened its approach by announcing the deployment of an age verification app enabling users to verify their age when accessing online services.[2] This approach introduces age-verification infrastructure rather than setting new legal thresholds. Moreover, the United States has adopted a threshold for children&rsquo;s personal data processing. The Children&rsquo;s Online Privacy Protection Act of 1998 (COPPA) requires covered online services to obtain verifiable parental consent before collecting, using, or disclosing personal information from children under 13.[3] While such requirements are absent at the federal level, age assurance and verification thresholds are implemented under state laws.[4]</p>
<p>Social media platforms&rsquo; policies are shaped by this regulatory fragmentation. Major social media platforms, such as Facebook,[5] Instagram,[6] TikTok,[7] and X,[8] explicitly adhere to a 13-year-old threshold, prohibiting users below this age from creating accounts or redirecting them to age-appropriate experiences. However, varied age thresholds have been adopted for specific policies across platforms, such as restricting specific features like direct messaging or content access settings. The appeal of the fixed thresholds is that they are simple to enforce and provide clear expectations for users, parents, platforms, and regulators. These measures raise a question: does neuroscience actually support a single age cutoff?</p>
<h3><strong>What Neuroscience Tells Us and Why It Does Not Give A Number</strong></h3>
<p>The limbic system governs emotional processing and rewards. This system shows increased sensitivity during puberty because hormonal changes increase an individual&rsquo;s responsiveness to rewards and social&nbsp; feedback. In contrast, the prefrontal cortex is responsible for impulse control, planning, and risk assessment, and is one of the last parts of the brain to fully develop. While the full maturity of the prefrontal cortex is estimated to occur by the mid-twenties, approximately 25 years old,[9] this is not absolute. Brain development varies across different people. Some individuals reach a plateau earlier, while others experience maturation that extends even further.[10]</p>
<p>The fact that emotional responsiveness and sensation-seeking develop earlier than self-regulation creates a developmental mismatch. While this imbalance between the dual systems has become a dominant framework for understanding adolescent risk-taking, the model has been contested as an oversimplification. The same child may be cognitively competent, but still psychosocially vulnerable. Although this imbalance is a general pattern, it does not occur at a specific age. Brain development is better understood as a gradient rather than a threshold. Different cognitive and psychosocial capacities emerge at different times and vary significantly across children. Therefore, a single age threshold is both over- and under-inclusive. It restricts children who can understand and engage with specific features before the specified age, while failing to protect other children who are not ready. Neuroscience offers developmental patterns, but it does not directly determine the appropriate regulatory thresholds, which remain policy choices.</p>
<h3><strong>How Platform Design Interacts with Developing Brains</strong></h3>
<p>Platform designs may influence adolescent behavior and engagement patterns during brain development. Features such as personalized content, infinite scroll, and unpredictable notifications (such as likes, shares, or comments) may function as variable-ratio reward mechanisms. These features are associated with dopamine-related reward responses and may increase engagement, potentially contributing to more compulsive use patterns.[11] Young users whose prefrontal cortex is still developing could be more susceptible to peer influence. They may experience heightened sensitivity to social approval and rejection.[12]</p>
<p>While there is no clear age threshold, neuroscience could explain that different risks align with &nbsp;different brain developmental timelines. The feature-based approach suggests a shift from one-size-fits-all age thresholds to regulations that tailor platform features to users&rsquo; developmental stages. By tailoring platform features to users&rsquo; developmental stages, this approach addresses the actual sources of harm. Although more complex to implement than a single age cutoff, it may better align protections with the risks children face at different stages.</p>
<p>Some social media platforms have moved toward this approach. For example, TikTok sets a default daily screen time of 60 minutes for users aged 13-17.[13] It disables push notifications from 9 PM for users aged 13-15, and 10 PM for those aged 16-17.[14] Similarly, Facebook has implemented the Facebook Teen Accounts for users aged 13-17, automatically applying more protective settings and sleep mode, as well as a daily limit reminder by default.[15] Instagram restricts direct messaging between users identified as teens and unknown users over 18.[16] These examples suggest that platforms already operate on a gradient model in practice.</p>
<p>Beyond these default age-related features, many platforms allow parents or guardians to set up features appropriately for their children. Their developmental needs may be best understood by their parents or guardians. For example, YouTube&rsquo;s Kids account allows signed-in parents to select a content experience for their children from preschool (ages 4 and under), younger (ages 5-8), older (ages 9-12), or a customized selection where parents approve content themselves.[17] These measures also reflect broader issues about platform responsibility. In the United States, recent product-liability verdicts have increased attention to claims involving allegedly addictive software design.</p>
<h3><strong>Moving Forward &amp; Open Questions</strong></h3>
<p>There is no single right age. But there are design features that may be more or less appropriate at different developmental stages. Neuroscience helps explain this developmental gap. Specifically, reward systems and platform features may affect children differently. However, the precise thresholds, such as how many notifications or how much screen time trigger harm remain unclear.</p>
<p>Some social media platforms have implemented age-tiered approaches, but broader regulatory development is needed. Some level of age assurance remains necessary. It is still important for platforms to know a user&rsquo;s approximate age in order to apply age-tiered protection effectively. However, a regulatory framework should treat age as a gradient, not a single gatekeeping threshold. Requirements should move beyond relying exclusively on fixed age thresholds and be built around risk- and design-based models. Platforms should still be required to assess risks and adapt their features to users&rsquo; age-related and developmental needs.</p>
<p>A feature-level approach is not perfect, but it is more closely aligned with how risk actually occurs. While more complex to enforce than a single age cutoff, this approach better balances the goal of mitigating online harms to children while preserving their access to social media. At the same time, the law should limit harms arising from age assurance or verification tools themselves, such as data privacy risks. Looking ahead, deeper collaboration between neuroscientists, platforms, and regulators will be necessary to refine this approach.</p>
<h3><strong>References</strong></h3>
<p>[1] EU GDPR Article 8, Conditions Applicable to Child&rsquo;s Consent in Relation to Information Society Services.</p>
<p>[2] European Commission, European Age Verification App to Keep Children Safe Online, April 2026, <a href="https://commission.europa.eu/news-and-media/news/european-age-verification-app-keep-children-safe-online-2026-04-15_en" rel="noopener noreferrer" target="_blank">https://commission.europa.eu/news-and-media/news/european-age-verification-app-keep-children-safe-online-2026-04-15_en</a>.</p>
<p>[3] &sect; 312.2 Definitions (defining &ldquo;child&rdquo; as an individual under the age of 13) and &sect; 312.5 Parental Consent.</p>
<p>[4] Texas&rsquo;s Securing Children Online Through Parental Empowerment (SCOPE) Act requires a digital service provider to register the age of the user, and users under 18 years old must obtain parental or guardian consent before creating an account; <em>see also</em>, Free Speech Coalition v. Paxton.</p>
<p>[5] Meta, Terms of Services, version 1 January 2025, <a href="https://www.facebook.com/terms/" rel="noopener noreferrer" target="_blank">https://www.facebook.com/terms/</a>.</p>
<p>[6] Instagram, Terms of Use, <a href="https://help.instagram.com/termsofuse" rel="noopener noreferrer" target="_blank">https://help.instagram.com/termsofuse</a>.</p>
<p>[7] TikTok, Terms of Services, version 22 January 2026, <a href="https://www.tiktok.com/legal/page/us/terms-of-service/en" rel="noopener noreferrer" target="_blank">https://www.tiktok.com/legal/page/us/terms-of-service/en</a>.</p>
<p>[8] X, Terms of Services, version 17 December 2025, <a href="https://x.com/en/tos" rel="noopener noreferrer" target="_blank">https://x.com/en/tos</a>.</p>
<p>[9] Mariam Arain et al., <em>Maturation of the Adolescent Brain </em>(2013), <a href="https://pmc.ncbi.nlm.nih.gov/articles/PMC3621648/" rel="noopener noreferrer" target="_blank">https://pmc.ncbi.nlm.nih.gov/articles/PMC3621648/</a>.</p>
<p>[10] Leah H. Somerville, <em>Searching for Signatures of Brain Maturity: What Are We Searching For? </em>(2016), <a href="https://www.sciencedirect.com/science/article/pii/S0896627316308091" rel="noopener noreferrer" target="_blank">https://www.sciencedirect.com/science/article/pii/S0896627316308091</a>; <em>see also</em>, Kathryn L Mills et al., <em>Inter-Individual Variability in Structural Brain Development from Late Childhood to Young Adulthood</em> (2021),<a href="https://pmc.ncbi.nlm.nih.gov/articles/PMC8489572/" rel="noopener noreferrer" target="_blank">https://pmc.ncbi.nlm.nih.gov/articles/PMC8489572/</a>.</p>
<p>[11] Jiangsong Wang and Shen Wang, <em>The Emotional Reinforcement Mechanism of and Phased Intervention Strategies for Social Media Addiction</em> (2025), &nbsp;<a href="https://pubmed.ncbi.nlm.nih.gov/40426443/" rel="noopener noreferrer" target="_blank">https://pubmed.ncbi.nlm.nih.gov/40426443/</a>.</p>
<p>[12] Eveline A. Crone and Elly A. Konjin, <em>Media Use and Brain Development During Adolescence </em>(2018),<a href="https://www.nature.com/articles/s41467-018-03126-x" rel="noopener noreferrer" target="_blank">https://www.nature.com/articles/s41467-018-03126-x</a>; <em>see also</em>, Patrik Wikman et al., <em>Brain Responses to Peer Feedback in Social Media Are Modulated by Valence in Late Adolescence</em> (2022), <a href="https://pubmed.ncbi.nlm.nih.gov/35706832/" rel="noopener noreferrer" target="_blank">https://pubmed.ncbi.nlm.nih.gov/35706832/</a>.</p>
<p>[13] TikTok, Guardian&rsquo;s Guide, <a href="https://www.tiktok.com/safety/en/tools-and-guides/guardians-guide" rel="noopener noreferrer" target="_blank">https://www.tiktok.com/safety/en/tools-and-guides/guardians-guide</a>.</p>
<p>[14] Id.</p>
<p>[15] Facebook, Help Centre, About Facebook Teen Accounts, <a href="https://www.facebook.com/help/1105851604342488" rel="noopener noreferrer" target="_blank">https://www.facebook.com/help/1105851604342488</a>.</p>
<p>[16] Instagram, Help Center, About Instagram Teen Privacy and Safety Settings, <a href="https://help.instagram.com/3237561506542117" rel="noopener noreferrer" target="_blank">https://help.instagram.com/3237561506542117</a>.</p>
<p>[17] YouTube, For Families Help, Help Center, Create a YouTube Kids Profile, <a href="https://support.google.com/youtubekids/answer/7554914?hl=en" rel="noopener noreferrer" target="_blank">https://support.google.com/youtubekids/answer/7554914?hl=en</a>.</p>]]></content>
	<updated>2026-07-01T10:07:51+00:00</updated>
	<author><name>Natnicha Sutthivana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-07-01T10:07:51+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>

	<category term="bioethics"/>

	<category term="neuroscience"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-06-25:/291088</id>
	<link href="https://law.stanford.edu/2026/06/25/new-article-ulysses/" rel="alternate" type="text/html"/>
	<title type="html">New Article in Stanford Computational Antitrust: Ulysses, A Case Outcome Predictor</title>
	<summary type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces the publication of &ldquo;Ulysses: A Case Outcome P...</p>]]></summary>
	<content type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces the publication of &ldquo;<a href="https://law.stanford.edu/publications/ulysses-a-case-outcome-predictor-for-computational-antitrust/" rel="noopener noreferrer" target="_blank">Ulysses: A Case Outcome Predictor for Computational Antitrust</a>&rdquo; by Piero Alexis Malca Vilchez, C&eacute;sar Humberto Qui&ntilde;ones Costa, and Enzo Rodrigo Gomez Rojas. The article appears in Volume 6 of Stanford Computational Antitrust (pp. 140&ndash;166).</p>
<p>Can a large language model predict whether a business practice will be found anticompetitive? The authors build a tool that answers the question for one jurisdiction. They take Peruvian competition law as their case study and construct a case outcome predictor. The design is meant to be replicated. An enforcer or a practitioner elsewhere can follow the same framework and adapt it to a given practice under a given legal regime.</p>
<p>The method matters as much as the result. The authors do not retrain a model. They guide it with legal expertise through prompting and retrieval-augmented generation. The system retrieves past case law and structures the legal reasoning around it. This keeps current assessments closer to prior administrative precedent and improves consistency across decisions. It also lowers the barrier to building such a tool, since no model retraining is required.</p>
<p>The authors are careful about scope. Their results are preliminary. The benchmark is a small proof of concept rather than a full validation. They present Ulysses as a demonstration of what domain-adapted legal workflows can do for specialized legal judgment prediction, not as a finished enforcement instrument.</p>
<p>Thibault Schrepel, founder of the Stanford Computational Antitrust Project, stated:</p>
<blockquote>
<p>&ldquo;This paper makes a useful point. You do not need to retrain a model to build a working legal prediction tool. You need legal experts who know the case law and a careful retrieval design. The authors prove it on Peruvian competition law, and they hand others a framework to follow. That is how computational antitrust reaches jurisdictions without large engineering teams. I value the honesty about the limits as much as the result.&rdquo;</p>
</blockquote>
<p>The article is available for download on the <a href="https://law.stanford.edu/publications/ulysses-a-case-outcome-predictor-for-computational-antitrust/" rel="noopener noreferrer" target="_blank">Stanford Computational Antitrust project&rsquo;s page</a>.</p>]]></content>
	<updated>2026-06-25T18:10:13+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-06-25T18:10:13+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-06-17:/290610</id>
	<link href="https://law.stanford.edu/2026/06/17/new-article-richard-may/" rel="alternate" type="text/html"/>
	<title type="html">New Article in Stanford Computational Antitrust: Generative AI Use by Antitrust Agencies</title>
	<summary type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces the publication of &ldquo;Generative AI Use by Comp...</p>]]></summary>
	<content type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces the publication of &ldquo;<a href="https://law.stanford.edu/publications/generative-ai-use-by-competition-authorities-why-why-not-and-what-might-be/" rel="noopener noreferrer" target="_blank">Generative AI Use by Competition Authorities: Why, Why Not, and What Might Be</a>&rdquo; by Richard May. The article appears in Volume 6 of <em>Stanford Computational Antitrust</em> (pp. 112-138).</p>
<p>Antitrust agencies can use AI to gather intelligence and to run their operations more efficiently. They can build tools in-house or rely on outside providers. The article examines what this adoption can deliver and what stands in its way. The potential gains are large. The risks are real. Some are particular to AI. Others come with any new technology.</p>
<p>The article argues that a top-down governance strategy matters most. Authorities need guardrails to manage the risks. They need scaling plans to turn early experiments into lasting capacity. Cooperation among authorities adds further value, since few agencies can address these problems alone. The article also looks beyond enforcement tooling. It asks whether AI might itself support pro-competitive intervention, for example through AI-based consumer agents acting on behalf of users. May treats this as a prospect rather than a recommendation. He argues it is too early to advocate such measures, while their potential merits further study.</p>
<p>Thibault Schrepel, founder of the Stanford Computational Antitrust Project, stated:</p>
<blockquote>
<p>&ldquo;Richard May moves the discussion past whether agencies should adopt AI toward how they should govern it. His focus on guardrails and scaling plans gives authorities a workable agenda. The closing reflection on AI-based consumer agents points to where the harder questions now sit.&rdquo;</p>
</blockquote>]]></content>
	<updated>2026-06-17T14:28:04+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-06-17T14:28:04+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-06-11:/290064</id>
	<link href="https://www.gautrais.com/conferences/rse-rne/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=rse-rne" rel="alternate" type="text/html"/>
	<title type="html">RSE / RNE, A-3421 + Zoom(10 juin 2026)</title>
	<summary type="html"><![CDATA[<p>Cette conf&eacute;rence explore les mutations de la Responsabilit&eacute; sociale des entreprises (RSE) vers la re...</p>]]></summary>
	<content type="html"><![CDATA[<div dir="auto">Cette conf&eacute;rence explore les mutations de la Responsabilit&eacute; sociale des entreprises (RSE) vers la responsabilit&eacute; num&eacute;rique des entreprises (RNE). Nos experts acad&eacute;mique analyseront les &eacute;volutions et questionnements &agrave; l&rsquo;oeuvre.</div>
<div dir="auto"></div>
<div dir="auto">Venez &eacute;couter la professeure <strong>G&eacute;raldine Goffaux Callebaut</strong> (Facult&eacute; de droit, Universit&eacute; d&rsquo;Orl&eacute;ans) accompagn&eacute;e du professeur <strong>Pierre Larouche</strong> (Facult&eacute; de droit, UdeM) qui partageront leurs r&eacute;flexions sur ce sujet&nbsp;!</div>
<div dir="auto"></div>
<div dir="auto">&#128205; En personne &agrave; l&rsquo;Universit&eacute; de Montr&eacute;al (A-3421);</div>
<div dir="auto">&#128250; Diffusion en direct sur Zoom;</div>
<div dir="auto">&#128351; 16h30 | 1 heure 30 de formation continue reconnue</div>
<div dir="auto"></div>
<div dir="auto">&#128073; Inscription gratuite&nbsp;:<strong>&nbsp;<a href="https://fcdroit.umontreal.ca/Web/MyCatalog/ViewP?pid=OPWhgFdTt9fynJhm%2fIXQ4A%3d%3d&amp;id=5SPrK8RrPxi23WLR57jz%2bg%3d%3d&amp;cvState=cvDate=09-04-2026" rel="noopener noreferrer" target="_blank">ici&nbsp;!</a></strong></div>
<div dir="auto"></div>
<div dir="auto">
<p><b>Pourquoi participer&nbsp;?</b><br>
Cette conf&eacute;rence est une occasion unique de r&eacute;fl&eacute;chir sur la mani&egrave;re dont les choix techniques fa&ccedil;onnent nos vies quotidiennes et de questionner la responsabilit&eacute; des acteurs num&eacute;riques dans la r&eacute;gulation et la transparence de leurs syst&egrave;mes. Que vous soyez juriste, technicien, chercheur ou simplement curieux des enjeux contemporains li&eacute;s aux technologies, cet &eacute;v&eacute;nement vous offrira des pistes de r&eacute;flexion essentielles.</p>
<p>&nbsp;</p>
<p><b>Inscrivez-vous d&egrave;s aujourd&rsquo;hui et venez enrichir votre vision des technologies et de leur impact sur notre soci&eacute;t&eacute;&nbsp;!</b></p>
</div>]]></content>
	<updated>2026-06-10T23:49:53+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-06-10T23:49:53+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-06-09:/289930</id>
	<link href="https://law.stanford.edu/2026/06/09/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954/" rel="alternate" type="text/html"/>
	<title type="html">Can Machines Think? – Revisiting the Alan Turing vs. John Searle Debate</title>
	<summary type="html"><![CDATA[<p>In memory of Alan Turing (23 June 1912 &ndash; 7 June 1954)
Can a machine genuinely think, understand, or...</p>]]></summary>
	<content type="html"><![CDATA[<p><img fetchpriority="high" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954.png" alt="Can Machines Think? - Revisiting the Alan Turing vs. John Searle Debate In memory of Alan Turing (23 June 1912 &ndash; 7 June 1954)" srcset="https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954.png 900w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954-300x200.png 300w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954-768x512.png 768w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954-120x80.png 120w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954-450x300.png 450w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954-220x147.png 220w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954.png 900w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954-300x200.png 300w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954-768x512.png 768w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954-120x80.png 120w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954-450x300.png 450w,https://law.stanford.edu/wp-content/uploads/2026/06/can-machines-think-revisiting-the-alan-turing-vs-john-searle-debate-in-memory-of-alan-turing-23-june-1912-7-june-1954-220x147.png 220w" sizes="(max-width: 900px) 100vw, 900px" referrerpolicy="no-referrer" loading="lazy"></p>
<p><em>In memory of Alan Turing (23 June 1912 &ndash; 7 June 1954)</em></p>
<p>Can a machine genuinely think, understand, or have a mind? Or, in other words, can machines possess intelligence?</p>
<p>One may argue that the answer depends on how we define intelligence. Is intelligence simply the ability to produce intelligent behavior? Or does real intelligence require inner understanding, consciousness, and maybe even the unconscious?</p>
<p>Two of the most important positions in this debate come from Alan Turing&rsquo;s &ldquo;imitation game&rdquo; and John Searle&rsquo;s &ldquo;Chinese room argument.&rdquo; Turing shifted the question toward behavior: if a machine can perform intelligently enough that we cannot distinguish it from a human, then we have reason to call it intelligent. Searle pushed back: producing the right output is not the same as understanding what the output means.</p>
<p>Let&rsquo;s first briefly review the two sides.</p>
<p><strong>Alan Turing&rsquo;s imitation game, proposed in 1950</strong></p>
<p>In 1950, Alan Turing proposed the &ldquo;imitation game&rdquo; to move beyond the vague question &ldquo;Can machines think?&rdquo; Instead of asking whether a machine has a soul, inner feelings, or a human-like mind, Turing focused on observable performance. If a human judge, communicating only through written language, cannot reliably distinguish between a machine and a human, then the machine has passed the test.</p>
<p>Turing&rsquo;s move was powerful because it made the question testable. Rather than trying to look inside the machine for an invisible essence called &ldquo;thinking,&rdquo; he asked us to evaluate what the machine can do. In this sense, Turing&rsquo;s approach is behavior-focused and functional: intelligence is judged by performance.</p>
<p>But this also creates a problem. Does intelligent behavior prove intelligence, or does it only imitate intelligence?</p>
<p><strong>John Searle&rsquo;s Chinese room argument, proposed in 1980</strong></p>
<p>John Searle&rsquo;s Chinese room argument was designed to challenge exactly this problem. He wanted to distinguish between symbol manipulation and actual understanding.</p>
<p>In his thought experiment, imagine a native English speaker locked in a room. This person does not understand Chinese. Inside the room, there are Chinese symbols and very detailed rulebooks written in English. Someone outside the room slips questions in Chinese under the door. The person inside follows the rules and produces perfectly coherent responses in Chinese.</p>
<p>To the person outside the room, it appears that the person inside understands Chinese. But from the inside, there is no understanding. The person is only manipulating symbols according to formal rules.</p>
<p>Searle&rsquo;s point is that syntax is not the same as semantics. A system may process symbols correctly without understanding their meaning. For Searle, this means that computation alone is not sufficient for genuine understanding.</p>
<p><strong>Are Turing and Searle views enough?</strong></p>
<p>Are these two views necessary and sufficient to answer whether machines can possess intelligence? I do not think so.</p>
<p>Turing gives us an important condition: if a machine thinks, it should probably be able to behave intelligently. But behaving intelligently is not enough to prove that the machine actually thinks. A good example is the current state of large language models. With their language capabilities, it is getting easier for LLMs to perform well on Turing-style tests. It is also getting harder to distinguish between human and machine performance, especially when the task is clearly defined and the success metric is measurable.</p>
<p>But this does not settle the question. LLMs can produce responses that look like reasoning while still making mistakes in logic, common sense, grounding, and time. They can sound coherent without necessarily having a stable model of the world. This is why I do not think that predicting the next token from an enormous amount of data, by itself, fully answers the question of machine thinking.</p>
<p>On the other hand, Searle&rsquo;s Chinese room also raises a question for me. What happens if the process inside the room is repeated thousands or millions of times? What happens if we add memory, feedback, learning, and the ability to connect symbols to action and experience? If the person or system changes over time, learns from past experiences and from semantic understanding in English, and begins to use the symbols in flexible and meaningful ways, is it still just symbol manipulation?</p>
<p>This is where the argument becomes more complicated. Humans also learn language through repeated exposure, correction, memory, association, and social use. We do not begin with full understanding. We build it gradually. So, the question is not only whether symbol manipulation is enough. The deeper question is: what must be added to symbol manipulation for understanding to emerge, if it can emerge at all?</p>
<p><strong>Intelligence, Thinking, and Reasoning</strong></p>
<p>I am not sure whether intelligence and thinking are the same thing. Maybe intelligence is a capacity for solving problems, while thinking is a broader mental process. Maybe thinking is one tool of intelligence. Or maybe intelligence, thinking, understanding, and consciousness are deeply connected in ways we still do not understand.</p>
<p>On the thinking side, Daniel Kahneman&rsquo;s distinction between System 1 and System 2 is useful. System 1 is fast, intuitive, and automatic. System 2 is slow, deliberate, and effortful. This distinction loosely echoes some of the current language around LLM reasoning models: some systems produce immediate answers, while others are designed to reason more slowly and explicitly.</p>
<p><strong>Consciousness, the Unconscious, and the Missing Piece</strong></p>
<p>But the human mind has other aspects that are mostly missing from the classic Turing-Searle debate or the system1-system2 distinctions: consciousness and the unconscious.</p>
<p>The definitions of consciousness and the unconscious are still debated. But a simple starting point is this: consciousness is the capacity to experience, feel, perceive, or be aware of oneself and the world from a first-person point of view. The unconscious is the set of mental processes that influence thoughts, feelings, behavior, memory, and perception without being directly available to awareness.</p>
<p>These concepts matter because human intelligence is not only explicit reasoning. Much of what we call understanding depends on background perception, emotion, memory, bodily experience, attention, intuition, and unconscious processing. A person does not only manipulate symbols. A person lives in a world, acts in that world, feels consequences, and builds meaning through experience.</p>
<p>Philip Goff, in his 2019 book <em>Galileo&rsquo;s Error: Foundations for a New Science of Consciousness</em>, argues that modern science became powerful partly by leaving consciousness out of its picture of nature. That move helped science describe the objective, measurable world, but it also left us with a hard problem: how do we explain subjective experience itself?</p>
<p>This is why the question &ldquo;Can machines think?&rdquo; cannot be answered only by looking at external behavior or internal computation. Turing shows us why behavior matters. Searle shows us why behavior may not be enough. But neither fully answers what thinking is.</p>
<p>To answer whether machines possess intelligence, or whether they can actually think, we may need a deeper theory of the human mind first. The Turing-Searle debate is not only about AI. It is part of a larger debate over whether mind is behavior, computation, brain activity, biological consciousness, causal role, embodied experience, or something else entirely.</p>
<p>Maybe the real question is not simply whether machines can think. The real question is what we mean by thinking in the first place.</p>]]></content>
	<updated>2026-06-09T12:08:10+00:00</updated>
	<author><name>Marzieh Nabi</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-06-09T12:08:10+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="codex"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-06-03:/289469</id>
	<link href="https://www.gautrais.com/conferences/preuve-ia/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=preuve-ia" rel="alternate" type="text/html"/>
	<title type="html">Preuve + IA, Preuve + IA: À l’ère où l’IA brouille la fiabilité des éléments de preuve, faut-il ajouter le « flair numérique » aux aptitudes des décideurs ? , Tribunal administratif du travail (TAT ) (Montréal) (2 juin 2026)</title>
	<summary type="html"><![CDATA[]]></summary>
	<content type="html"><![CDATA[]]></content>
	<updated>2026-06-02T20:06:25+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-06-02T20:06:25+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-05-29:/289028</id>
	<link href="https://www.gautrais.com/conferences/lia-humanite/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=lia-humanite" rel="alternate" type="text/html"/>
	<title type="html">L&amp;#8217;IA + humanité, École d&#039;été en droit international appliqué - Droit international, intelligence artificielle et gouvernance du numérique, Université de Sherbrooke (Longueuil) - Salle L1-3660(29 mai 2026)</title>
	<summary type="html"><![CDATA[]]></summary>
	<content type="html"><![CDATA[]]></content>
	<updated>2026-05-29T10:01:27+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-05-29T10:01:27+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-05-28:/288902</id>
	<link href="https://www.gautrais.com/conferences/les-enjeux-juridiques-de-lintelligence-artificielle-pour-les-pme/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=les-enjeux-juridiques-de-lintelligence-artificielle-pour-les-pme" rel="alternate" type="text/html"/>
	<title type="html">Les enjeux juridiques de l’intelligence artificielle pour les PME(28 mai 2026)</title>
	<summary type="html"><![CDATA[<p>Les enjeux juridiques de l&rsquo;intelligence artificielle pour les PME
Peut-on se lancer dans l&rsquo;aventure ...</p>]]></summary>
	<content type="html"><![CDATA[<h3>Les enjeux juridiques de l&rsquo;intelligence artificielle pour les PME</h3>
<p>Peut-on se lancer dans l&rsquo;aventure de l&rsquo;IA sans pr&eacute;paration? M&ecirc;me si le cadre juridique demeure encore &agrave; parfaire, il existe d&eacute;j&agrave; des textes l&eacute;gaux et &eacute;thiques qui invitent les acteurs publics et priv&eacute;s &agrave; faire preuve de diligence dans la mani&egrave;re de d&eacute;velopper et d&rsquo;utiliser l&rsquo;IA. Cette pr&eacute;sentation vise &agrave; vous sensibiliser aux bonnes pratiques et aux avenues &agrave; privil&eacute;gier pour &eacute;voluer de fa&ccedil;on responsable avec l&rsquo;IA.</p>
<h4>&Agrave; qui s&rsquo;adresse l&rsquo;atelier</h4>
<p>Aux gestionnaires, aux responsables l&eacute;gaux, aux strat&egrave;ges num&eacute;riques et aux dirigeants de PME souhaitant explorer l&rsquo;IA et booster leur visibilit&eacute; en ligne.</p>
<h4>Ce que vous allez concr&egrave;tement retirer de la conf&eacute;rence</h4>
<ul>
<li>Une meilleure compr&eacute;hension des enjeux juridiques et &eacute;thiques li&eacute;s &agrave; l&rsquo;intelligence artificielle</li>
<li>Des pistes d&rsquo;action concr&egrave;tes &agrave; mettre en place d&egrave;s aujourd&rsquo;hui</li>
</ul>
<h4>D&eacute;roulement d&eacute;taill&eacute; de chaque rencontre</h4>
<ul>
<li>30 minutes&nbsp;: Accueil des participants</li>
<li>15 minutes&nbsp;: Mot de bienvenue</li>
<li>75 minutes&nbsp;: Conf&eacute;rence par un expert invit&eacute;</li>
<li>10 minutes&nbsp;: Pause</li>
<li>70 minutes&nbsp;: Atelier d&rsquo;int&eacute;gration de l&rsquo;IA
<ul>
<li>10 minutes&nbsp;: Mise en contexte &ndash; Pr&eacute;sentation des objectifs de l&rsquo;analyse collective.</li>
<li>25 minutes&nbsp;: Travail en sous-groupes &ndash; D&eacute;termination des t&acirc;ches automatisables, des leviers IA et des gains potentiels (temps, co&ucirc;ts, revenus).</li>
<li>20 minutes&nbsp;: Mise en commun structur&eacute;e &ndash; Partage des recommandations et organisation des id&eacute;es selon trois axes (automatisation, aide &agrave; la d&eacute;cision et optimisation).</li>
<li>15 minutes&nbsp;: Synth&egrave;se strat&eacute;gique &ndash; D&eacute;termination des &laquo;&nbsp;quick wins&nbsp;&raquo; &agrave; court terme, des projets structurants et des indicateurs de performance &agrave; suivre.</li>
</ul>
</li>
<li>10 minutes&nbsp;: Mot de la fin</li>
</ul>
<h4>Sujets abord&eacute;s</h4>
<ul>
<li aria-level="1">Aspects juridiques</li>
<li aria-level="1">Enjeux &eacute;thiques</li>
<li aria-level="1">Actions &agrave; mettre en place d&egrave;s maintenant</li>
</ul>
<h4>Pourquoi participer</h4>
<p>Notre approche est ax&eacute;e sur les solutions concr&egrave;tes et pas seulement sur la th&eacute;orie. Nous combinons les deux afin que vous ayez tout en main pour implanter les meilleures pratiques IA dans votre organisation.</p>
<p>Suivant la conf&eacute;rence, nous vous proposons un atelier collaboratif pour mettre en pratique les notions apprises et &eacute;changer de fa&ccedil;on plus personnalis&eacute;e avec notre expert.</p>
<h4>Expert conf&eacute;rencier</h4>
<p><b>Vincent Gautrais</b>&nbsp;&mdash;&nbsp;Chercheur au CRDP, professeur titulaire &agrave; la Facult&eacute; de droit de l&rsquo;Universit&eacute; de Montr&eacute;al, et titulaire de la Chaire L.R. Wilson sur le droit des technologies de l&rsquo;information et du commerce &eacute;lectronique.</p>
<h4>Animation</h4>
<p>Matthieu Lirette-G&eacute;linas &mdash;&nbsp;<a href="https://maverick-analytik.ca/" target="_blank" rel="noopener noreferrer">Maverick Analytik</a></p>
<p><strong>Limite de 40 participants. Bienvenue &agrave; tous!</strong></p>]]></content>
	<updated>2026-05-28T10:31:48+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-05-28T10:31:48+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-05-23:/288544</id>
	<link href="https://law.stanford.edu/2026/05/23/new-article-anselm-kusters/" rel="alternate" type="text/html"/>
	<title type="html">New Article in Stanford Computational Antitrust: Competition in the Press: A Computational Analysis of U.S.–German Newspaper Discourse (1870–1945)</title>
	<summary type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces the publication of &ldquo;Competition in the ...</p>]]></summary>
	<content type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces the publication of &ldquo;Competition in the Press: A Computational Analysis of U.S.&ndash;German Newspaper Discourse (1870&ndash;1945)&rdquo; by Anselm K&uuml;sters. The article appears in Volume 6 of Stanford Computational Antitrust (pp. 68&ndash;111).</p>
<p>What do people mean when they talk about competition? K&uuml;sters answers the question with a corpus of approximately 1.1 million digitized newspaper articles published in the United States and Germany between 1870 and 1945. The analysis proceeds in three steps. Keyword frequencies establish the vocabulary surrounding competition in each national press. Dynamic topic modeling tracks how thematic clusters shift across decades. Cross-lingual semantic embeddings then measure where competition discourse sits between economic-administrative vocabulary on one side and war-and-contest vocabulary on the other.</p>
<p>The two countries diverge sharply. In the German press, competition migrated from civic-commercial vocabulary in the 1870s toward organized performance, order, and martial imagery by the 1930s. In the American press, competition stayed anchored to institutional and economic vocabulary throughout the period. The divergence predates the Sherman Antitrust Act of 1890. K&uuml;sters reads this as evidence that the two legal regimes were built on pre-existing semantic foundations rather than the reverse.</p>
<p>The article connects the historical analysis to present-day enforcement. K&uuml;sters traces a continuity from the German press&rsquo;s framing of competition as a rule-bound contest to the legal doctrine of Leistungswettbewerb, the German concept typically translated as competition on the merits.&rdquo; He then argues that machine-learning screening tools and large language models trained predominantly on one national tradition will reproduce that tradition&rsquo;s implicit frames. A model trained on U.S. enforcement records learns to associate harmful conduct with terms such as conspiracy, foreclosure, and market share. The same conduct described in German or EU text data may be associated with orderly competition, fair trading, and performance. As enforcement agencies move toward algorithmic screening, this cross-lingual semantic mismatch becomes a concrete risk.</p>
<p>Thibault Schrepel, founder of the Stanford Computational Antitrust Project, stated:</p>
<blockquote>
<p>&ldquo;K&uuml;sters shows that the semantic foundations of competition law diverged across jurisdictions before the statutes were written. He then closes the loop with a warning that matters now. Algorithmic enforcement tools inherit those foundations from their training data. Agencies adopting these tools without auditing their jurisdictional coverage will import one tradition&rsquo;s assumptions about what competition is into another tradition&rsquo;s enforcement decisions. That is the kind of finding the field needs at this moment.&rdquo;</p>
</blockquote>
<p>Anselm K&uuml;sters is affiliated with the Max Planck Institute for Legal History and Legal Theory in Frankfurt am Main and with the Centre for European Policy in Berlin. The article is available for download on the <a href="https://law.stanford.edu/publications/competition-in-the-press-a-computational-analysis-of-u-s-german-newspaper-discourse-1870-1945/" rel="noopener noreferrer" target="_blank">Stanford Computational Antitrust project&rsquo;s page</a>.</p>]]></content>
	<updated>2026-05-23T11:37:34+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-05-23T11:37:34+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-05-23:/288521</id>
	<link href="https://law.stanford.edu/2026/05/22/analyzing-doping-enhanced-sport-and-enterprise-responsibility/" rel="alternate" type="text/html"/>
	<title type="html">Analyzing Doping, Enhanced Sport, and Enterprise Responsibility</title>
	<summary type="html"><![CDATA[<p>On May 24, 2026, an entity with ties to Peter Thiel, Donald Trump Jr., and Christian Angermayer will...</p>]]></summary>
	<content type="html"><![CDATA[<p>On May 24, 2026, an entity with ties to Peter Thiel, Donald Trump Jr., and Christian Angermayer will apparently offer athletes $250,000 per event won and potential $1 million bonuses to compete in the &ldquo;Enhanced Games.&rdquo;[1] In open defiance of the anti-doping rules found in the World Anti-Doping Code and the UNESCO International Convention Against Doping in Sport, this event allows competitors to use some performance-enhancing drugs (and, possibly, gene editing).</p>
<p>Aron D&rsquo;Souza, the event&rsquo;s founder and CEO of an AI adjudication company, defends the model as the &ldquo;safest sporting event in history&rdquo; claiming that organizers will pre-screen athletes for potential medical hazards and monitor athletes&rsquo; health status while they are competing.[2] However, the World Anti-Doping Agency (WADA) has rejected this competition as dangerous and irresponsible, emphasizing athlete health, the risk of powerful substances, and the danger of normalizing performance-enhancing drug use for entertainment and marketing.[3]</p>
<p>This essay gives background to the bodies governing sport, evaluates the competing claims of individual autonomy versus public health, and concludes with a proposal for an enterprise liability-shifting regulatory framework. I argue that athlete bans alone are incomplete, and that sports law should also ask when federations, promoters, teams, sponsors, or parent companies should bear responsibility for the enhancement risks they help create.</p>
<h3><strong>I. Anti-doping Governance is a Combination of Hard and Soft Law</strong></h3>
<p>WADA is the organization spearheading international efforts to standardize and harmonize anti-doping efforts. WADA has an unusual hybrid structure. Formally, WADA is a Swiss private-law, not-for-profit foundation, but it is composed and funded by both the Olympic Movement and public authorities representing governments. This hybrid design allows WADA to operate between private sport regulation and public legal authority, making international anti-doping governance a mixture of soft law, contractual sport rules, and state-backed legal obligations.[4]</p>
<p>The WADA Code itself functions primarily as soft law&mdash;a set of rules enforced through private contracts or informal means between athletes, national federations, and the International Olympic Committee.[5] When an athlete signs up to compete in a federation event, they agree to strict liability, meaning they are responsible for any substance found in their body regardless of intent. The WADA Code is reinforced by the UNESCO International Convention Against Doping in Sport, a 136-page document that governs anti-doping practices across the globe, which provides a hard law foundation by requiring signatory states to align their domestic legislation with WADA standards. For serious first violations, the Code can impose a four-year period of ineligibility, especially when the violation is intentional or involves a non-specified substance or prohibited method.[6]</p>
<p>The Enhanced Games challenges this hierarchy by attempting to operate outside the contractual jurisdiction of traditional federations. In doing so, it raises questions regarding enterprise responsibility: if a private company incentivizes high-risk chemical or biological enhancement, who bears the legal burden if an athlete suffers a catastrophic health failure? Unlike traditional sports, where the athlete often bears the brunt of &ldquo;strict liability,&rdquo; the Enhanced Games model suggests a shift toward corporate accountability for medical oversight.</p>
<h3><strong>II. Sports Already Draw Blurry Lines Between Risk, Technology, and Enhancement</strong></h3>
<p>Broadly speaking, doping refers to athletes&rsquo; use of any performance-enhancing methods that are considered to be unethical or that undermine a level playing field in sport.[7] To be against doping depends on the premise that regulators can identify a clear boundary between natural performance and impermissible artificial advantage. But across chemical enhancement, equipment regulation, testing regimes, and competition categories, that boundary is often unclear. Therefore, the legal question should not be limited to whether an individual athlete crossed it; it should instead ask who designed, enforced, or profited from the current boundary lines.</p>
<h4><strong>A. Regulating Chemical Risks in Already Physically Risky Sports is Paternalistic</strong></h4>
<p>Anti-doping policy can sound paternalistic in sports where athletes already accept serious bodily risk. Free solo climbing, professional football, and mixed martial arts all involve physical danger that spectators, sponsors, and governing bodies permit or even market.[8] A rule telling athletes that physical risk is acceptable but chemical risk is forbidden can look less like a pure safety regulation and more like a judgment about what kinds of risk sport wants to recognize. The line between those risks can be blurred too. For instance, the U.S. 9<sup>th</sup> Circuit in <em>Hunt v. Zuffa</em> affirmed that the performance of a doped MMA opponent was not so enhanced by performance-enhancing drugs as to exceed opponent&rsquo;s consent to battery in fight.[9] In other words, the court treated doping as insufficient, on those facts, to transform the physical contact of an MMA fight into a nonconsensual battery.</p>
<h4><strong>B. We Already Regulate Physical Advantages</strong></h4>
<p>The same line-drawing problem appears in equipment regulation. As new technologies enter competition, sports regulators must decide which innovations are permissible improvements and which ones distort the nature of the event. In 2009, Swimming&rsquo;s International Federation moved to ban non-textile polyurethane suits after controversy over whether the suits could aid speed or buoyancy.[10] Similarly, in running events, World Athletics amended rules in 2020 on what shoes competitors could wear, including considerations of availability, prototypes, sole thickness, and shoe construction.[11] Technological advancements though high-tech swimsuits and carbon-plated running shoes already indicate that the boundary between acceptable enhancement and impermissible advantage is unclear. Even outside the context of drugs or biological modification, sports law governance faces the problem of deciding how much human performance may be shaped by external intervention.</p>
<h4><strong>C. Testing Results are Uncertain and Discriminatory</strong></h4>
<p>Testing uncertainty adds another reason for caution before imposing the harshest sanctions. In Shelby Houlihan&rsquo;s case, the transnational Court of Arbitration for Sport (CAS) imposed a four-year ban after testing positive for nandrolone, an anabolic steroid, while Houlihan argued that a pork burrito could have caused the result.[12]</p>
<p>Kathryn Henne, in her book Testing for Athlete Citizenship, argues that anti-doping testing can be seen as needless surveillance and can be discriminatory or arbitrary, including for women and people from lower-income countries.[13] She notes that athletes caught and punished for doping are not always the ones using performance-enhancing drugs to cheat. In the case of female athletes, violations of fair play can stem from their inherent biological traits.</p>
<h4><strong>D. Creating a Separate Category <strong>May Improve Competition Fairness</strong></strong></h4>
<p>International bodybuilding competitions already separate a natural category from a performance-enhanced one. Kayser, Mauron, and Miah argued in 2007 that current anti-doping policy may create health problems of its own and that medically supervised doping could be ethically preferable to hidden, unsupervised use.[14] If enhancement exists anyway, disclosure and medical supervision may be safer than denial and underground use.</p>
<h3><strong>III. Shifting Responsibility from the Athlete to the Federation May Be a Way Forward</strong></h3>
<p>Modern sports enhancement is produced by systems, not just individual athletes. So rather than a binary choice between total prohibition and a separate, unregulated competition category, a more sustainable model may involve a regulatory framework that shifts liability to enterprises.</p>
<p>Just as enterprise liability for defective products can move responsibility from the individual user to the commercial actor that designs, markets, and profits from the risk, perhaps the same can be done with sports. Doing so could still preserve athlete sanctions for serious intentional doping, but adds enterprise duties of disclosure, independent testing, medical monitoring, insurance, and compensation when organizations fail to manage doping risk.</p>
<p>The stakes of maintaining the current athlete-centric model are high. History demonstrates that when regulators focus solely on punishing individual competitors, the systemic exploitation of human biology continues unabated. During the German Democratic Republic (GDR) regime, doctors and coaches administered the anabolic steroid Oral-Turinabol to athletes without explaining what the substances actually were.[15] More recently, WADA banned Russia in 2019 from international sports competitions for four years after the country was found to be running a years-long, state-sponsored doping scheme.[16] In both cases, institutions encouraged, concealed, or normalized enhancement practices. Punishing only the athlete therefore misidentifies the source of the harm; it leaves untouched the officials that create the conditions under which athletes are pressured or deceived into modifying their bodies for competitive gain.</p>
<p>Instead of asking only whether the athlete should be banned, regulators should ask what duties should fall on the league, promoter, federation, team, sponsor, or parent company that designs the competitive environment. The U.S. appeals court in <em>Hunt</em> pointed towards this path when it considered UFC&rsquo;s alleged representations, testing practices, and role as event organizer.[17] While the court ultimately rejected Mark Hunt&rsquo;s claim that UFC encouraged a doped athlete fight, it allowed legal theories tied to Hunt&rsquo;s claim that he suffered actionable harm because he would have withdrawn from the fight had the promoter disclosed the truth about his opponent&rsquo;s doping status.[18]</p>
<p>In WADA-regulated sport, transferring liability to the parent organization could mean stronger sanctions for support personnel and teams that facilitate doping and larger consequences for institutions that create incentives for hidden enhancement. In enhanced competitions like the Enhanced Games, it could mean mandatory health funds, physician oversight, and strict sponsor or promoter liability for misleading safety claims. A neutral policy could therefore keep WADA&rsquo;s four-year ban for serious intentional doping while requiring the parent enterprise to bear costs when its business model increases the risk of chemical coercion, hidden enhancement, or unreliable enforcement.</p>
<p>By shifting the legal focus from &ldquo;catching individual cheats&rdquo; to &ldquo;regulating enterprise designs,&rdquo; sports law can finally hold the true profit-makers accountable for the physiological risks they help create.</p>
<p><strong>References</strong></p>
<p>[1] John Hoberman, The Enhanced Games: A Techno-Fantasy That Will Fail, 14 Performance Enhancement &amp; Health 100380 (2026), https://doi.org/10.1016/j.peh.2025.100380; Clara Molot, <em>Inside the Enhanced Games, Where Athletes Compete on Steroids. And Growth Hormones. And Adderall.</em>, Vanity Fair (Apr. 30, 2026).</p>
<p>[2] J. Whitehead, <em>Enhanced games: Event for doped athletes backed by group who want to &lsquo;cheat death,&rdquo;</em> N.Y. Times (Mar. 22, 2024).</p>
<p>[3] World Anti-Doping Agency, WADA Condemns Enhanced Games as Dangerous and Irresponsible (May 22, 2025).</p>
<p>[4] World Anti-Doping Agency, Governance, WADA, https://www.wada-ama.org/en/who-we-are/governance.</p>
<p>[5] World Anti-Doping Agency, World Anti-Doping Code art. 1, 2 (2021).</p>
<p>[6] <em>Id.</em> at Art. 10.2.1 (2021).</p>
<p>[7] Kathryn Henne, <em>WADA, the Promises of Law and the Landscapes of Antidoping Regulation</em>. PoLAR: Political and Legal Anthropology Review, 33, 306-325 (2010). https://doi.org/10.1111/j.1555-2934.2010.01116.x.</p>
<p>[8] Bengt Kayser, Alexandre Mauron &amp; Andy Miah, Current Anti-Doping Policy: A Critical Appraisal, 8 BMC Med. Ethics 2, 5-6 (2007).</p>
<p>[9] <em>Hunt v. Zuffa LLC</em>, No. 23-3113, 2025 WL 1164219 at *1 (9th Cir. Apr. 22, 2025) (affirming the lower court&rsquo;s decision).</p>
<p>[10] Swimming: Hi-Tech Suits Banned, Sky Sports (July 24, 2009).</p>
<p>[11] <em>World Athletics Modifies Rules Governing Competition Shoes for Elite Athletes</em>, World Athletics (Jan. 31, 2020); <em>World Athletics Amends Rules Governing Shoe Technology and Olympic Qualification System</em>, World Athletics (July 28, 2020).</p>
<p>[12] <em>World Athletics v. Houlihan</em>, CAS 2021/O/7977, Award, paras. 5, 26-33, 153 (Ct. Arb. Sport Aug. 27, 2021).</p>
<p>[13] Kathryn Henne, <em>Testing for Athlete Citizenship: Regulating Doping and Sex in Sport</em> (2015).</p>
<p>[14] Bengt Kayser, Alexandre Mauron &amp; Andy Miah, Current Anti-Doping Policy: A Critical Appraisal, 8 BMC Med. Ethics 2, 5-6 (2007).</p>
<p>[15] Kyle James, <em>East Germany&rsquo;s Doping Program Casts Long Shadow Over Victims</em>, DW.Com (Jan. 10, 2010) https://www.dw.com/en/east-germanys-doping-program-casts-long-shadow-over-victims/a-5968383.</p>
<p>[16] Eric He, <em>What Does ROC Stand For? And Why Did Russia Get Banned from Olympics?</em>, NBC Olympics (Feb. 5, 2022).</p>
<p>[17] <em>See Hunt</em>, 2025 WL 1164219 at *1.</p>
<p>[18] <em>Id.</em></p>]]></content>
	<updated>2026-05-22T23:47:49+00:00</updated>
	<author><name>Katherine Wu</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-05-22T23:47:49+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>

	<category term="bioethics"/>

	<category term="doping"/>

	<category term="gene editing"/>

	<category term="genetics"/>

	<category term="liability"/>

	<category term="pharmacueticals"/>

	<category term="sports law"/>

	<category term="wada"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-05-18:/288142</id>
	<link href="https://law.stanford.edu/2026/05/18/the-growing-use-of-the-fda-breakthrough-devices-program-and-recalls/" rel="alternate" type="text/html"/>
	<title type="html">The Growing Use of the FDA Breakthrough Devices Program and Recalls</title>
	<summary type="html"><![CDATA[<p>At the close of 2025, the US Government Accountability Office (GAO) issued a report concluding that ...</p>]]></summary>
	<content type="html"><![CDATA[<p>At the close of 2025, the US Government Accountability Office (GAO) issued a report concluding that the Food and Drug Administration (FDA) should dedicate more resources to its oversight of recalls for medical devices.[1] If the use of a medical device begins to prompt safety or other concerns, either the FDA can mandate a recall or&mdash;more commonly&mdash;the device&rsquo;s manufacturer can voluntarily initiate a recall and work with the FDA to resolve those concerns.[2] Yet, the GAO concluded the FDA does not have enough staff to oversee these recall processes, and even suggested policymakers consider whether the agency needs more authority to conduct recalls for devices.</p>
<p>The GAO report, however, does not touch specifically on the FDA&rsquo;s newer Breakthrough Devices Program.[3] This Program has operated for about a decade and provides device manufacturers with a menu of potential benefits&mdash;including potentially modifying clinical trial expectations&mdash;if the FDA determines that a device they are still developing meets certain statutory criteria. To be designated a breakthrough, a device should &ldquo;provide for more effective treatment&rdquo; of serious conditions <em>and</em> either 1) use &ldquo;breakthrough technologies,&rdquo; 2) have no alternative on the market, 3) be better than alternatives on the market, or 4) generally be &ldquo;in the best interest of patients.&rdquo;[4]</p>
<p>In a recent article in the <em>Columbia Science and Technology Law Review</em>, I argue that the kind of expedited regulatory review that happens in the Breakthrough Devices Program should not be combined with immunity from tort liability.[5] Medical devices that are authorized through a Premarket Approval by the FDA are shielded from much state-level tort liability by federal law, which appears to be true even if those devices participate in the Breakthrough Devices Program and receive expedited regulatory review. This is a problem, since it could shift some of the risks of medical innovation onto patients who use new devices, instead of the companies that develop them. The argument was based in part on empirical findings illustrating how this Program has been operating over its first decade.</p>
<p>In light of the recent GAO report on device recalls, this blog post draws out and highlights three of the article&rsquo;s findings that have potential relevance to medical device recall law and policy. They are:</p>
<ol>
<li>The number of breakthrough designated devices that go on to receive FDA authorization is increasing over time;</li>
<li>A notable amount of these authorized breakthrough devices are &ldquo;cleared&rdquo; through the 510(k) pathway, which typically does not require clinical trials proving safety and effectiveness; and</li>
<li>Recalls for breakthrough devices have already begun for this relatively new Program, affecting about one in ten of those authorized so far.</li>
</ol>
<h3><strong>Authorizations of Breakthrough Devices Are Increasing</strong></h3>
<p>Generally, new medical devices (except for many low-risk ones) must get some kind of authorization from the FDA before they can be legally marketed in the United States. The three most common kinds of authorization are Premarket Approval, 510(k) clearance, and the De Novo pathway.[5] Premarket Approval is typically for higher-risk devices and requires clinical trials showing they are safe and effective. Moderate-risk devices instead usually use the 510(k) or De Novo pathways. The 510(k) process often does not require clinical trials if a manufacturer can show their device is &ldquo;substantially equivalent&rdquo; to a device already on the market. The De Novo process is for devices that are not equivalent to an existing product but are not risky enough to merit a full Premarket Approval, and may include some clinical trials.</p>
<p>Devices destined for any of these three kinds of authorization are eligible to apply to the Breakthrough Devices Program. The FDA reports how many medical devices it annually designates as &ldquo;breakthroughs&rdquo; on its website, which is roughly increasing over time.[3] However, the agency does not publicize which devices or manufacturers have received the designation or what regulatory benefits they received, if any, citing its own regulations and Freedom of Information Act exceptions for &ldquo;confidential&rdquo; business information.[6] In fact, the FDA did not even begin reporting which breakthrough devices had been authorized to enter the US market for patient use at all until 2022, when journalists began questioning the agency&rsquo;s lack of transparency.[7]</p>
<p>Cross-referencing that now-public list of authorized breakthrough devices against other publicly available FDA databases gave a more robust picture of the Breakthrough Devices Program. The findings from my study show that the number of breakthrough devices that the FDA has authorized&mdash;not just designated&mdash;is also increasing over time.[5]</p>
<h4><strong>FDA Device Authorizations After Breakthrough Designation</strong></h4>
<p><img fetchpriority="high" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-300x169.png" alt="" srcset="https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-300x169.png 300w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-1024x576.png 1024w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-768x432.png 768w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-1152x648.png 1152w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-142x80.png 142w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-220x124.png 220w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure.png 1280w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-300x169.png 300w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-1024x576.png 1024w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-768x432.png 768w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-1152x648.png 1152w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-142x80.png 142w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure-220x124.png 220w,https://law.stanford.edu/wp-content/uploads/2026/05/Blog-FDA-Figure.png 1280w" sizes="(max-width: 600px) 100vw, 600px" referrerpolicy="no-referrer" loading="lazy"></p>
<p>*Data are through June 30, 2025; reproduced with permission from the <em>Columbia Science and Technology Law Review</em></p>
<h3><strong>More Breakthrough Devices Going Through the 510(k)</strong></h3>
<p>These data on authorized breakthrough devices also show that a surprising number of devices going through the Breakthrough Devices Program end up being authorized through the 510(k) pathway. In the last full year of data that was available at the time, over half of all authorized breakthrough devices that year (2024) went through the 510(k) process.</p>
<p>This finding is surprising, since for that to happen a breakthrough 510(k) device would seemingly need to both be a &ldquo;breakthrough&rdquo; but, at the same time, be &ldquo;substantially equivalent&rdquo; to an existing product. One of the requirements for using the 510(k) pathway is that the device either has &ldquo;the same technological characteristics&rdquo; as an existing device, or has &ldquo;different technological characteristics&rdquo; but &ldquo;[d]oes not raise different questions of safety and effectiveness.&rdquo;[8]</p>
<p>Since the FDA rarely reports which statutory criteria justified providing breakthrough designation to a device intended for the 510(k) pathway,[5] it is difficult to determine exactly how a &ldquo;breakthrough&rdquo; device could either use existing technology or use new technology that has no new safety or effectiveness implications. Perhaps these devices received the designation by meeting statutory criteria other than the use of &ldquo;breakthrough technologies,&rdquo;[4] though it is difficult to know based on only publicly available records.</p>
<h3><strong>Recalls for Breakthrough Devices Have Already Begun</strong></h3>
<p>The data also show that, as of mid-last year, one breakthrough device had already undergone a Class I recall and 16 devices underwent Class II recalls&mdash;involving 17 out of the 160 total breakthrough devices that had been authorized by then. Class I recalls happen when there is &ldquo;a reasonable probability that [a device] will cause serious adverse health consequences or death,&rdquo; while a Class II recall generally indicates a risk of &ldquo;temporary or medically reversible adverse health consequences.&rdquo;[9] For context, the GAO found that device manufacturers voluntarily initiated between 736 and 865 recalls each year, from 2020 to 2024.[1]</p>
<p>While the one Class I recall was for a device that underwent Premarket Approval, the Class II recalls were for breakthrough devices authorized across all three pathways. These recall data do not necessarily speak to the overall safety of the affected devices, as recalls can happen for a variety of reasons and can be remedied.</p>
<p>Yet, the notable percentage of breakthrough devices being recalled (over one in ten) may deserve greater policy attention. As further context, previous research has found that medical devices that receive priority review from the FDA&mdash;a benefit also included in the Breakthrough Devices Program&mdash;are generally recalled earlier and more often than devices receiving standard review.[10]</p>
<h3><strong>Implementing the GAO Recommendations</strong></h3>
<p>When read in light of the GAO report and previous research, these data suggest that the FDA may need even greater staffing and resources to monitor breakthrough device recalls, possibly over and above the boost already recommended by the GAO. These innovative devices may undergo less strict regulatory review as a part of their participation in the Breakthrough Devices Program,[6] which may then require a higher level of regulatory surveillance and recall oversight after patients begin using those devices to ensure that public health can be adequately protected.</p>
<p>While the current political moment may not facilitate providing the FDA with adequate resources for regulatory supervision, policymakers should seriously consider how to implement the GAO&rsquo;s recommendations as early as possible, and may need to account for breakthrough devices when they do.</p>
<h3><strong>References</strong></h3>
<p>[1] U.S. Gov&rsquo;t Accountability Off., Medical Device Recalls: HHS and FDA Should Address Limitations in Oversight of Recall Process, GAO-26-107619 (Dec. 8, 2025), https://www.gao.gov/products/gao-26-107619.</p>
<p>[2] See 21 C.F.R. &sect;&sect; 7.40&ndash;7.59, 810.1&ndash;810.17 (2026).</p>
<p>[3] U.S. Food &amp; Drug Admin., <em>Breakthrough Devices Program</em>, https://www.fda.gov/medical-devices/how-study-and-market-your-device/breakthrough-devices-program (accessed May 13, 2026).</p>
<p>[4] 21 U.S.C. &sect; 360e&ndash;3(b) (2026).</p>
<p>[5] Walter G. Johnson, <em>Breakthrough or Breakaway Innovation?</em>, 27 Colum. Sci. &amp; Tech. L. Rev. 171 (2026), https://doi.org/10.52214/stlr.v27i1.14548.</p>
<p>[6] U.S. Food &amp; Drug Admin., Breakthrough Devices Program: Guidance for Industry and Food and Drug Administration Staff (2023), https://www.fda.gov/media/162413/download.</p>
<p>[7] Katie Palmer &amp; Mario Aguilar, <em>FDA&rsquo;s Breakthrough Device Program, Meant to Benefit Patients, Is Delivering the Biggest Gains for Companies</em>, Stat News (2022), https://www.statnews.com/2022/04/18/fda-breakthrough-device-designation-investigation/.</p>
<p>[8] 21 C.F.R. &sect; 807.100(b)(2) (2026).</p>
<p>[9] 21 C.F.R. &sect; 7.3(m) (2026).</p>
<p>[10] Caroline Ong, Vy K. Ly &amp; Rita F. Redberg, <em>Comparison of Priority vs Standard US Food and Drug Administration Premarket Approval Review for High-Risk Medical Devices</em>, 180 JAMA Internal Med. 801 (2020).</p>]]></content>
	<updated>2026-05-18T18:29:31+00:00</updated>
	<author><name>Law and Biosciences Blog</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-05-18T18:29:31+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>

	<category term="breakthrough devices program"/>

	<category term="fda"/>

	<category term="gao"/>

	<category term="medical device"/>

	<category term="medicine"/>

	<category term="recalls"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-05-16:/287826</id>
	<link href="https://www.gautrais.com/conferences/influences-nord-sud-du-droit-compare-a-la-decolonisation-du-droit/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=influences-nord-sud-du-droit-compare-a-la-decolonisation-du-droit" rel="alternate" type="text/html"/>
	<title type="html">Influences Nord-Sud: du droit comparé à la décolonisation du droit, Dakar (Sénégal) + Zoom(15 mai 2026)</title>
	<summary type="html"><![CDATA[<p>Trop souvent, les pays du Sud s&rsquo;inspirent des mani&egrave;res de dire le droit en se basant sur des l&eacute;gisla...</p>]]></summary>
	<content type="html"><![CDATA[<div dir="auto"><span>Trop souvent, les pays du Sud s&rsquo;inspirent des mani&egrave;res de dire le droit en se basant sur des l&eacute;gislations provenant du Nord. Si le droit compar&eacute; est assur&eacute;ment une source d&rsquo;inspiration, on constate trop souvent des implants juridiques qui sont parfois trop fortement pens&eacute;s par des juristes du Nord. Dans certaines circonstances m&ecirc;mes, ils sont &laquo;&nbsp;impos&eacute;s&nbsp;&raquo; par des organismes internationaux qui font primer l&rsquo;harmonisation du droit &agrave; la protection des particularismes culturels.</span></div>
<div dir="auto"></div>
<div dir="auto">Venez &eacute;couter diff&eacute;rents professeurs de diff&eacute;rents horizons sur ce sujet.</div>
<div dir="auto"></div>
<div dir="auto">&#128205; En personne au S&eacute;n&eacute;gal;</div>
<div dir="auto">&#128250; Diffusion en direct sur Zoom;</div>
<div dir="auto"><strong>&#128351; 9h30 &ndash; 17h00 (S&eacute;n&eacute;gal)&nbsp;&nbsp;; 5h30 &ndash; 13h00 (Qu&eacute;bec); 11h30 &ndash; 19h00 (France)</strong></div>
<div dir="auto"></div>
<div dir="auto">&#128073; Inscription gratuite, pour recevoir le lien zoom, merci de contacter&nbsp;: luka.sanchez@umontreal.ca</div>
<div dir="auto"></div>]]></content>
	<updated>2026-05-15T22:10:22+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-05-15T22:10:22+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-05-11:/287507</id>
	<link href="https://law.stanford.edu/2026/05/11/bangladesh-computational-antitrust/" rel="alternate" type="text/html"/>
	<title type="html">The Stanford Computational Antitrust Project Welcomes the Bangladesh Competition Commission</title>
	<summary type="html"><![CDATA[<p>Stanford, May 2026 &mdash; The Stanford Computational Antitrust Project, an initiative led by Dr. Thibault...</p>]]></summary>
	<content type="html"><![CDATA[<p>Stanford, May 2026 &mdash; The Stanford Computational Antitrust Project, an initiative led by Dr. Thibault Schrepel, is pleased to announce that the Bangladesh Competition Commission (BCC) has joined its global network.</p>
<p>The Stanford Computational Antitrust Project brings together over 80 competition agencies from around the world to explore how computational methods can strengthen the analysis and enforcement of competition law. Membership is independent and carries no financial obligation.</p>
<p>The Bangladesh Competition Commission was established under the Competition Act, 2012 and is the statutory body entrusted with the application of competition law in Bangladesh. The Commission is responsible for preventing, controlling, and eradicating collusion, monopoly, abuse of dominant position, and other practices adverse to competition. It plays a central role in shaping the competitive conditions of one of South Asia&rsquo;s fastest-growing economies.</p>
<p>The partnership will focus on methodological exchanges and applied research. The BCC will contribute to the project&rsquo;s annual reports, participate in its events, engage in exchanges with peer agencies across the network, and collaborate on building legal frameworks and computational tools adapted to the realities of fast-evolving markets.</p>
<p>Dr. Thibault Schrepel, founder of the Stanford Computational Antitrust Project, stated:</p>
<blockquote><p>&ldquo;The Bangladesh Competition Commission is exactly the kind of partner we hoped to welcome. Bangladesh is one of the most dynamic economies in South Asia, and the questions its competition authority faces are at the heart of what computational antitrust can address. We are delighted to begin this collaboration and look forward to the work ahead.&rdquo;</p></blockquote>
<p>Contact:<br>
Stanford Computational Antitrust Project<br>
law.stanford.edu/computationalantitrust<br>
schrepel@stanford.edu</p>
<p>Bangladesh Competition Commission<br>
www.ccb.gov.bd</p>]]></content>
	<updated>2026-05-11T15:38:25+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-05-11T15:38:25+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-05-07:/287227</id>
	<link href="https://law.stanford.edu/2026/04/23/elabogado-codex-group-meeting-april-23-2026/" rel="alternate" type="text/html"/>
	<title type="html">ElAbogado – CodeX Group Meeting – April 23, 2026</title>
	<summary type="html"><![CDATA[<p>ElAbogado: AI-Powered Legal Lead Matching at Scale
ElAbogado is a Spanish-based legal lead generatio...</p>]]></summary>
	<content type="html"><![CDATA[<p><strong>ElAbogado: AI-Powered Legal Lead Matching at Scale</strong></p>
<p>ElAbogado is a Spanish-based legal lead generation platform that connects people with the right lawyers across Spain, the U.S., Puerto Rico, Mexico, Chile, and Colombia. Co-founder Mart&iacute; Manent and data scientist Veronica Sorin presented at Stanford Law School&rsquo;s CodeX Group Meeting on how they&rsquo;ve built what they describe as a state-of-the-art agentic legal lead management system.</p>
<ul>
<li><strong>The problem they solve:</strong> Most people default to the nearest or most familiar lawyer rather than one who specializes in their specific legal issue &mdash; ElAbogado matches users to the right specialist, having helped 2.5+ million people find lawyers to date.</li>
<li><strong>Scale:</strong> The platform handles ~1,500 leads per day (8,000/week), fielding inquiries via chat, phone, and WhatsApp.</li>
<li><strong>15 years of data as the foundation:</strong> Real legal case data trained their AI models on tone, question flow, case qualification, and jurisdiction matching.</li>
<li><strong>Agentic pipeline:</strong> AI agents now handle inbound/outbound calls, chat, and WhatsApp conversations &mdash; qualifying leads, extracting case data, routing to the right lawyer, and following up if a lawyer doesn&rsquo;t respond.</li>
<li><strong>Results:</strong> ~70% of cases are fully automated; headcount for the human lawyer intake team has been cut by more than half in under a year.</li>
<li><strong>Guardrails:</strong> They deliberately stop short of 100% automation, keeping humans in the loop for complex cases (~30%) and running post-call quality checks.</li>
<li><strong>What&rsquo;s next:</strong> Pushing automation toward 85&ndash;90%, expanding to new countries (now a one-month project vs. one year previously), and potentially entering English-speaking markets.</li>
</ul>
<p><img loading="lazy" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026.png" alt="ElAbogado - CodeX Group Meeting - April 23, 2026" srcset="https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026.png 1553w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-300x150.png 300w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-1024x513.png 1024w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-768x385.png 768w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-1536x769.png 1536w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-1152x577.png 1152w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-160x80.png 160w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-640x320.png 640w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-220x110.png 220w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026.png 1553w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-300x150.png 300w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-1024x513.png 1024w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-768x385.png 768w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-1536x769.png 1536w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-1152x577.png 1152w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-160x80.png 160w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-640x320.png 640w,https://law.stanford.edu/wp-content/uploads/2026/05/elabogado-codex-group-meeting-april-23-2026-220x110.png 220w" sizes="(max-width: 1553px) 100vw, 1553px" referrerpolicy="no-referrer"></p>
<p><a href="https://youtu.be/EdbfT0sskgM?si=VER8rUbcXX8CVD4m" target="_blank" rel="noopener noreferrer">Watch CodeX Group Meeting with ElAbogado</a></p>
<p><strong>Full Transcript</strong></p>
<p><b>Roland Vogl</b></p>
<p><span>Welcome everyone to our Codex group meeting. This is our first group meeting after our FutureLaw Conference. It&rsquo;s been an intense week at Stanford. If you were here, I hope you enjoyed it as much as we did. We thought we had a very productive week with a lot of new ideas that were being shared, and a lot of great people in town. If you weren&rsquo;t able to participate this year, I hope you&rsquo;ll make it next year. We will be pushing out videos of our main conference, the main Future Law Conference, in the next couple of days or so. You will be able to watch the videos in our YouTube channel. It&rsquo;s really great content there, so be sure to check it out.</span></p>
<p><b>Roland Vogl:</b><span> One of the great people who came here and was here for pretty much the entire week is Mart&iacute; Manent, who&rsquo;s been a friend for many years, a legal innovation powerhouse in Spain, and whose platform, whose ElAbogado platform, reaches beyond Spain, actually, to many other countries. This is actually a legal lead generation platform that he&rsquo;s built among other legal tech projects. Mart&iacute; has kindly accepted our invitation to present here today, along with Veronica, who&rsquo;s a data scientist at El Abogada. We&rsquo;re thrilled to have you here today, and excited to learn what you&rsquo;ve been up to. With that, I will turn it over to Mart&iacute; and Veronica.</span></p>
<p><b>Marti Manent</b><span> Roland thank you very much for the invitation, and it was a great pleasure last week to be with all of you in Stanford. It was an amazing week, and probably all the videos will be very interesting for all of us.</span></p>
<p><span>Thank you for the invitation to explain ElAbogado, and what we have been doing the last two years, because probably after sharing this with a lot of people last week, I think that what we are doing is probably the state-of-the-art in agentic legal lead management.</span></p>
<p><span>For the first introduction, ElAbogado is a platform that was built with, we think, a nice proposal, because we think that a lot of people cannot go directly to a lawyer and what he or she does is go to the lawyer that is probably in the same street or close to a friend. Let&rsquo;s imagine that if you have some health problem and you go just to the person that you have close to you. That probably is not what you are doing. If you have a health problem, you go to the doctor that has the speciality correctly matched to what you have.</span></p>
<p><span>But a lot of people all around the world cannot go to a lawyer that has the practice for the problem that he or she has. Some years ago, we understood that if we could just make a match with a lawyer who has the practice that that person is looking for, that would be a nice step to more democratize access to justice. That was our proposal. To do that, we think that we can do it in a big way. We try to do that with technology. After some years, we have helped more than 2.5 million people to find the right lawyer, and that is for us, is a pleasure to know that a lot of people have found the right lawyer to help with their problem.</span></p>
<p><span>To give an idea of how many leads we are managing per day, we are probably at more than 1,500 per day. We are managing these leads through&hellip; in Spain, also in the States for the Spanish-speaking community. We are the lead platform in Puerto Rico, and also we are in Mexico, in Chile, and Colombia.</span></p>
<p><span>To give a little bit of context on our platform &mdash; what we do is, when we find a person that is looking for a lawyer, we want to talk with that person, because we need to understand what kind of problem he or she has, what kind of lawyer he or she needs, and if there is a real problem, or if it&rsquo;s not a legal problem.</span></p>
<p><span>In the last 5 or 6 years, we have been doing that with more than 40 lawyers in our team. But this is not scalable, and at the end of 2024, when the LLMs started being robust, we decided to try to build a new kind of solution.</span></p>
<p><span>What we understood is that if we could build a solution that can help people 24 hours a day, 7 days a week, through an agentic system, that would be amazing, because we could go to more countries and help more people.</span></p>
<p><span>That is what we have built with a conventional legal artificial intelligence model that is named CLAIM. One thing that we are very proud of is that OpenAI and 11 Labs &mdash; which are probably two of the leading labs doing LLMs, and also voice LLM, which is a level lab from Europe &mdash; have recognized us with some kind of award that we have received, and that, for us, was amazing.</span></p>
<p><span>To try to explain more entirely what we are doing here, it&rsquo;s a pleasure that Veronica is here with me. She&rsquo;s the scientist that can explain what we have been doing with this platform.</span></p>
<p><b>Veronica:</b><span> I think Mart&iacute; explained what it is that we do, and I will try to explain a little bit on how we do it. I think Mart&iacute; already mentioned some of the numbers, so the only thing I want you to get in mind is that we had a really big challenge to try to manage and to respond to all those users that we have, who have a real legal problem and need a fast answer or help. We had to find a way to do it as fast and efficiently as we can.</span></p>
<p><span>We had to find a way to treat our users in the best way, and so the problem is: which is the technology, and how we can use the technology that we have at the moment to help the users in the best way. To keep in mind, we have, like, one lead per minute, more or less, and 8,000 or so leads by week, 30K in a month. We had to find a way to find a solution for this technical challenge. How can we respond to our users in the best way, fast, and give them the best specialist for their legal problem?</span></p>
<p><span>What we realized is that it&rsquo;s not just one technology that can do all. We had to merge many pieces to make all this work and give us a solution.</span></p>
<p><span>The first thing we have is actually the training data. We have, like, 15 years of real legal cases. We have our lawyers that manage this list, that talk with the people. We have the lead with all the information, the data that is useful to train any artificial intelligence. That&rsquo;s kind of the base.</span></p>
<p><span>Then we have to build, on top of that, with the best tools that we can find, depending on the problem. It could be commercial tools, or any open source tools, and so on. Recently, and we&rsquo;ll talk a little bit more in a moment, it&rsquo;s all about LLMs. What is our best LLM? The thing is that we need to test, tune, and find what is the best solution for each specific task that we need to resolve. There is no just one solution for all.</span></p>
<p><span>We realized &mdash; and this was some time ago, because actually we have been using artificial intelligence for years now &mdash; that sometimes we also need to build an in-house solution. We cannot just pick up some tool that someone else has built and plug it in. We actually had to tune that for our product. We have all that data as the training ground, and how we translate that and build a tool that helps us to solve each of the technical challenges that we have.</span></p>
<p><span>Here we mentioned Claim &mdash; I think Mart&iacute; mentioned it &mdash; and we have also Leaks and SLAB that also give us the solution to other problems. The last part of all this is how we orchestrate all that. How we connect those tools &mdash; that could be just commercial, open source &mdash; with our tools, and how we use our data from all these 15 years to tune all that and put it all together.</span></p>
<p><span>As I said, we started with artificial intelligence some time ago; it&rsquo;s not just with the big LLM movement.</span></p>
<p><span>We realized, as Mart&iacute; said, that we have users that call us. One per minute or so. That means that you have a bigger, long call queue, and people that need an answer now &mdash; people that call, or people that just leave a message. We have all that, and we have our lawyers, who actually have to call them and extract or ask the user all the data that we need, so we can define what the problem is and which is the best specialist for that problem.</span></p>
<p><span>At that point, we understood that we had to make that process efficient. We needed a way to decide which is the lead you call first. How do you make all the efficiencies, so that you can give a solution to all of the users that are contacting you? At that moment, we used machine learning, so we trained, with our leads, a model that we also had in-house, to make this process very efficient.</span></p>
<p><span>Then, by 2022 or 2023, we had the big wow with the LLMs, so that became public for everyone. At that point, we said, okay, how do we start adopting that technology?</span></p>
<p><span>One way, for example, is to try to automatize and make things more efficient. For example, when we have to contact the lawyers, we send the information of the case of the user. The user needs a divorce lawyer that is in Barcelona, with such and such issues. All that, for example, the people just write in an email to send. Why, if the LLM can actually help on that &mdash; one of the simple things is we just ask it to make a text summary of the case. It&rsquo;s automatic. The people do not have to write any email. Things go fast, more efficient. So you start doing this type of things.</span></p>
<p><span>Then when the LLMs became even more intelligent, I think that&rsquo;s when we made the jump &mdash; a really big step forward &mdash; because now we can actually help people 24/7. People sometimes have problems, and the problems appear at any time of the day, and we are there for them to help.</span></p>
<p><b>Marti Manent</b><span> Let me explain a little bit. In 2019, what we did with machine learning was orchestrate which lead we need to call right now. Imagine that you have 100 or 200 leads that you need to call. The best decision was made by machine learning &mdash; that was TensorFlow from Google.</span></p>
<p><span>The next step in 2023 was: some of the information that we are going to send to the lawyer &mdash; who is our customer; the customer is the lawyer that pays per lead to us &mdash; is gonna be built by an LLM. The lawyer that calls the potential customer asks: where do you need a lawyer, in Barcelona, in Madrid, in Miami, whatever; what kind of practice is this? At the end, it was an LLM that wrote the message that the lawyer is going to receive.</span></p>
<p><span>But here, we still had lawyers inside our company making these calls and writing part of the documents that we were sending to our customers.</span></p>
<p><span>The big jump, as Vero mentioned, is in 2025. That part of all the jobs that our lawyers had been doing, we have transferred to an agent. To an agent that is making a call, an agent that is answering on WhatsApp, an agent that is answering a chat. I think that it&rsquo;s making the decision to say which is the best practice that that person is looking for. I think that it&rsquo;s making the decision of, okay, there is a case here that can go on. Also, an agent that makes a decision that, economically, this lead is viable.</span></p>
<p><span>Right now, we have probably half of the lawyers that we used to have in-house. In less than a year, we have reduced our task force that was doing the calls by a half. For me, that is very relevant, because that job has been done by lawyers, by people that have been trained, going to a law school, and have some kind of knowledge and make a decision. These decisions now are made by an agent. Better.</span></p>
<p><b>Veronica:</b><span> Yeah, exactly. Just to give a little bit on the hints of what the pipeline looks like step by step: we have the user, the person, the human, that has a problem and contacts us looking for a lawyer. That can be either, as Mart&iacute; said, a chat &mdash; so just typing &mdash; or calling us, or even WhatsApp.</span></p>
<p><span>Now we have an agent that actually answers the phone, in a way, or talks via chat, and that&rsquo;s all AI. That agent can converse and has a natural conversation with the user, because what we need in that conversation is to understand what the problem of the user is, where the problem is, and ask the questions that we know will give us the lead, or that we can use later on to validate and say, okay, this is a viable legal case. As Martin said, also, it&rsquo;s an economically viable one as well.</span></p>
<p><span>All that information is what we need to extract, and the agent knows, because we have trained it with the data from these 15 years. We tell this agent what it is that it needs to ask the user, so we have all that information to build this lead.</span></p>
<p><span>Once this conversation happens, then it goes to another agent, as well, that extracts all that data. We have a data model, so we actually have to fill that and get all the data from those leads to our database. Then that also goes to another agent where we do all this validation. Is the case valid? The agent knows how to decide if the case is a valid case or not.</span></p>
<p><span>Just to go on that part &mdash; the agent, once it qualifies the lead, can say: okay, I have everything, the lead is ready. We can just send it to the best lawyer, to the lawyer that this person needs, based on the legal area, on where they&rsquo;re located, the jurisdiction, etc. It just automatically sends.</span></p>
<p><span>That&rsquo;s more or less 50% of the cases. It&rsquo;s a pipeline built on AI agents, pure agentic tech. Everything goes by itself.</span></p>
<p><span>At some point, also, it could be that it&rsquo;s not a real lead. We are an online platform, so we receive calls that are an error, or there&rsquo;s not a real legal issue there. It&rsquo;s also as valuable to know not to send something to a lawyer. The agent also knows how to decide that the lead is not a real legal case. It also closes leads when that needs to be done.</span></p>
<p><span>There is also a third thing that could happen, and the system handles that as well: escalate to a human, which goes to our lawyers. When the lead needs to be handled by them, because maybe the case is complicated enough, or needs more information than we have, we can also transfer to a human when it&rsquo;s needed.</span></p>
<p><span>We also kind of close the loop, because once we send the lead to a lawyer, we want to know if the user still needs help. In the case that the lawyers do not call for some reason, we make a follow-up call. That is also an AI doing that &mdash; it&rsquo;s also another agent &mdash; to follow up and know if this person still needs help. If they do, it goes again back into the pipeline, and we help, again, to find a lawyer that helps with the problem.</span></p>
<p><span>As Mart&iacute; said, we communicate with the users through all three channels. The chat was actually the first channel that we started with the AI, because it&rsquo;s probably the easier one, in the sense that you have time to talk with the user, so the pace is very different, like with a voice call. When the user has to call us, it has to be in real time. We have the latency to take into account, and it&rsquo;s very challenging. The LLMs are now capable of doing that, because before, at the very beginning, it was very difficult to find a tool that gives you the latency and the intelligence to do that. Now, it&rsquo;s possible.</span></p>
<p><span>Also &mdash; and I don&rsquo;t know if we mentioned &mdash; it&rsquo;s not only the inbound calls, but we also do outbound calls. The channels talk to each other, so if in a chat you don&rsquo;t get all the information, you trigger a call, and the system also calls the user to get all the information for the case if needed.</span></p>
<p><span>We also now include WhatsApp, which is different because the user really sets the pace there. The user can get the fast answer from us when the user is there, but if the user has to go away and come back, the chat keeps listening, and it waits for the user to talk to us again.</span></p>
<p><span>To put everything together &mdash; I think we can say that our secret, in a way, is to have the 15 years of real legal cases. That&rsquo;s what we train all the agentic system that we have on. We can help the system know exactly what we need to ask the user, how to talk to the user, which is the tone, how to pace the conversation. At the end, we have what we need &mdash; the information we need for that legal case &mdash; so we can help them.</span></p>
<p><b>Marti Manent</b><span> Just one second. To not run out of time, I think that we want to show a real call that I think will be more interesting. All this explanation is to do that.</span></p>
<p><b>Roland Vogl:</b><span> Yeah, we can&rsquo;t hear the audio, that&rsquo;s too bad.</span></p>
<p><b>Veronica:</b><span> No?</span></p>
<p><b>Roland Vogl:</b><span> Nope. But&hellip; We have a mute agent.</span></p>
<p><b>Marti Manent</b><span> Yeah, oh, we can share. I think that it&rsquo;s in the presentation. You can see here, it&rsquo;s our page. We share this information online.</span></p>
<p><span>What is very relevant here is that we have a lot of challenges. The first challenge was to build the orchestration for agents. The second challenge was to decide what kind of practice. The third challenge: decide if the problem was a real legal problem, and whether it&rsquo;s economically valuable or not. Also, for example, we had challenges like the latency of the call, because if we don&rsquo;t have the right latency and the answer goes too fast, then the user doesn&rsquo;t perceive a correct back-and-forth and says, okay, that&rsquo;s a machine, I don&rsquo;t want to talk with a machine.</span></p>
<p><span>Anyone who wants to see online can go to eLabogado.com slash lawyer, and you can check real calls. You can see chats and all of this. I think that if the people want to make some questions, now would be the time.</span></p>
<p><b>Roland Vogl:</b><span> Yeah, so I think one question I have is: at what point did you feel comfortable that the agent that you tasked with this triaging task &mdash; the one you had human lawyers do before, right &mdash; like, is this a legal case, what kind of case is it, and who&rsquo;s the right lawyer in what jurisdiction to connect this case with? That&rsquo;s the key functionality, and probably the first functionality you tried to use AI for. How much testing did you do, how much validation did you do, before you felt like, okay, we&rsquo;re gonna use this now? Maybe you actually don&rsquo;t have a job for your human lawyers anymore, or you no longer have that job for them.</span></p>
<p><b>Marti Manent</b><span> Yeah, I think that has two answers. One is that we have a lot of cases from these last years, and we can train the machine, and also we can check if the answer that the machine is giving to us matches with the answer that the real lawyer gave previously. That is very relevant. We train over a platform with real cases, and then we pass the same cases through our platform and see the results.</span></p>
<p><span>Before we felt comfortable &mdash; as you asked &mdash; we didn&rsquo;t put it online. The first thing that we put online was the chat, and that&rsquo;s also very relevant, because it&rsquo;s easier to manage a case through a chat &mdash; by the technology, not by the information, but by the technology. After we felt comfortable with the chat, we jumped to the voice. This was the step: first, train with all data, train the machine, then pass the test. Once the machine, the platform, answers the same answers that all the lawyers did before with those cases, we put that platform ready online.</span></p>
<p><span>The second part of the question: yes, these agents are doing the job that real human lawyers were doing. As we mentioned last week when I was in Stanford, I think that it becomes a tsunami to the profession. For us, like one year ago, it was very strange, because for us it was a real tsunami that was coming to the profession, and the people are not running. We have less than half of the people that had been doing this job.</span></p>
<p><b>Roland Vogl:</b><span> I see, okay. So, now, at this point, can you say what percentage of your team &mdash; is this fully automated, this task now with agents already, or do you still have some humans involved in it, even if just for quality assurance?</span></p>
<p><b>Marti Manent</b><span> Yeah, almost 70% of the cases are fully automated. You asked which lawyer we give the lead to. One of the tricky questions was to find the place where the user is, because in the States, for example, there are a lot of cities that have the same name. How you can say that it&rsquo;s Miami from Florida, or it&rsquo;s Miami from California, or it&rsquo;s Miami from Texas? One trick that we found is to ask for the postal code. In which postal code you are &mdash; that is the way that you make the match with the lawyer in that jurisdiction.</span></p>
<p><span>For the 30% of the cases that cannot be managed by an agent, we send that case to a human, who manages the case. We also make post-checks of the calls &mdash; what does it mean? We check if, after a decision has been made by an agent, it is working correctly, and we are just tuning that result.</span></p>
<p><b>Roland Vogl:</b><span> Okay. There&rsquo;s a question from somebody in the chat, which is: deciding whether a case has merit or not &mdash; is that not already legal practice, and therefore might be called unauthorized practice of law?</span></p>
<p><b>Marti Manent</b><span> What I understand is, to try to understand if the case can go on or not &mdash; is that the question?</span></p>
<p><b>Roland Vogl:</b><span> Yeah, if a case has merit or not. If you say, like, okay, this is not even a legal case, versus, it is a legal case that you want to match with a lawyer. If you do this automatically, isn&rsquo;t that already legal practice? It could be, therefore, a violation of unauthorized practice of law.</span></p>
<p><b>Marti Manent</b><span> What we are doing is &mdash; our platform is a marketing platform. Our customers are the lawyers that want a new customer for them. What we are doing is helping lawyers, to give the lawyers the lead that they are asking for. For example, if you ask for a lead of a civil case, we cannot give you a criminal lead, because you are not doing that practice.</span></p>
<p><span>What we are doing is helping people &mdash; as I explained at the beginning &mdash; who don&rsquo;t know what kind of practice they need and don&rsquo;t know if there is a real case there. What we are just asking them is some questions to understand: okay, you&rsquo;re asking for a civil case &mdash; yes, that&rsquo;s a civil case. You are asking for a lawyer that makes that practice where? Miami, in San Francisco, or wherever. We say, okay, that is a lawyer that you previously chose.</span></p>
<p><span>For example, in the States, we don&rsquo;t choose the lawyer. The lawyer is chosen by the user. In other jurisdictions, the platform can choose the lawyer. But for example, in the States, the user chooses the lawyer. If that lawyer doesn&rsquo;t do the practice that the user is asking for, we need to say: okay, that lawyer does not practice physical cases or criminal cases.</span></p>
<p><b>Roland Vogl:</b><span> Okay. Sugaram&rsquo;s asking: what LLMs are you using to build your agents?</span></p>
<p><b>Marti Manent</b><span> Yeah, nice question. We use all of the big names that you know. Here, I&rsquo;m going to give you some tricks. We are not going to explain all the platform and how it works, but we recommend making parts of the problem. When you take all the problem in one cake, that is not the solution. You need to make some parts of that problem, and you can solve different parts of the problem with different LLMs. Let me explain a little bit. There are some LLMs that are quicker to answer. For example, if you are making a call, you cannot use, for example, Opus from Anthropic. Probably you need to use a smaller LLM that can go more quickly, and then the latency is lower. That is very, very relevant.</span></p>
<p><b>Roland Vogl:</b><span> Got it, okay. Awesome, so what&rsquo;s next for you? I mean, now it seems like you have, kind of, this business figured out. That&rsquo;s an interesting point you made, too, which is &mdash; in a sense, what I hear you say is, look, with a new tech, you can do this all quite quickly, right? But it still required 15 years of experience to know what the issues are, what&rsquo;s the tone, how to place this technology into this business opportunity, right? That&rsquo;s really where the rubber hits the road for many, right? Theoretically speaking, we all have the tools now to build a flywheel, a machine like this, right? But exactly how to fit it into the world is really where you need the context and the experience and all that, right?</span></p>
<p><span>I think that&rsquo;s one of the learnings from this. One of the questions that comes for me is: where do you&hellip; what&rsquo;s the next thing you want to apply this technology towards? Can you share anything, or it&rsquo;s all still in stealth, and we&rsquo;ll learn about it at your next presentation at Codex.</span></p>
<p><b>Marti Manent</b><span> No, don&rsquo;t worry. I think that we need to move the line up close to 85% of the cases. One of the learnings that we have found is that if you try to put it 100% automatic, you will probably have a big problem, because it&rsquo;s very, very hard. The actual LLMs make mistakes. They are not perfect. If you try to do a perfect solution, you are gonna make some mistakes, because it&rsquo;s very, very hard to achieve that &mdash; almost impossible.</span></p>
<p><span>The first solution here is that we want to push the line up to 85% or 90%, but never to 100, because some cases must be managed by a human. What we are also doing is jumping to new jurisdictions. It&rsquo;s more easy now, because we have the tools to jump to another jurisdiction. To go to another country, for example, for us, it&rsquo;s like a one-year project, and now it&rsquo;s like a one-month project. It&rsquo;s very, very easy now for us to go to different countries. Another thing is, we are a Spanish-speaking platform, and one of the things that we have on the table is going to English-speaking users, also.</span></p>
<p><b>Roland Vogl:</b><span> Got it, okay. Everyone can look forward to ElAbogado coming to a country near you. There&rsquo;s global expansion on the horizon. Maybe last question, because we&rsquo;re over time already, unfortunately &mdash; Reem is asking how you deal with privacy issues.</span></p>
<p><b>Marti Manent</b><span> Yeah, that&rsquo;s a very nice, interesting question. We are from Europe, and in Europe, the privacy issues are very, very interesting. We have a distributed platform, and for each country, we manage the data from that country. We use Amazon Web Service, and also we use providers that can provide service all around the world. That is one of the solutions, but it&rsquo;s very easy, though it has some restrictions. You need to use the platform that can go for an instance for each country.</span></p>
<p><b>Roland Vogl:</b><span> Got it, okay. Cool. Well, let&rsquo;s&hellip; oh, hold on, so Salih has their hand up. Sadi, you wanna unmute yourself and speak up?</span></p>
<p><b>Salih Tarhan:</b><span> Yeah, Salih, yeah, correct. I need to give some context, that&rsquo;s why, actually, I raised my hand. Thank you guys for the presentation, it was great. So, while I reviewed your website, actually, I saw that you are probably targeting the U.S. attorneys as well.</span></p>
<p><span>My question is &mdash; we built a platform helping attorneys to find attorneys in other jurisdictions, in other U.S. states. What we saw is that there are a lot of problems on ethics and professional responsibility. You cannot market, you cannot feasibly vet the attorneys in some states. There are the ABA model rules, a lot of highly regulated areas. I think you plan to extend your reach to the U.S. Do you have a plan to navigate this complex area of the law? Do you see any problem in the future for that?</span></p>
<p><b>Marti Manent</b><span> Yeah, there are some countries that we cannot go to, because the lawyers cannot make any kind of advertisement, and it&rsquo;s like the old school, closed market. I think that that is not good for justice. I think that it&rsquo;s good for justice that the users, the consumers, can see different kinds of lawyers, and the lawyers can advertise and explain their practice. Because if the lawyers cannot explain their practice, that is a closed market, and I think that it&rsquo;s not good for the competition. So, there are some countries that we cannot go to.</span></p>
<p><b>Roland Vogl:</b><span> Yeah, so I think, yeah, there&rsquo;s some&hellip; there are several platforms that have been trying to resolve that in the U.S. I could probably try to connect you with some people who&rsquo;ve been working on that, if you&rsquo;re interested in that. I think one of the questions is: do you take a share in the legal fees that are being generated by this lead? That&rsquo;s a different proposition and probably harder &mdash; it probably won&rsquo;t pass the fee-splitting rules in the U.S. Whereas if you have a law firm just paying a general subscription fee or something to a service, that&rsquo;s more likely just fine.</span></p>
<p><span>Well, anyways, I think this was a great conversation. Interesting also to see how a legal tech provider that you are &mdash; from the pre-GPT days and pre-LLM days &mdash; well, you started already in 2019, as you shared, with machine learning to help with the matchmaking, and then really also leveraged the LLM capabilities in your business. Also, how that affects your headcount and how you think about that. I think that&rsquo;s been really instructive, and I think it&rsquo;s instructive for a lot of legal tech players who&rsquo;ve been around for some time, and maybe some new entrants, too.</span></p>
<p><span>That was a really rich conversation. I really appreciate you, Mart&iacute; and Veronica, for staying up on this special day. I know Barcelona is like a holiday today, and it&rsquo;s already late at night, so really thank you so much for being with us here today. On behalf of everyone, a quick round of applause. Thank you for joining us, thank you for everyone in the group for tuning in. Look out for our Codex Future Law videos, which will be coming out soon, and I will be sending an update on our next meeting in the near future. Alright, well, good to see you all. Thank you very much.</span></p>
<p>&nbsp;</p>]]></content>
	<updated>2026-04-23T21:28:42+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-04-23T21:28:42+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="codex"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-05-07:/287149</id>
	<link href="https://www.gautrais.com/conferences/rencontres-jeunes-chercheurs-droit-numerique-droit-numerique-et-autonomie/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=rencontres-jeunes-chercheurs-droit-numerique-droit-numerique-et-autonomie" rel="alternate" type="text/html"/>
	<title type="html">Rencontres Jeunes chercheurs Droit &amp;#038; Numérique &amp;#8211; Droit, Numérique et Autonomie, HEC Montréal, Édifice Hélène-Desmarais (501, rue De la Gauchetière O, Montréal, QC H2Z 1Z5) (6 mai 2026)</title>
	<summary type="html"><![CDATA[<p>La&nbsp;Chaire L.R. Wilson&nbsp;a le plaisir de vous convier &agrave; la&nbsp;8e &eacute;dition des Rencontres Jeunes Chercheurs ...</p>]]></summary>
	<content type="html"><![CDATA[<p>La&nbsp;<strong>Chaire L.R. Wilson</strong>&nbsp;a le plaisir de vous convier &agrave; la&nbsp;<strong>8e &eacute;dition des Rencontres Jeunes Chercheurs Droit &amp; Num&eacute;rique</strong>, qui se tiendra le <strong>mercredi 6 mai 2026</strong> en format hybride &agrave; HEC Montr&eacute;al. Cet &eacute;v&eacute;nement s&rsquo;adresse aux jeunes chercheuses et chercheurs souhaitant &eacute;changer autour des enjeux contemporains du droit du num&eacute;rique, dans un cadre favorisant la discussion et les collaborations.</p>
<p>Depuis 2018, cet &eacute;v&eacute;nement offrent un espace privil&eacute;gi&eacute; aux jeunes chercheuses et chercheurs pour pr&eacute;senter leurs travaux, b&eacute;n&eacute;ficier de retours de leurs pairs et contribuer &agrave; la formation d&rsquo;une nouvelle g&eacute;n&eacute;ration de sp&eacute;cialistes du droit du num&eacute;rique. Pour l&rsquo;&eacute;dition 2026, la r&eacute;flexion portera sur le th&egrave;me&nbsp;<strong>&laquo;&nbsp;Droit, num&eacute;rique et autonomie&nbsp;&raquo;&nbsp;</strong>explor&eacute; sous trois axes majeurs: (1) l&rsquo;autonomie des &Eacute;tats et des insitutions, (2) l&rsquo;autonomie individuelle, corporelle, sociale et m&eacute;dicale et (3) l&rsquo;autonomie des syst&egrave;mes num&eacute;riques, des biens et des donn&eacute;es.</p>
<p>Les propositions issues de diff&eacute;rents syst&egrave;mes juridiques et de disciplines vari&eacute;es (sciences politiques, philosophie, &eacute;conomie, sociologie, informatique, etc.) sont vivement encourag&eacute;es.</p>
<p><strong>Soumission&nbsp;:</strong>&nbsp;<a rel="noopener">jeuneschercheursnumerique@gmail.com</a></p>
<p><strong>Date limite:&nbsp;</strong>23 f&eacute;vrier 2026 &agrave; 23h59</p>
<p><strong>Pour plus de d&eacute;tails:&nbsp;</strong><a href="https://www.chairelrwilson.ca/files/sites/36/2026/01/Appel-a-communication-VL_CJDN-2026.pdf" rel="noopener noreferrer" target="_blank">Appel &agrave; communication VL_CJDN 2026</a></p>]]></content>
	<updated>2026-05-07T01:22:41+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-05-07T01:22:41+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-05-01:/286709</id>
	<link href="https://www.gautrais.com/presse/votre-recours-a-lia-au-boulot-pourrait-etre-illegal/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=votre-recours-a-lia-au-boulot-pourrait-etre-illegal" rel="alternate" type="text/html"/>
	<title type="html">Votre recours à l’IA au boulot pourrait être illégal (La Presse, 1 mai 2026)</title>
	<summary type="html"><![CDATA[<p>Pratiquez-vous l&rsquo;intelligence artificielle fant&ocirc;me&nbsp;? Peut-&ecirc;tre le faites-vous sans m&ecirc;me le savoir, e...</p>]]></summary>
	<content type="html"><![CDATA[<p>Pratiquez-vous l&rsquo;intelligence artificielle fant&ocirc;me&nbsp;? Peut-&ecirc;tre le faites-vous sans m&ecirc;me le savoir, et c&rsquo;est probablement ill&eacute;gal. Vous rendez votre employeur passible d&rsquo;une amende, en vertu de dispositions de la loi&nbsp;25 qu&eacute;b&eacute;coise et du&nbsp;<em>CLOUD Act</em>&nbsp;am&eacute;ricain, qui s&rsquo;opposent sur la question de la protection des renseignements personnels des Qu&eacute;b&eacute;cois.</p>
<h4><a href="https://www.lapresse.ca/affaires/2026-05-01/entorse-possible-a-la-loi-25/votre-recours-a-l-ia-au-boulot-pourrait-etre-illegal.php" rel="noopener noreferrer" target="_blank">Pour en savoir +</a></h4>]]></content>
	<updated>2026-05-01T14:31:14+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-05-01T14:31:14+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-27:/286321</id>
	<link href="https://law.stanford.edu/2026/04/27/2026-llm-x-law-hackathon-6-winners/" rel="alternate" type="text/html"/>
	<title type="html">2026 LLM x Law Hackathon #6 Winners</title>
	<summary type="html"><![CDATA[<p>On April 12, 2026, as part of CodeX FutureLaw Week, some of the brightest minds in artificial intell...</p>]]></summary>
	<content type="html"><![CDATA[<p>On April 12, 2026, as part of CodeX FutureLaw Week, some of the brightest minds in artificial intelligence and law gathered for the LLM &times; Law Hackathon &mdash; a full-day event bringing together AI innovators, machine learning specialists, and legal professionals to build the next generation of legal technology. Over the course of a single day, participants moved beyond theory and into practice, prototyping tools at the intersection of large language models and the legal system. The hackathon wasn&rsquo;t just a competition; it was a glimpse into what becomes possible when the people who understand AI and the people who understand law are finally in the same room, building together.</p>
<h2>1st Place &ndash; Overall: ClauseWise<br>
Sharpe Challenge Winner<br>
PatentVC | Trademarkia Winner</h2>
<p><img fetchpriority="high" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners.png" alt="2026 LLM x Law Hackathon #6 Winners" srcset="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-300x225.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-768x576.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-107x80.png 107w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-220x165.png 220w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-300x225.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-768x576.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-107x80.png 107w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-220x165.png 220w" sizes="(max-width: 800px) 100vw, 800px" referrerpolicy="no-referrer" loading="lazy"></p>
<p>ClauseWise is a logic-based middleware designed to bridge the gap between static legal text and active financial systems. It transforms contracts from passive documents into executable code, allowing for automated enforcement and &ldquo;what-if&rdquo; scenario modeling.</p>
<p><strong>The Challenge: &ldquo;The Execution Gap&rdquo;</strong></p>
<ul>
<li>AI Hallucinations: Standard LLMs are probabilistic, meaning they &ldquo;guess&rdquo; terms rather than calculate them, which is dangerous for legal compliance.</li>
<li>Revenue Leakage: Companies lose roughly 9% of revenue annually because they fail to track complex contract triggers like late fees or price escalations hidden in PDFs.</li>
<li>Trust Issues: There is no standard way to turn machine logic back into human-readable legal text without losing the original intent.</li>
</ul>
<p><strong>The Solution: A Two-Way Pipeline</strong></p>
<ul>
<li>Parsing: Converts messy contract text into a Structured Intermediate Representation (IR) that understands math, dates, and conditions.</li>
<li>Execution: A &ldquo;Logic Runner&rdquo; simulates facts (e.g., a late payment) to determine exactly what is owed or who is in breach.</li>
<li>Decompilation: A deterministic decompiler (non-LLM) converts that logic back into English to ensure the output is audit-ready and byte-identical to the intended law.</li>
</ul>
<p><strong>Market Impact</strong></p>
<ul>
<li>Target: Corporate Legal and FinTech departments managing high-volume, complex agreements (SLA credits, procurement, debt).</li>
<li>Value Prop: It shifts legal teams from reactive &ldquo;document reviewers&rdquo; to proactive &ldquo;logic managers.&rdquo;</li>
<li>Core Benefit: Eliminates &ldquo;contract leakage&rdquo; and provides the transparent, verifiable results required for regulatory and judicial scrutiny.</li>
</ul>
<figure aria-describedby="caption-attachment-565379"><img decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7.png" alt="2026 LLM x Law Hackathon #6 Winners 6" srcset="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7-300x225.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7-768x576.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7-107x80.png 107w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7-220x165.png 220w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7-300x225.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7-768x576.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7-107x80.png 107w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-7-220x165.png 220w" sizes="(max-width: 800px) 100vw, 800px" referrerpolicy="no-referrer" loading="lazy"><figcaption>Raj Abhyanker (PatentVC | Trademarkia) with members of the ClauseWise team</figcaption></figure>
<p><strong>Team</strong><br>
<a href="https://www.linkedin.com/in/alex-moon/" target="_blank" rel="noopener noreferrer">Alex Moon, PM at Coupa Software</a><br>
<a href="https://arminheydari.com/" rel="noopener noreferrer" target="_blank">Armin Heydari, PhD Candidate at Harvard University</a><br>
<a href="https://www.linkedin.com/in/danhong-cao-784715170/" rel="noopener noreferrer" target="_blank">Danhong Cao, Associate at Fenwick &amp; West</a><br>
Harit Patel, Builder<br>
Yuvraj Taneja, High School Student and an AI Builder.</p>
<h2>1st Runner Up &ndash; Miranda AI &ndash; Voice AI for the Moment Rights Matter</h2>
<p><img decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2.png" alt="2026 LLM x Law Hackathon #6 Winners 1" srcset="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2-300x225.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2-768x576.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2-107x80.png 107w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2-220x165.png 220w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2-300x225.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2-768x576.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2-107x80.png 107w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-2-220x165.png 220w" sizes="(max-width: 800px) 100vw, 800px" referrerpolicy="no-referrer" loading="lazy"></p>
<p><span>Every day, thousands of people are arrested and pushed into a legal system they don&rsquo;t understand. Critical information&mdash;about their rights, their charges, and what happens next&mdash;is delivered at the worst possible moment: when they are stressed, intoxicated, confused, frustrated or unable to process it.</span></p>
<p><span>As a result, that information doesn&rsquo;t land.</span></p>
<ul>
<li><span>This creates cascading bottlenecks during booking and processing:</span></li>
<li><span>Individuals don&rsquo;t understand instructions or next steps and make avoidable mistakes</span></li>
<li><span>Jail staff must repeat information and manage frustrations</span></li>
<li><span>Systems slow down due to inmate frustration</span></li>
</ul>
<p><span><a href="https://github.com/kollaikal-rupesh/miranda-ai" rel="noopener noreferrer" target="_blank">Miranda is a voice agent</a> that anyone can call directly from jail / anywhere to get immediate, clear, state-specific information about their rights, their case, and what to expect next. This reduces confusion, improves compliance, and removes friction across the system.</span></p>
<p><span>For jails, this means:</span></p>
<ul>
<li><span>Fewer repeated questions and less strain on staff</span></li>
<li><span>Smoother booking and intake processes</span></li>
<li><span>Potential to reduce escalations by giving inmates a clear answers</span></li>
</ul>
<p><span>When Miranda identifies that someone may need legal representation, it connects them with a partner law firm who matches their case. With the individual&rsquo;s consent, Miranda shares a structured summary of the interaction.</span></p>
<ul>
<li><span>This benefits everyone:</span></li>
<li><span>Individuals get faster access to the right lawyer</span></li>
<li><span>Lawyers receive pre-qualified leads, pre-briefed clients</span></li>
<li><span>Jails save time and money dealing with frustrated inmates</span></li>
</ul>
<p><span>US law firms spend $2.5B annually on advertising. The US jail phone call industry generates $1.4B annually. Our mission is to modernize access to preliminary legal information. Through this mission, and an expansion into all areas where private citizens first interact with our justice system&ndash;hospitals, civil courts, etc. &ndash;we intend to become the #1 source of converted leads for lawyers.&nbsp;</span></p>
<p><span>&nbsp;Built on a multi-agent voice pipeline: Pipecat, Deepgram, GPT (13 multi-agent tools), Cartesia, PostgreSQL, and LangGraph.&nbsp;</span></p>
<p><strong>Team</strong><br>
<span><a href="https://www.linkedin.com/in/kollaikalrupesh/" rel="noopener noreferrer" target="_blank">Kollaikal Rupesh</a><br>
</span><span>Ruomeng Sun<br>
</span><span><a href="https://www.linkedin.com/in/charleybmoore/" rel="noopener noreferrer" target="_blank">Charley Moore</a>&nbsp;</span></p>
<h2>2nd Runner Up: Bridge</h2>
<p><img loading="lazy" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3.png" alt="2026 LLM x Law Hackathon #6 Winners 2" srcset="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3-300x281.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3-768x718.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3-86x80.png 86w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3-220x206.png 220w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3-300x281.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3-768x718.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3-86x80.png 86w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-3-220x206.png 220w" sizes="(max-width: 800px) 100vw, 800px" referrerpolicy="no-referrer"></p>
<p><span>Bridge is a legal intelligence platform that helps firms turn senior review into scalable associate training. It captures the value hidden in redlines and revisions so every correction becomes part of a firm&rsquo;s collective know-how, not just a one-off edit.</span></p>
<p><span>In most firms, senior lawyers spend time correcting junior work, but the insight behind those edits is lost once the document is returned. Bridge changes that by helping firms learn from how their best lawyers review, so associates improve faster, firms develop more consistent standards, and institutional knowledge compounds over time.</span></p>
<p><span>The product is designed to fit into existing lawyer workflows without asking seniors to change how they work. By sitting between senior and junior lawyers, Bridge makes it easier for firms to preserve judgment, reduce repeated mistakes, and build stronger legal teams over time.</span></p>
<p><span><strong>Team</strong><br>
</span><span><a href="https://www.linkedin.com/in/ayomide-oloyede/" rel="noopener noreferrer" target="_blank">Ayomide O. Oloyede</a><br>
</span><span><a href="https://www.linkedin.com/in/irisscai/" rel="noopener noreferrer" target="_blank">Iris Cai</a><br>
</span><span><a href="https://www.linkedin.com/in/malti-john-7718922b4/" rel="noopener noreferrer" target="_blank">Malti John</a><br>
</span><span><a href="https://www.linkedin.com/in/mihir-modi-1b68b5357/" rel="noopener noreferrer" target="_blank">Mihir Modi</a><br>
</span><a href="https://www.linkedin.com/in/tejaswitakharel/" rel="noopener noreferrer" target="_blank"><span>Tejaswita Kharel</span></a></p>
<h2>Harvey Challenge Winner:<strong> Warhol: AI Copyright Defense</strong></h2>
<p><img loading="lazy" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4.png" alt="2026 LLM x Law Hackathon #6 Winners 3" srcset="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4-300x225.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4-768x576.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4-107x80.png 107w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4-220x165.png 220w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4-300x225.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4-768x576.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4-107x80.png 107w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-4-220x165.png 220w" sizes="(max-width: 800px) 100vw, 800px" referrerpolicy="no-referrer"></p>
<p><span>52% of designers now use generative AI tools. 2.5 billion images are stolen every day, which constitutes more than $600 billion in annual damages from lost licensing fees alone. And AI tools aren&rsquo;t just getting better at generating images. They&rsquo;re getting better at finding infringement. The copyright storm isn&rsquo;t on the horizon. It&rsquo;s here. In-house IP clearance teams built for a pre-AI world and freelance creatives working without legal cover aren&rsquo;t remotely prepared for what&rsquo;s coming.</span></p>
<p><span>The exposure is massive and almost entirely unaddressed. Designers, marketers, and agencies generate AI images daily for commercial work: for landing pages, ad campaigns, product mockups, merchandise, etc., and with little real visibility into whether those outputs resemble copyrighted works. Today&rsquo;s copyright image search tools only catch exact copies. They can&rsquo;t evaluate stylistic similarity, compositional overlap, or the legal doctrines that actually determine infringement (e.g. Fair Use, Substantial Similarity, Merge, Scenes a Faire, etc.). The gap between how copyright law works and the tools that impact it has never been wider.</span></p>
<p><span>Warhol is a copyright legal agent that closes that gap. It searches the internet for visually similar prior works using multi-provider reverse image search, scores candidates through a machine learning similarity pipeline that goes far beyond pixel matching, and runs the top matches through a doctrine-aware legal analysis layer &mdash; evaluating substantial similarity, fair use, merger, scenes a faire, and independent creation &mdash; grounded in real case law. Integrated directly into your AI image tool, Warhol evaluates any generated image in one click and delivers a structured copyright risk report before you ship.</span></p>
<p><span><strong>Team</strong><br>
</span><span><a href="https://www.linkedin.com/in/willdinneen/" rel="noopener noreferrer" target="_blank">Will Dinneen</a><br>
</span><span><a href="https://www.linkedin.com/in/joshfwaldman/" rel="noopener noreferrer" target="_blank">Josh Waldman</a><br>
</span><span><a href="https://www.linkedin.com/in/chris-taejoon-um-116b50181/" rel="noopener noreferrer" target="_blank">Chris Um</a><br>
</span><span>Dhanin Wongpanich&nbsp;</span></p>
<h2>Band AI Challenge Winner: <strong>Cura: Multi-Modal Agentic Dataroom Creation</strong></h2>
<p><img loading="lazy" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5.png" alt="2026 LLM x Law Hackathon #6 Winners 4" srcset="https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5-300x225.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5-768x576.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5-107x80.png 107w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5-220x165.png 220w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5.png 800w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5-300x225.png 300w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5-768x576.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5-107x80.png 107w,https://law.stanford.edu/wp-content/uploads/2026/04/2026-llm-x-law-hackathon-6-winners-5-220x165.png 220w" sizes="(max-width: 800px) 100vw, 800px" referrerpolicy="no-referrer"></p>
<p><span>312 hours per lawyer per year are lost on document management challenges. In M&amp;A, the pain is sharpest. Over 10,000 U.S. deals close each year, each requiring hundreds of documents compiled under a closing clock. That means weeks of email ping-pong, associates at $600/hour chasing PDFs, and 40% of large deals missing their projected closing timeline. Virtual data rooms didn&rsquo;t fix this.</span></p>
<p><span>Cura&rsquo;s multi-modal agentic document retrieval gives in-house counsel more time to spend on high value judgment matters. Picture an M&amp;A deal. The outside lawyer sends a checklist to the seller and the seller&rsquo;s in-house counsel is now on a wild goose chase to retrieve the documents requested. What if agents could help?&nbsp;</span></p>
<p><span>The client gets a guided flow &mdash; think TurboTax for legal documents. AI agents run in parallel across local storage, Google Drive, QuickBooks, and bank accounts via Plaid &mdash; finding, classifying, and renaming every document automatically. The lawyer opens a complete data room with AI summaries and pre-populated disclosure schedules before the first meeting. Zero follow-up emails. The first conversation is law, not logistics.</span></p>
<p><span>The firms that adopt Cura compress timelines and capture margin. The ones that don&rsquo;t keep lighting money on fire chasing PDFs.&nbsp;</span></p>
<p><strong>Team</strong><br>
<span><a href="https://www.linkedin.com/in/william-mcdugald/" rel="noopener noreferrer" target="_blank">Will McDugald&nbsp;</a><br>
</span><span><a href="https://www.linkedin.com/in/solapm/" rel="noopener noreferrer" target="_blank">Sola Melville Paterson-Marke</a><br>
</span><span>Kaitlyn Angel Kwan<br>
</span><span><a href="https://www.linkedin.com/in/taruni-kavuri-87a38916b/" rel="noopener noreferrer" target="_blank">Taruni Kavuri</a><br>
</span><a href="https://www.linkedin.com/in/emmanueldaudu/" rel="noopener noreferrer" target="_blank"><span>Emmanuel O. Daudu</span></a></p>
<p>&nbsp;</p>
<p><em>Photos by Pierre-Loic Doulcet and Jay Mandal</em></p>
<div>
<div></div>
</div>]]></content>
	<updated>2026-04-27T17:50:35+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-04-27T17:50:35+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="codex"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-27:/286312</id>
	<link href="https://law.stanford.edu/2026/04/27/even-chiles-neurorights-leave-inferred-mental-data-in-a-gray-zone/" rel="alternate" type="text/html"/>
	<title type="html">Even Chile’s Neurorights Leave Inferred Mental Data in a Gray Zone</title>
	<summary type="html"><![CDATA[<p>Chile is often described as one of the strongest constitutional examples of neurorights&mdash;that is, spe...</p>]]></summary>
	<content type="html"><![CDATA[<p>Chile is often described as one of the strongest constitutional examples of neurorights&mdash;that is, special legal protection for brain-related information and mental integrity.[1] In 2021, Chile amended its Constitution to require special protection for brain activity and the information derived from it.[2] In a 2023 decision, the Supreme Court ordered Emotiv, a US consumer-neurotechnology company, to delete the brain-activity data of a Chilean user collected through its Emotiv Insight headset. The Court held that the company&rsquo;s storage of that data violated his rights to mental integrity and privacy. [3] In 2024, however, Chile&rsquo;s public health authority concluded that the same product did not fall within ordinary medical-device regulation because it was not intended for diagnosis or treatment.[4] Chile has gone unusually far in recognizing that brain-related information deserves special legal attention, yet it still does not clearly resolve how law should treat information inferred from neural activity once it is processed and used outside a traditional medical setting.</p>
<p>Chile&rsquo;s 2021 constitutional amendment was ambitious because it did more than add another privacy rule. Law No. 21.383 amended article 19, number 1, of the Constitution and stated that scientific and technological development must serve people and respect both physical and psychic integrity&mdash;that is, a person&rsquo;s bodily and mental integrity.[5] It also added that the law must specially safeguard &ldquo;brain activity&rdquo; and &ldquo;the information derived from it.&rdquo;[6] That wording matters. It clearly reaches beyond the raw electrical signal itself. At the same time, it leaves an obvious follow-up question. How far does protection extend once neural activity is turned into later-stage information, such as a score, a profile, or another output produced by software? The Constitution marks out a protected area, but it does not by itself tell us which institution supervises each kind of downstream information, what remedies apply, or where non-medical consumer neurotechnology fits in the broader legal system.</p>
<p>The Supreme Court&rsquo;s 2023 Emotiv ruling shows why the constitutional text matters. The case was brought by former senator Guido Girardi Lav&iacute;n, one of the initiators of the constitutional reform that later became Law No. 21.383.[7] According to the judiciary&rsquo;s official summary, the Court held that the commercialization and storage of the claimant&rsquo;s brain-activity data violated not only his physical and psychic integrity but also his privacy rights.[8] It therefore ordered Emotiv to eliminate all stored information linked to the claimant&rsquo;s use of the device, and to do so without further procedure.[9] The Court also instructed the Instituto de Salud P&uacute;blica (ISP), Chile&rsquo;s public health authority, and the customs authority to act within their powers so that the commercialization and use of the device, and the handling of the data it collected, would comply with Chilean law.[10] This was a real remedy. It showed that neurorights language in Chile was not merely symbolic.</p>
<p>But the ruling was only clear at one level&mdash;stored information collected through the device&mdash;and less clear on other issues. This is important. Emotiv Insight is not just a passive EEG recorder. Emotiv presents the product as a consumer headset that can collect raw EEG data while also providing information or performing actions for users such as performance metrics, facial-expression detections, and &ldquo;mental command&rdquo; features. The Court&rsquo;s decision most clearly addressed the storage of the claimant&rsquo;s brain-activity data and the legality of the device&rsquo;s commercialization and use in Chile. It did not, at least on the face of the official materials, fully specify how law should classify and govern later software-generated scores, profiles, or inferences derived from that data&mdash;especially once the ISP later concluded that Insight was not being marketed as a medical device.</p>
<p>Acting on that instruction, the ISP issued a 2024 technical report classifying Emotiv Insight under Chilean sanitary-control rules. That report makes the distinction easier to see. The agency explained that the key issue under Chile&rsquo;s sanitary-control rules&mdash;the regulatory regime governing medical products and devices&mdash;was not simply whether the device used EEG technology, but whether it was intended for medical purposes.[11] In other words, the question was not simply &ldquo;does this device interact with the brain?&rdquo; but &ldquo;is this device being marketed and used as a medical device?&rdquo; The ISP noted that Emotiv presented Emotiv Insight as a product for research applications and personal use, not as a tool for diagnosis or treatment.[12] For that reason, the agency concluded that Emotiv Insight was not a medical device and therefore did not fall within the ISP&rsquo;s ordinary jurisdiction on that basis.[13] The ISP resolutions database separately lists Resolution No. 3147 of May 31, 2024 as determining the sanitary-control regime for Emotiv Insight.[14] That conclusion matters because it reveals a gap that is easy to miss. A consumer neurotechnology product can still interact with brain activity and produce user-facing outputs, yet remain outside a familiar medical-device pathway. Once that is true, the legal problem changes. The question is no longer whether Chile recognizes that brain-related information matters&mdash;it clearly does. The harder question is which legal pathway governs non-medical, software-mediated, and potentially inferential uses of information derived from neural activity.</p>
<p>A fair response is that Chile&rsquo;s constitutional text may already be broad enough. One could argue that &ldquo;information derived from&rdquo; brain activity is an intentionally wide phrase, and that the Emotiv ruling proves Chilean courts can act when neurotechnology threatens mental integrity and privacy.[15] Some commentators go further and argue that the neurorights provision may not have done all the work in the Emotiv case, because ordinary privacy and data-protection law could already have supported much of the result.[16] That criticism should be taken seriously. But it does not eliminate the gray zone. Even if existing privacy and data-protection law could have supported the deletion remedy, the neurorights provision does something those rules do not: it gives information &ldquo;derived from&rdquo; brain activity a distinct constitutional status. The official materials currently show a strong constitutional principle, a meaningful deletion remedy, and an agency conclusion that the product at issue does not fall neatly within ordinary medical-device regulation.[17] They also leave open the possibility of further judicial intervention, even if the ISP does not treat the product as a medical device. But that is not the same as a settled governance framework. Courts may provide ex post remedies in particular disputes; they do not by themselves identify a clear ex ante regulator for non-medical, software-generated scores, profiles, or inferences.</p>
<p>This is not simply a story about data storage. It is a story about legal translation. Chile has clearly said that brain-related information matters, but it has not yet made equally clear how some forms of derived or inferred mental data should be classified, supervised, and remedied in non-medical consumer contexts.</p>
<p>The pending legislation confirms that this translation is still in progress. Bolet&iacute;n No. 13.828-19, a bill that would implement the 2021 constitutional provision with detailed rules on neurorights and neurotechnology research, has passed the Senate and is now before the Chamber of Deputies.[18] Official Chamber materials also show that, during the week of April 6&ndash;8, 2026, the Commission continued considering the bill and heard presentations on it, and that, in the following week, it scheduled a session to hear expert views on the bill, including that of Rafael Yuste, the Columbia neuroscientist who helped shape Chile&rsquo;s neurorights framework. [19] Chile therefore looks less like a finished model than like a legal system still trying to convert constitutional recognition into operational governance. That does not make Chile less important. It makes Chile more revealing. Chile matters not because it has fully solved neurotechnology law, but because even its strongest rights-based framework still forces us to confront a harder question: what should law do once a system moves beyond collecting neural signals and begins producing information inferred from them?</p>
<h3>References</h3>
<p>[1] Lorena Guzm&aacute;n H., Chile: Pioneering the Protection of Neurorights, UNESCO Courier (Mar. 21, 2022) (last updated Oct. 13, 2023), <a href="https://courier.unesco.org/en/articles/chile-pioneering-protection-neurorights" rel="noopener noreferrer" target="_blank">https://courier.unesco.org/en/articles/chile-pioneering-protection-neurorights</a>.</p>
<p>[2] Ley No. 21.383, Diario Oficial [D.O.], Oct. 25, 2021, art. &uacute;nico (Chile).</p>
<p>[3] <em>Girardi/Emotiv Inc</em>., Corte Suprema [C.S.], Rol No. 105065-2023, Aug. 9, 2023 (Chile); see also Poder Judicial de Chile, Neuroderechos: <em>Corte Suprema ordena eliminar informaci&oacute;n recogida por dispositivo de monitoreo de actividad cerebral</em> (Aug. 11, 2023).</p>
<p>[4] Inst. de Salud P&uacute;blica de Chile, Informe T&eacute;cnico RCS No. 33-A/24: Informe de Evaluaci&oacute;n de Solicitud de R&eacute;gimen de Control Sanitario, &ldquo;Emotiv Insight&rdquo; at 5&ndash;6 (Mar. 2024); Inst. de Salud P&uacute;blica de Chile, Resoluciones, Resoluci&oacute;n 3147, Determina R&eacute;gimen de Control Sanitario del Producto Emotiv Insight (May 31, 2024).</p>
<p>[5] Ley No. 21.383, supra note 2.</p>
<p>[6] Id.</p>
<p>[7] Proyecto de Reforma Constitucional, Bolet&iacute;n No. 13.827-19 (Oct. 7, 2020) (moci&oacute;n of Senators Guido Girardi, Carolina Goic, Francisco Chahu&aacute;n, Juan Antonio Coloma, and Alfonso De Urresti) (which later became Ley No. 21.383).</p>
<p>[8] Poder Judicial de Chile, supra note 3.</p>
<p>[9] Id.</p>
<p>[10] Id.</p>
<p>[11] Inst. de Salud P&uacute;blica de Chile, Informe T&eacute;cnico RCS No. 33-A/24, supra note 4, at 1&ndash;3.</p>
<p>[12] Id. at 3.</p>
<p>[13] Id. at 5&ndash;6.</p>
<p>[14] Inst. de Salud P&uacute;blica de Chile, Resoluciones, supra note 4.</p>
<p>[15] Ley No. 21.383, supra note 2; Poder Judicial de Chile, supra note 3.</p>
<p>[16] Alejandra Z&uacute;&ntilde;iga-Fajuri et al., Neurorights in Chile: Between Neuroscience and Legal Science, in REGULATING NEUROSCIENCE: TRANSNATIONAL LEGAL CHALLENGES 165, 165&ndash;79 (Mart&iacute;n Hevia ed., 2021).</p>
<p>[17] Poder Judicial de Chile, supra note 3; Inst. de Salud P&uacute;blica de Chile, Informe T&eacute;cnico RCS No. 33-A/24, supra note 4, at 5&ndash;6.</p>
<p>[18] <em>Proyecto de Ley sobre protecci&oacute;n de los neuroderechos y la integridad mental, y el desarrollo de la investigaci&oacute;n y las neurotecnolog&iacute;as</em>, Bolet&iacute;n No. 13.828-19, segundo tr&aacute;mite constitucional (Chile).</p>
<p>[19] C&aacute;mara de Diputadas y Diputados, Citaciones Semana del 06 al 08 de abril de 2026 (Comisi&oacute;n de Futuro, Ciencias, Tecnolog&iacute;a, Conocimiento e Innovaci&oacute;n); C&aacute;mara de Diputadas y Diputados, Citaciones Semana del 13 al 15 de abril de 2026 (same commission).</p>]]></content>
	<updated>2026-04-27T16:50:43+00:00</updated>
	<author><name>Law and Biosciences Blog</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-04-27T16:50:43+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>

	<category term="bioethics"/>

	<category term="brain data"/>

	<category term="chile"/>

	<category term="human rights law"/>

	<category term="medical devices"/>

	<category term="medicine"/>

	<category term="mental privacy"/>

	<category term="neurorights"/>

	<category term="neuroscience"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-23:/286013</id>
	<link href="https://www.gautrais.com/conferences/seminaire-lintelligence-artificielle-transforme-la-pratique-du-droit-mais-quen-est-il-de-son-enseignement/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=seminaire-lintelligence-artificielle-transforme-la-pratique-du-droit-mais-quen-est-il-de-son-enseignement" rel="alternate" type="text/html"/>
	<title type="html">Cristiano Therrien, Séminaire&amp;#160;: L’intelligence artificielle transforme la pratique du droit, mais qu’en est-il de son enseignement&amp;#160;?, Salle A-3421(22 avril 2026)</title>
	<summary type="html"><![CDATA[<p>&nbsp;
La Chaire L.R. Wilson a le plaisir d&rsquo;organiser un s&eacute;minaire portant sur les impacts, les enje...</p>]]></summary>
	<content type="html"><![CDATA[<p>&nbsp;</p>
<p>La Chaire L.R. Wilson a le plaisir d&rsquo;organiser un s&eacute;minaire portant sur les impacts, les enjeux et les questions autour de l&rsquo;IA dans l&rsquo;enseignement du droit. Ce s&eacute;minaire sera anim&eacute; par l&rsquo;excellent&nbsp;<a spellcheck="false" href="https://www.linkedin.com/preload/#" rel="noopener noreferrer" target="_blank">Cristiano Therrien</a>.</p>
<p>&#128204; Facult&eacute; de droit, salle A-3421&nbsp;;</p>
<p>&#128197; 22 avril &agrave; 16 h&nbsp;;</p>
<p>&#127908; Anim&eacute; par Cristiano Therrien&nbsp;;</p>
<p>&#128233; <strong>Sur invitation</strong>. si vous &ecirc;tes int&eacute;ress&eacute;s, merci de contacter&nbsp;: luka.sanchez@umontreal.ca</p>
<p>Une occasion de r&eacute;fl&eacute;chir aux enjeux p&eacute;dagogiques soulev&eacute;s par l&rsquo;int&eacute;gration de l&rsquo;IA dans la formation juridique&nbsp;: transformation des comp&eacute;tences attendues, remise en question des m&eacute;thodes d&rsquo;&eacute;valuation et red&eacute;finition du r&ocirc;le de l&rsquo;enseignant.</p>]]></content>
	<updated>2026-04-23T00:44:39+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-04-23T00:44:39+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-23:/286011</id>
	<link href="https://law.stanford.edu/2026/04/22/why-ai-cannot-forget-genomic-data/" rel="alternate" type="text/html"/>
	<title type="html">Why AI Cannot Forget Genomic Data</title>
	<summary type="html"><![CDATA[<p>The right to be forgotten is becoming increasingly difficult to enforce in practice for genomic data...</p>]]></summary>
	<content type="html"><![CDATA[<p>The right to be forgotten is becoming increasingly difficult to enforce in practice for genomic data trained on Artificial Intelligence (AI) models. Once genomic data is used to train AI models, it becomes embedded in the model&rsquo;s parameters. As these systems learn, they can enable the re-identification of individuals and the inference of health risks.[1] Even where valid consent exists, a model&rsquo;s future inferences may exceed the original scope of consent or persist after the data subject&rsquo;s lifetime.</p>
<p>Genomic data is inherently familial, connecting an individual to a vast network of biological relatives. The inferential capabilities of AI enable the identification not only of data subjects but also potentially of their family members, who have neither been informed nor given consent. AI thus reframes privacy concerns from unauthorized access to ongoing predictive inference about individuals and their relatives. This means that traditional data protection law, built around individual control over retrievable records that can be located and erased, is mismatched with how AI actually processes genomic data. At the same time, machine unlearning, which aims to remove particular data points from a trained model, remains technically challenging.</p>
<h3><strong>The Legal Disconnect</strong></h3>
<p>The right to be forgotten was established following the Court of Justice of the European Union (CJEU)&rsquo;s 2014 <em>Google Spain v AEPD </em>decision.[2] This right was later codified in Article 17 of the European Union General Data Protection Regulation (GDPR), which authorizes data subjects to request the deletion of their personal data under specific circumstances.[3] By contrast, the United States lacks a federal equivalent. [4] Instead, the right to be forgotten is regulated under a patchwork of state laws, such as the California Consumer Privacy Act (CCPA).[5]</p>
<p>The right to be forgotten centers on the threshold of personal data. Under the GDPR, this is defined broadly as any information relating to an identified or identifiable person, including genetic and pseudonymized data.[6] Similarly, the CCPA covers these terms and extends to &ldquo;abstract digital formats,&rdquo; a category that captures AI systems capable of outputting personal information.[7] The CCPA further recognizes &ldquo;unique identifiers&rdquo; that identify a consumer or family, as well as &ldquo;probabilistic identifiers&rdquo; that link a consumer or device using specific data categories.[8] However, these frameworks primarily address outputs or stored records, not the internal architecture of AI models. It remains unclear how the right to be forgotten should apply to internal model parameters that encode learned patterns that enable inferences. Regarding genomic AI, a model does not require access to a data subject&rsquo;s stored DNA sequence; it only needs to have learned the relevant patterns to infer traits about the data subject or their family.</p>
<p>A recent case further illustrates this disconnect. In the CJEU&rsquo;s <em>EDPS v SRB</em> 2025 decision, data stripped of direct identifiers remains protected as personal data if re-identification is &ldquo;reasonably likely.&rdquo; The determination depends on the technical, organizational, and legal measures available to the specific recipient.[9] However, this reasoning presumes a static dataset capable of re-identification, instead of a probabilistic model that generates inferences from learned patterns. Moreover, the right to be forgotten is centered on an individualistic right. Yet, genomic data is inherently shared in nature. Consider siblings who share genomic data: if one consents to sharing their data while the other requests deletion. Whose right prevails? Does one sibling&rsquo;s erasure undermine the other&rsquo;s autonomy? This becomes even more complex when considering the entire network connected to that single data point. This tension suggests the need to reconsider privacy rights at a collective or familial level. As genomic data is a shared resource, an AI model serves as a population-wide asset. In that setting, individual removal might impact the broader data environment.</p>
<h3><strong>The Technical Reality: Machine Unlearning</strong></h3>
<p>A comprehensive solution for machine unlearning remains technically elusive. Existing methods experience significant scale limitations and are not yet suitable for routine deployment in large-scale production systems. The most direct approach to delete specific data and retrain the model from scratch is computationally expensive. Ideally, an effective &ldquo;unlearning&rdquo; standard would balance three competing objectives: speed and cost, privacy, and fairness. Speed requires unlearning to be performed quickly and efficiently. Privacy demands erasure of the targeted data&rsquo;s influence on model parameters. Fairness ensures that removing data from one group does not degrade predictions or utility for other groups.[10] Fairness is particularly challenging because models typically evaluate groups and relationships rather than isolated individuals. Removing a single data point potentially distorts comparisons and the fairness constraints in which that point played a role. Deleting one record may require updating parameters at the group or population level to restore balance within the model. These adjustments could introduce new biases or reduce overall model performance.[11]</p>
<p>In the context of genomic data, even if direct data was surgically removed, embedded familial patterns can persist within the model&rsquo;s learned parameters. This challenge is further complicated by the increasingly interdependent algorithmic supply chains. Major tech companies, such as Amazon, Microsoft, and Google, offer integrated &ldquo;all-in-one&rdquo; packages where foundation models and downstream applications are tightly coupled.[12] In this setting, unlearning a single record does not guarantee the erasure of those patterns across the entire supply chain&rsquo;s architecture. These technical limitations directly challenge the obligations to remove data &ldquo;without undue delay&rdquo; under the GDPR&rsquo;s requirement, or within the CCPA&rsquo;s 45 to 90 day timeframe.[13]</p>
<h3><strong>Looking Ahead</strong></h3>
<p>The convergence of genomic data and AI has exposed the limits of the right to be forgotten in both the legal framework and technical reality. This highlights the need for a modernized legal framework that prioritizes collective rights and algorithmic accountability over individualistic control. Moving forward, as AI-trained genomic data moves toward breakthroughs that could save millions, it introduces a tension between the individual&rsquo;s right to be forgotten and the collective right to health. The solution likely lies not in absolute erasure, but in governing how AI remembers, ensuring that persistence of data serves the public good.</p>
<h3><strong>References</strong></h3>
<p>[1] Giacomo Nebbia et al., Re-identification of Patients from Imaging Features Extracted by Foundation Models (2025), <a href="https://www.nature.com/articles/s41746-025-01801-0" rel="noopener noreferrer" target="_blank">https://www.nature.com/articles/s41746-025-01801-0</a>; Artem Shmatko et al., <em>Learning the Natural History of Human Disease with Generative Transformers </em>(2026), <a href="https://www.nature.com/articles/s41586-025-09529-3" rel="noopener noreferrer" target="_blank">https://www.nature.com/articles/s41586-025-09529-3</a>; and Rose Orenbuch et al., <em>Proteome-wide Model for Human Disease Genetics</em> (2025), <a href="https://www.nature.com/articles/s41588-025-02400-1" rel="noopener noreferrer" target="_blank">https://www.nature.com/articles/s41588-025-02400-1</a>.</p>
<p>[2] European Union, <em>Right to be Forgotten on the Internet </em>(2022), <a href="https://eur-lex.europa.eu/EN/legal-content/summary/right-to-be-forgotten-on-the-internet.html" rel="noopener noreferrer" target="_blank">https://eur-lex.europa.eu/EN/legal-content/summary/right-to-be-forgotten-on-the-internet.html</a> (ruling that the search engine operator has a responsibility to remove links to personal information from search results in specific circumstances). See also, Judgment of the Court (Grand Chamber), 13 May 2014. Google Spain SL and Google Inc. v Agencia Espa&ntilde;ola de Protecci&oacute;n de Datos (AEPD) and Mario Costeja Gonz&aacute;lez.</p>
<p>[3] EU GDPR, Article 17.1 (a)-(f) and Article 17.3 (stating conditions for erasure under Article 17.1(a)-(f), such as the data subject withdraws consent, or the personal data have been unlawfully processed. And, providing circumstances when the right to erasure shall not apply to the extent that processing is necessary, such as for exercising the right of freedom of expression and information).</p>
<p>[4] A comprehensive federal privacy framework has not been adopted in the United States. Data protection is governed by sector-specific laws, such as the Health Insurance Portability and Accountability Act (HIPAA) and the Genetic Information Nondiscrimination Act (GINA).</p>
<p>[5] CCPA, Section 1798.105.</p>
<p>[6] EU GDPR, Articles 4(1), 4(5), and 4(13).</p>
<p>[7] CCPA, Section 1798.140 (v)(4)(c) (defining that personal information can exist in abstract digital formats, including compressed encrypted files, metadata, or artificial intelligence systems that are capable of outputting personal information.); <em>see also</em> California Assembly Bill No. 1008 (2024).</p>
<p>[8] CCPA, Sections 1798.140 (x) and 1798.140 (aj).</p>
<p>[9] European Data Protection Supervisor v Single Resolution Board (EDPS v SRB), Appeal, Case C-413/23 P.&nbsp; (Sept. 4, 2025), <a href="https://eur-lex.europa.eu/legal-content/EN/TXT/?uri=celex:62023CJ0413" rel="noopener noreferrer" target="_blank">https://eur-lex.europa.eu/legal-content/EN/TXT/?uri=celex:62023CJ0413</a>.</p>
<p>[10] Alex Oesterling, et al., <em>Fair Machine Unlearning: Data Removal While Mitigating Disparities</em> (2023), <a href="https://proceedings.mlr.press/v238/oesterling24a/oesterling24a.pdf" rel="noopener noreferrer" target="_blank">https://proceedings.mlr.press/v238/oesterling24a/oesterling24a.pdf</a>.</p>
<p>[11] Id.; <em>see also</em> George-Octavian Barbulescu and Francois Buet-Golfouse, <em>Unfair Unlearning? Accounting for Fairness in Machine Unlearning </em>(2018), <a href="https://kdd2025.kdd.org/wp-content/uploads/2025/07/paper_23.pdf" rel="noopener noreferrer" target="_blank">https://kdd2025.kdd.org/wp-content/uploads/2025/07/paper_23.pdf</a>;</p>
<p>[12] Jennifer Cobbe, <em>Understanding Accountability in Algorithmic Supply Chains</em> (2023), <a href="https://arxiv.org/abs/2304.14749" rel="noopener noreferrer" target="_blank">https://arxiv.org/abs/2304.14749</a>.</p>
<p>[13] Ben Wolford, <em>Everything You Need to Know About the &ldquo;Right to be Forgotten&rdquo;</em>, <a href="https://gdpr.eu/right-to-be-forgotten/" rel="noopener noreferrer" target="_blank">https://gdpr.eu/right-to-be-forgotten/</a>(stating that &ldquo;undue delay&rdquo; is considered to be about a month); CCPA, Section 1798.130(a)(2)(A).</p>
<p></p>]]></content>
	<updated>2026-04-23T01:41:29+00:00</updated>
	<author><name>Natnicha Sutthivana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-04-23T01:41:29+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>

	<category term="bioethics"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-22:/286001</id>
	<link href="https://law.stanford.edu/2026/04/22/digital-brain/" rel="alternate" type="text/html"/>
	<title type="html">Stanford Computational Antitrust offers to help antitrust agencies build their own digital brain</title>
	<summary type="html"><![CDATA[<p>Palo Alto, April 22, 2026. Starting today, Stanford Computational Antitrust is available to help ant...</p>]]></summary>
	<content type="html"><![CDATA[<p>Palo Alto, April 22, 2026. Starting today, Stanford Computational Antitrust is available to help antitrust agencies worldwide build queryable knowledge systems from their own decisional records.</p>
<p>The offer follows a <a href="https://papers.ssrn.com/sol3/papers.cfm?abstract_id=6594359" rel="noopener noreferrer" target="_blank">forthcoming guide</a> in the Network Law Review by Thibault Schrepel, creator and director of the Stanford Computational Antitrust project. The build takes a few hours with very little technical skills.</p>
<p>To show what is possible, Dr. Schrepel built one such system from all European Commission competition decisions spanning 1977 to 2025. The system maps the corpus as an interactive knowledge graph. Each decision is a node. Each doctrinal link is an edge. Users can see at a glance which decisions the Commission&rsquo;s own case law treats as foundational, and where its reasoning has drifted or fragmented over time.</p>
<p><img fetchpriority="high" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-1024x936.jpg" alt="Stanford Computational Antitrust offers to help competition agencies build their own digital brain 1" srcset="https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-1024x936.jpg 1024w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-300x274.jpg 300w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-768x702.jpg 768w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-1536x1404.jpg 1536w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-1152x1053.jpg 1152w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-88x80.jpg 88w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-220x201.jpg 220w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2.jpg 1580w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-1024x936.jpg 1024w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-300x274.jpg 300w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-768x702.jpg 768w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-1536x1404.jpg 1536w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-1152x1053.jpg 1152w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-88x80.jpg 88w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2-220x201.jpg 220w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-competition-agencies-build-their-own-digital-brain-2.jpg 1580w" sizes="(max-width: 1024px) 100vw, 1024px" referrerpolicy="no-referrer" loading="lazy"></p>
<p>The best part comes next. The graph generates a private Wikipedia powered by the corpus. On demand, it produces a wiki page on any theme covered by the decisions, with cross-links to related topics and a master index. A user can ask for a page on ecosystem theories of harm. The system writes it from the decisions, cites the relevant cases, and links to every adjacent topic. Ask a follow-up question and the answer feeds back into the knowledge base as a new page. The more the system is used, the more connections it builds. It does not generate content beyond what the decisions contain. It does not hallucinate a case that does not exist.</p>
<p><img decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-982x1024.png" alt="Stanford Computational Antitrust offers to help antitrust agencies build their own digital brain" srcset="https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-982x1024.png 982w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-288x300.png 288w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-768x801.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-1152x1201.png 1152w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-77x80.png 77w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-220x229.png 220w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain.png 1414w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-982x1024.png 982w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-288x300.png 288w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-768x801.png 768w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-1152x1201.png 1152w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-77x80.png 77w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain-220x229.png 220w,https://law.stanford.edu/wp-content/uploads/2026/04/stanford-computational-antitrust-offers-to-help-antitrust-agencies-build-their-own-digital-brain.png 1414w" sizes="(max-width: 982px) 100vw, 982px" referrerpolicy="no-referrer" loading="lazy"></p>
<p>The applications extend beyond research. Agencies can give the system to case handlers. A handler drafting an abuse of dominance decision can query every prior decision on market definition and identify where the reasoning has shifted. Court of appeals rulings can be integrated into the same graph. Handlers can see which theories survived appeal, which were reversed. Inconsistencies surface before a decision is issued rather than on appeal.</p>
<blockquote><p>&ldquo;Every competition agency faces the same problem,&rdquo; said Schrepel. &ldquo;Hundreds of decisions accumulated over decades. No one has read them all. No one remembers them in enough detail to catch contradictions as they emerge. A draft decision could be checked against the full decisional record before it is issued. Inconsistencies could surface before they reach appeal, not after.&rdquo;</p></blockquote>
<p>The project is open to partnering with agencies that want to build their own system. Each agency&rsquo;s corpus is different. The methodology adapts to it. The project team will advise on design, corpus preparation, and deployment.</p>
<p>Agencies interested in exploring this should contact: schrepel@stanford.edu</p>
<p>The guide is available open access on SSRN: <a href="https://papers.ssrn.com/sol3/papers.cfm?abstract_id=6594359" rel="noopener noreferrer" target="_blank">https://papers.ssrn.com/sol3/papers.cfm?abstract_id=6594359</a></p>
<p>Contact<br>
Thibault Schrepel<br>
schrepel@stanford.edu</p>]]></content>
	<updated>2026-04-22T18:15:18+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-04-22T18:15:18+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-22:/285944</id>
	<link href="https://law.stanford.edu/2026/04/21/less-invasion-more-inclusion-ivgs-potential-impact-on-posthumous-gamete-retrieval/" rel="alternate" type="text/html"/>
	<title type="html">Less Invasion, More Inclusion: IVG’s Potential Impact on Posthumous Gamete Retrieval</title>
	<summary type="html"><![CDATA[<p>Posthumous conception remains one of the most contested practices in assisted human reproduction (AH...</p>]]></summary>
	<content type="html"><![CDATA[<p>Posthumous conception remains one of the most contested practices in assisted human reproduction (AHR), with objections often centering on the invasive nature of retrieving gametes from the deceased or dying. [1] <em>In vitro</em>gametogenesis (IVG) is a developing technique that aims to derive gametes from ordinary somatic cells. The process involves taking non-reproductive cells, such as skin or hair, and reprogramming them into pluripotent stem cells, which can then be guided to become viable gametes for AHR. [2, 3] Though still in the early stages of clinical development, recent IVG studies in non-human animal models have yielded promising results, and some experts have predicted that the technique could be used to generate human gametes within the next decade. [4]</p>
<p>If human application is successful, IVG imagines a pathway where gametes are generated <em>ex vivo</em> without needles into testes, ovarian hyperstimulation, or surgery. As I have argued in a recent paper, this could be particularly significant for posthumous conception in several ways. [5] First, IVG would remove the race against the clock that currently defines post-mortem gamete retrieval. [6] Second, it would weaken one of the most persistent ethical objections to the practice: invasiveness. [1] Third, by avoiding hormone cycles and surgical collection, IVG could markedly increase the availability of female gametes for posthumous use, narrowing a longstanding gender gap in this area. [5]</p>
<h3><strong>Less Invasion:</strong></h3>
<p>At present, sperm procurement varies in invasiveness depending on whether the source is alive, incapacitated, or deceased. Competent living men can usually provide sperm through ejaculation, sometimes assisted by penile vibratory stimulation or electroejaculation. [7] When a man is comatose or dying, retrieval is generally preferred before circulatory death because sperm motility declines rapidly afterward. [8] After death, the window for retrieval is narrow, with viable sperm typically recoverable for only 24&ndash;36 hours. [6] Once circulation has ceased, surgical methods are generally required, ranging from needle aspiration to open testicular biopsy. In practice, guidance recommends open surgical retrieval of testicular tissue post-mortem in order to obtain enough sperm for multiple IVF cycles. [8]</p>
<p>Against this backdrop, objections to posthumous gamete retrieval routinely foreground invasiveness. [1] In comatose patients, retrieval offers no therapeutic benefit, leading some to doubt whether it can ever be in the patient&rsquo;s interests. Here, &ldquo;harm&rdquo; is not limited to pain, but may include non-experiential interests in bodily integrity or in avoiding genetic parenthood. [9] Others argue that once cardiac or brain-stem death has been declared, there is no rights-bearing person left to be harmed, and so bodily-violation claims lose force. [10] Still others maintain that interests in bodily integrity survive death, such that surgical retrieval remains invasive and objectionable. [1, 9]</p>
<p>IVG could directly target this concern. Because somatic tissue can be obtained far less invasively than gametes (and in some cases without touching the body at all, as with shed hairs on a hairbrush or saliva from a toothbrush) the technology could remove both the physical invasion and the race against time that currently define posthumous gamete retrieval.</p>
<h3><strong>More Inclusion:</strong></h3>
<p>The implications for women may be even more significant. To date, posthumous conception has relied overwhelmingly on cryopreserved gametes or embryos stored during life, or on posthumous sperm retrieval. Egg retrieval, by contrast, is an intensive and invasive process whether the woman is alive, incapacitated, or deceased. [11]</p>
<p>For egg cryopreservation, patients typically undergo controlled ovarian hyperstimulation involving daily gonadotropin injections over nine to ten days, followed by surgical retrieval of mature eggs. Retrieval from a comatose or dying woman is technically possible, but it still requires hormone stimulation and surgery while the patient is incapacitated. Post-mortem egg retrieval is more difficult still. Without oxygen, eggs cease to be viable within hours, making retrieval unrealistic unless stimulation has already been completed. [11]</p>
<p>The practical effect is a persistent disparity between sperm banking and egg cryopreservation. Sperm banking is comparatively simple and inexpensive, whereas egg storage requires hormonal stimulation and surgery. As a result, stored sperm is far more commonly available than stored eggs, even as egg-freezing rates rise. [12] And although egg retrieval from a dead or dying woman is technically possible, it is highly invasive, time-sensitive, and rarely attempted. [13] Here, IVG could be transformative. By bypassing ovarian stimulation and surgical retrieval entirely, IVG could enable women to store eggs without those interventions, increasing the number of women with eggs in storage and improving the availability of female gametes for posthumous use. In that sense, IVG is not only a less invasive technology; it is potentially a more inclusive one.</p>
<h3><strong>What IVG Cannot Change:</strong></h3>
<p>IVG could narrow the gender gap that currently exists in the availability of gametes for posthumous use. But any parity effect would depend on cost, safety, social acceptability, and clinical capacity. Moreover, posthumous conception using eggs still raises practical asymmetries in that if the surviving partner is male, a gestational carrier would be required. If the surviving partner is female and able to carry the pregnancy, donor sperm would still be needed unless, in some speculative future, IVG made it possible to derive functional sperm from her somatic cells. [14]</p>
<p>More fundamentally, reducing invasiveness will not end debates about autonomy, consent, or the weight some place on the right not to be a genetic parent. IVG may decouple posthumous conception from the specific concern that gamete retrieval is an invasive physical affront, but it does not resolve whether a person authorized posthumous reproductive use at all. Nor can IVG settle broader concerns about the future child&rsquo;s interests, inheritance and so forth. Those questions remain regardless of how gametes are obtained. [5]</p>
<h3><strong>References:</strong></h3>
<p>[1] A.R. Schiff, &lsquo;Arising from the Dead: Challenges of Posthumous Procreation&rsquo; (1997) 75(3) <em>North Carolina Law Review </em>901.</p>
<p>[2] K. Bowman, C. Matney and E.P. Dawson (eds.), <em>In Vitro&ndash;Derived Human Gametes as a Reproductive Technology: Scientific, Ethical, and Regulatory Implications: Proceedings of a Workshop</em> (National Academies Press, 2023).</p>
<p>[3] H.T. Greely, <em>The End of Sex and the Future of Human Reproduction</em> (Harvard University Press, 2026).</p>
<p>[4] H. Devlin, &lsquo;Lab-grown sperm and eggs just a few years away, scientists say&rsquo; <em>The Guardian</em> (5 July 2025), &lt;https://www.theguardian.com/science/2025/jul/05/lab-grown-sperm-and-eggs-scientists-reproduction&gt;.</p>
<p>[5] C. McGovern, &lsquo;From scalpel to statute: IVG&rsquo;s impact on invasiveness and gender parity in posthumous conception&rsquo; (2026) 34(1) <em>Medical Law Review</em> 2.</p>
<p>[6] A. Jequin and M. Zhang, &lsquo;Practical Problems in the Posthumous Retrieval of Sperm&rsquo; (2014) 29(12) <em>Human Reproduction</em> 2615.</p>
<p>[7] H. Rozati, T. Handley, and C. Jayasena, &lsquo;Process and Pitfalls of Sperm Cryopreservation&rsquo; (2017) 6(9) <em>Journal of Clinical Medicine</em> 89.</p>
<p>[8] C.M. Rothman, &lsquo;A Method for Obtaining Viable Sperm in the Postmortem State&rsquo; (1980) 34(5) <em>Fertility and Sterility</em>512.</p>
<p>[9] G. Pitcher, &lsquo;The Misfortunes of the Dead&rsquo; (1984) 21 <em>American Philosophical Quarterly</em> 183.</p>
<p>[10] J. Harris, &lsquo;Law and Regulation of Retained Organs: The Ethical Issues&rsquo; (2002) 22 <em>Journal of Legal Studies</em> 527.</p>
<p>[11] M. Soules, &lsquo;Commentary: Posthumous Harvesting of Gametes &ndash; A Physicians Perspective&rsquo; (1999) 27 <em>Journal of Law, Medicine and Ethics</em> 362.</p>
<p>[12] Department of Health and Social Care, <em>Gamete (egg, sperm) and embryo storage limits: response to consultation</em>(September 2021).</p>
<p>[13] D. Greer, A. Styer, T. Toth, C. Kindregan and J. Romero, &lsquo;Case 21-2010: A Request for Retrieval of Oocytes from a 36-Year-Old Woman with Anoxic Brain Injury&rsquo; (2010) 363 <em>The New England Journal of Medicine </em>276.</p>
<p>[14] A. Le Goff, R. Jeffries Hein, A.N. Hart, I. Roberson and H.L. Landecker, &lsquo;Anticipating in&nbsp;vitro gametogenesis: Hopes and concerns for IVG among diverse stakeholders&rsquo; (2024) 19(7) <em>Stem Cell Reports</em> 933.</p>
<p></p>]]></content>
	<updated>2026-04-21T23:05:28+00:00</updated>
	<author><name>Claire McGovern</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-04-21T23:05:28+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-21:/285935</id>
	<link href="https://www.gautrais.com/conferences/lia-juridique-au-quebec-ou-en-sommes-nous-vraiment/?utm_source=rss&amp;utm_medium=rss&amp;utm_campaign=lia-juridique-au-quebec-ou-en-sommes-nous-vraiment" rel="alternate" type="text/html"/>
	<title type="html">L’IA juridique au Québec&amp;#160;: où en sommes-nous vraiment&amp;#160;?, L’IA juridique au Québec : où en sommes-nous vraiment ?, En ligne(21 avril 2026)</title>
	<summary type="html"><![CDATA[<p>Rejoignez notre panel d&rsquo;experts le&nbsp;21 avril de 12 h 00 &agrave; 13 h 00&nbsp;avec Me Dominique Monette de Stikem...</p>]]></summary>
	<content type="html"><![CDATA[<p>Rejoignez notre panel d&rsquo;experts le&nbsp;<strong>21 avril de 12 h 00 &agrave; 13 h 00</strong>&nbsp;avec Me Dominique Monette de Stikeman, Me Hugues Langlais de Cabinet Me Hugues Langlais, Me Vincent Gautrais de l&rsquo;Universit&eacute; de Montr&eacute;al ainsi que notre mod&eacute;ratrice Madame Ranishta Sonah de LexisNexis Canada, pour une discussion sur l&rsquo;&eacute;tat de l&rsquo;intelligence artificielle dans l&rsquo;&eacute;cosyst&egrave;me juridique qu&eacute;b&eacute;cois.</p>
<p>Cette pr&eacute;sentation fera le point sur le niveau d&rsquo;adoption de l&rsquo;IA dans les cabinets d&rsquo;avocats au Qu&eacute;bec, et nos conf&eacute;renciers discuteront des outils les plus utilis&eacute;s, qu&rsquo;ils soient g&eacute;n&eacute;ratifs ou sp&eacute;cialis&eacute;s.</p>
<p><strong>Le webinaire explorera notamment:</strong></p>
<p>&bull; Les enjeux de responsabilit&eacute; professionnelle li&eacute;s &agrave; l&rsquo;usage de l&rsquo;IA<br>
&bull; Les nouvelles comp&eacute;tences requises pour les juristes<br>
&bull; L&rsquo;interaction avec la Loi 25 en mati&egrave;re de protection des renseignements personnels<br>
&bull; Les d&eacute;veloppements f&eacute;d&eacute;raux &agrave; venir en intelligence artificielle, dont la Loi C-27</p>
<p>Une s&eacute;ance essentielle pour les professionnels du droit qui souhaitent comprendre les enjeux actuels, anticiper les &eacute;volutions r&eacute;glementaires et adapter leurs pratiques.</p>]]></content>
	<updated>2026-04-21T14:57:21+00:00</updated>
	<author><name>Vincent Gautrais</name></author>
	<source>
		<id>https://www.gautrais.com</id>
		<link rel="self" href="https://www.gautrais.com"/>
		<updated>2026-04-21T14:57:21+00:00</updated>
		<title>Vincent Gautrais</title></source>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-20:/285857</id>
	<link href="https://law.stanford.edu/2026/04/20/new-article-alba-ribera-martinez/" rel="alternate" type="text/html"/>
	<title type="html">New Article in Stanford Computational Antitrust: Computational Presumptions Applied to AI Markets</title>
	<summary type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces the publication of &ldquo;Computational Presu...</p>]]></summary>
	<content type="html"><![CDATA[<p>The <a href="https://law.stanford.edu/computationalantitrust" rel="noopener noreferrer" target="_blank">Stanford Computational Antitrust Project</a> announces the publication of &ldquo;Computational Presumptions Applied to AI Markets&rdquo; by Alba Ribera Mart&iacute;nez. The article appears in Volume 6 of Stanford Computational Antitrust (pp. 32-67).</p>
<p>Digital regulators worldwide are imposing sweeping bans on data combinations to eliminate data asymmetries and learning effects. The paper argues that these interventions reveal a critical disconnect. Rules such as those introduced by the EU&rsquo;s Digital Markets Act and the UK&rsquo;s Digital Markets, Competition and Consumers Act were designed for traditional platforms. They are now being applied to AI downstream markets whose competitive dynamics differ. Reinforcement learning and model drift disrupt the standard feedback loops. The distinction between across-user and within-user learning further complicates the picture.</p>
<p>Building on this diagnosis, the article proposes an alternative instrument. Computational presumptions grounded in verifiable privacy-utility thresholds can serve as measurable compliance mechanisms. The paper identifies a NIST-aligned threshold of 2 &lt; &epsilon; &lt; 8 as a workable safe harbor, and shows how the same logic can extend to federated learning and homomorphic encryption through functionally equivalent indicators. The resulting framework transforms the regulator&rsquo;s task from tracking every prohibited data combination to auditing a single measurable parameter.</p>
<p>Thibault Schrepel, founder of the Stanford Computational Antitrust Project, stated:</p>
<blockquote>
<p>&ldquo;Alba Ribera Mart&iacute;nez offers one of the clearest demonstrations that the DMA&rsquo;s architecture does not transpose cleanly to AI markets. Her proposal gives regulators something measurable to audit instead of an unmanageable monitoring task. This is constructive legal scholarship.&rdquo;</p>
</blockquote>
<p>Alba Ribera Mart&iacute;nez is a Visiting Professor at the Brussels Study Centre and an Editor-in-Chief of Stanford Computational Antitrust. The article is available for download on the <a href="https://law.stanford.edu/publications/computational-presumptions-applied-to-ai-markets/" rel="noopener noreferrer" target="_blank">Stanford Computational Antitrust project&rsquo;s page</a>.</p>]]></content>
	<updated>2026-04-20T14:55:03+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-04-20T14:55:03+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-20:/285858</id>
	<link href="https://law.stanford.edu/2026/04/10/new-article-neves-bussmann/" rel="alternate" type="text/html"/>
	<title type="html">New Article in Stanford Computational Antitrust: Smart Agent-Based Modelling with LLMs and Algorithmic Collusion</title>
	<summary type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces the publication of &ldquo;Smart Agent-Based M...</p>]]></summary>
	<content type="html"><![CDATA[<p>The <a href="https://law.stanford.edu/computationalantitrust" rel="noopener noreferrer" target="_blank">Stanford Computational Antitrust Project</a> announces the publication of &ldquo;Smart Agent-Based Modelling with LLMs: Leveraging Large Language Models for a Better Understanding of Algorithmic Collusion&rdquo; by Carlos Eduardo Veras Neves and Tanise Brandao Bussmann. The article appears in Issue VI of Stanford Computational Antitrust (pp. 1-31).</p>
<p>The paper introduces a Smart Agent-Based Modelling (SABM) framework within computational antitrust to simulate and detect the conditions that foster algorithmic collusion. The authors run Bertrand duopoly simulations in which LLM-driven agents stabilize prices above competitive levels without being explicitly instructed to do so. Simulations conducted in English and Portuguese show that linguistic context shapes outcomes. Communication between agents amplifies emergent behaviors, including the mimicking of concerns about collusion itself.</p>
<p>The contribution bridges market simulation and antitrust enforcement. By giving authorities an accessible tool to reproduce collusive conditions in silico, SABM offers a path to stress-test theories of harm before they materialize in real markets. The framework speaks directly to the open question of how regulators should address autonomous algorithmic collusion when no explicit agreement can be documented.</p>
<p>Thibault Schrepel, founder of the Stanford Computational Antitrust Project, stated:</p>
<blockquote>
<p>&ldquo;Carlos Eduardo Veras Neves and Tanise Brandao Bussmann contribute a practical instrument to a debate that has too often remained abstract. Their simulations confirm that LLM-driven pricing agents can drift into tacit collusion without being told to. Any agency thinking about how to monitor these markets should take note.&rdquo;</p>
</blockquote>
<p>The article is available for download <a href="https://law.stanford.edu/publications/smart-agent-based-modelling-with-llms-leveraging-large-language-models-for-a-better-understanding-of-algorithmic-collusion/" rel="noopener noreferrer" target="_blank">over here</a>.</p>]]></content>
	<updated>2026-04-10T14:55:16+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-04-10T14:55:16+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-08:/284889</id>
	<link href="https://law.stanford.edu/2026/04/08/when-claude-code-meets-apples-app-store/" rel="alternate" type="text/html"/>
	<title type="html">When Claude Code Meets Apple’s App Store </title>
	<summary type="html"><![CDATA[<p>Apple&rsquo;s App Store submission is one of the more demanding gatekeeping mechanisms in consumer s...</p>]]></summary>
	<content type="html"><![CDATA[<p>Apple&rsquo;s App Store submission is one of the more demanding gatekeeping mechanisms in consumer software. It requires accurate privacy disclosures, published security standards, measurable performance and accessibility thresholds, and design compliance reviewed by human reviewers. With Artificial General Intelligence (AGI) claims refusing to die, I decided to take a look at whether Claude Code would fit the bill and what would happen if I brought an app from Claude Code and introduced it to the App Store.</p>
<p>Claude Code moves fast at ideation, screen mapping, scaffolding, and boilerplate generation, and developers have shipped real apps this way. But at the back of the development life cycle, where compliance, privacy disclosure, security architecture, and App Store submission live, the human cost reasserts itself. Studies of AI-generated code indicate a significant share requires refactoring to meet Apple&rsquo;s accessibility and performance standards, and a meaningful fraction of AI-driven apps fail review due to privacy or design violations.</p>
<p>A little more than three years ago, I began developing the <a href="https://ailccp.replit.app" rel="noopener noreferrer" target="_blank">AI Life Cycle Core Principles (AILCCP)</a>. This is a framework&mdash;and now an app&mdash;that organizes AI development and deployment obligations across 37 principles, 10 development phases, and 48 controls, mapped to international standards and regulatory enforcement contexts. It gives developers, deployers, lawyers, and policymakers a shared vocabulary and methodology for assessing where an AI system meets its obligations and where it falls short across the development and deployment life cycle. I use it to granularly analyze things like AI legislation, policies, AI vendor agreements, AI governance documents, and questions such as whether Claude Code is AGI. The AILCCP contains 37 principles, each with multiple requirements. Three principles apply most directly here: Wherewithal, Human-Centered, and Workforce Compatible. For each, I focus on the requirements most relevant to what the App Store test exposes, then apply it to Claude Code.</p>
<p><b>Wherewithal</b> asks whether the capability matches what is being claimed. The enthusiasm around AI coding tools has generated claims that Claude Code can take a developer from idea to shipped app with minimal effort. That framing describes the front of the life cycle accurately and the back poorly, and developers who plan around it will discover the gap at exactly the point where it costs the most to close.</p>
<p><b>Human-Centered</b> requires human-in-the-loop oversight at the pre-deployment review and deployment phases. Those are the phases where an iOS app is tested against Apple&rsquo;s privacy guidelines, where data handling disclosures are drafted and verified, where security architecture is stress-tested, and where the submission package is assembled and submitted for review. Claude Code does not do those things independently. A developer who has moved quickly through scaffolding and code generation arrives at those phases with the tool&rsquo;s momentum behind them and its limitations fully exposed.</p>
<p><b>Workforce Compatible</b> asks whether an AI tool builds human capability or displaces it. A developer who uses Claude Code to generate iOS code throughout a project never learns iOS development. They learn to prompt. When the tool produces architecturally flawed code, which it does with some regularity, the developer has no independent basis for catching the error. They are dependent on the tool to identify problems that the tool created. That is not augmentation. It is a different kind of dependency, and it grows less visible the more the tool appears to be working.</p>
<p>Claude Code is powerful, without a doubt. But a phase-specific competence at a high level is not what &ldquo;G&rdquo; in AGI means.</p>]]></content>
	<updated>2026-04-08T14:32:14+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-04-08T14:32:14+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="agi"/>

	<category term="anthropic"/>

	<category term="artificial general intelligence"/>

	<category term="eran kahana"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-07:/284816</id>
	<link href="https://law.stanford.edu/2026/04/07/when-the-medium-becomes-the-message-and-the-message-becomes-irrelevant/" rel="alternate" type="text/html"/>
	<title type="html">When the Medium Becomes the Message and the Message Becomes Irrelevant</title>
	<summary type="html"><![CDATA[<p>A widely circulated image purportedly depicting one of the American airmen recently rescued by U.S. ...</p>]]></summary>
	<content type="html"><![CDATA[<p>A widely circulated image purportedly depicting one of the American airmen recently rescued by U.S. special forces from Iran drew millions of views this past week. It drew something else as well: a fact-check. The image, several accounts announced with evident satisfaction, is AI-generated. (Bravo, Inspector Clouseau.) Texas Governor Greg Abbott shared it. Major influencers amplified it. The fact-check lit up the reply threads.</p>
<p>I want to set aside the image and focus on the finger-pointer, because what the act of identification reveals is more interesting than the image itself.</p>
<p>Consider what was not contested. The airman&rsquo;s rescue happened. The emotion expressed by millions of people who engaged with the image was genuine. No one who shared it claimed it was a photograph taken by a photojournalist embedded with the rescue team. Most people who encountered it likely experienced it the way they experience a commemorative illustration, as a visual token for something that actually occurred.</p>
<p>Now consider a cartoon. Suppose someone had drawn the same scene, soldiers in a helicopter, smiling, American flag in hand, in the style of a tasteful editorial illustration, the fact-checkers would have had nothing to say. The drawing would have traveled the same emotional circuit. The soldiers would have been the same soldiers. The rescue would have been the same rescue. The difference between the cartoon and the AI-generated image is purely procedural. The AI image was generated by a statistical model trained on visual data. The cartoon was generated by a human hand trained on visual instruction. In both cases, no camera was present. In both cases, the image is a representation, not a document.</p>
<p>Yuval Noah Harari argued in <em>Sapiens</em> that the human capacity for shared fiction, for constructing and inhabiting stories that are not literally true in a documentary sense, is the source of civilizational cohesion. The story of a rescued soldier, expressed in an image that was never a photograph, is doing exactly this work. It is binding a community around a shared recognition of something that happened and matters. The finger-pointer, by flagging the image&rsquo;s generative provenance, is not adding epistemic content. The finger-pointer is asserting a procedural standard as a substitute for engaging with the story. The question &ldquo;is this AI-generated?&rdquo; has displaced the question &ldquo;is this meaningful?&rdquo; and the displacement is being performed as though it were a contribution to public discourse.</p>
<p>What the finger-pointer is actually doing is performing epistemic status. The detection requires no expertise, but deploying it produces the appearance of rigor: I saw through this, I identified the error, I am the one who knows. This is not fact-checking in any meaningful sense. Fact-checking interrogates claims and the claim here, that American airmen were rescued, is true. What is being fact-checked is the artwork.</p>
<p>This particular form of intervention will become self-obsolete. The precedent is already visible. When Photoshop entered the visual commons in the 1990s, &ldquo;it&rsquo;s been Photoshopped&rdquo; carried the same accusatory charge the AI flag carries today. The charge faded because it became universal. Sharpening, cropping, color grading, exposure correction, skin retouching, background removal, these are now understood as the ordinary conditions of professional image-making, not deviations from it. Nobody pauses before a magazine cover to announce that the photograph has been post-processed.</p>
<p>As generative models improve and AI-generated imagery saturates the visual commons, the identification will carry decreasing signal. When every image could be AI-generated and many will be, announcing that a specific image is AI-generated will produce the same information as announcing that a specific sentence was typed on a keyboard.</p>]]></content>
	<updated>2026-04-07T14:17:39+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-04-07T14:17:39+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="artificial intelligence"/>

	<category term="eran kahana"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-04-06:/284719</id>
	<link href="https://law.stanford.edu/2026/04/05/turning-ai-governance-into-operational-infrastructure/" rel="alternate" type="text/html"/>
	<title type="html">Turning AI Governance Into Operational Infrastructure</title>
	<summary type="html"><![CDATA[<p>I started building the AI Life Cycle Core Principles (AILCCP) framework in March 2023 because I foun...</p>]]></summary>
	<content type="html"><![CDATA[<p>I started building the AI Life Cycle Core Principles (AILCCP) framework in March 2023 because I found that terms like &ldquo;trustworthy,&rdquo; &ldquo;reliable,&rdquo; &ldquo;secure,&rdquo; &ldquo;safe,&rdquo; &ldquo;explainable,&rdquo; &ldquo;robust,&rdquo; and &ldquo;ethical&rdquo; were being used in AI governance with persistent, frustrating ambiguity. That ambiguity might look like flexibility, but it is not. It creates a definitional vacuum that destabilizes the ability of stakeholders to maintain a coherent conversation about what these principles mean and<span>&nbsp; </span>actually require. And when the principles themselves are imprecise, the laws, regulations, standards, and best practices that refer to them inherit that imprecision, and become less effective or entirely ineffective. My work making them more concrete exposed how many adjacent areas needed the same treatment, things like ownership, life cycle coverage, risk interdependencies, standards mapping. The result is the framework as it stands today, and the work is ongoing.<span>&nbsp;</span></p>
<p>With the release of the AILCCP Explorer, an <a href="https://ailccp.replit.app" rel="noopener noreferrer" target="_blank">interactive web application</a> that makes the full framework navigable and searchable, this felt like the right moment to revisit what the AILCCP is, how it works, and why it is built the way it is.<span>&nbsp;</span></p>
<p>The AILCCP is a structured knowledge graph that connects existing principles, controls, international standards, life cycle phases, and identified risks into a single navigable structure with over 500 explicit cross-references. The ambiguity is extinguished.</p>
<h4><b>The AI Governance Problem</b></h4>
<p>ISO/IEC 42001 addresses AI management systems. The NIST AI Risk Management Framework maps risk categories and profiles. IEEE has published standards addressing algorithmic bias, transparency, and system design. The EU AI Act imposes risk-based obligations with enforcement teeth.</p>
<p>But these instruments do not talk to each other. Anyone building, deploying, procuring, or auditing an AI system today must reconcile guidance from them, map their practices to regulatory expectations that often vary by jurisdiction, culture, and produce documentation that satisfies reviewers.</p>
<h4><b>What the AILCCP Is</b><b></b></h4>
<p>The AILCCP is a cross-linked knowledge base built from five components: principles, controls, standards, life cycle phases, and risks. Each one connects to the others through explicit, traceable links.</p>
<p>The framework is built on 37 principles, most of which were distilled from international consensus such as the OECD, UNESCO, G7, G20, and APAC. The AILCCP gives each one a defined scope, an objective, and measurable outcomes so that stakeholders working with different source standards are looking at the same thing. Governance follows an AI system from the first scoping decision through operational monitoring to eventual retirement.</p>
<h4><b>The Architecture</b></h4>
<p><b>37 Principles</b></p>
<p>Each principle includes a short definition, a detailed definition, an objective statement, key questions, suggested controls, required evidence artifacts, and identified stakeholders. The principles are organized across 15 categories and mapped to 10 pillars that span Oversight and Accountability, Reliability and Robustness, Transparency and Explainability, Ethics, Fairness and Equity, Privacy and Consent, Safety and Security, Human-Centered and Workforce concerns, Data and Process stewardship, and Organizational Capability.</p>
<p>Every principle includes a rationale explaining why it belongs in the framework. When stakeholders adapt the framework to their context, the rationale helps them decide which principles matter most for their system.</p>
<p><b>48 Controls</b></p>
<p>Controls are the &ldquo;how.&rdquo; Each is defined by name, domain, function, and rationale, and each maps to its top three principle alignments. Across the full set, this produces 187 control-to-principle links. Every one of the 48 connects to at least one principle, ensuring that implementation guidance always traces back to a governance commitment.</p>
<p>But here is the thing: controls that exist in isolation, disconnected from the principles they are meant to serve, tend to break down. When a control has no explicit link to a principle, stakeholders struggle to explain why they are implementing it, auditors have difficulty assessing whether it is sufficient, and the control becomes a compliance artifact rather than a governance mechanism.</p>
<p><b>43 International Standards</b></p>
<p>The framework maps 43 standards from IEEE, ISO/IEC, and NIST, each with a scope statement, summary, intended use, and identified primary users. Each standard maps to up to five principles, generating 215 standard-to-principle links that touch 29 of the 37 principles.</p>
<p>The 43 standards were selected because they are actionable and recognized across regulatory and audit contexts. Standards are increasingly taking on weight, legitimacy, and force, recognized by legislators, regulators, courts, and the broader developer and implementer ecosystem. When the question is &ldquo;show me the controls for data governance,&rdquo; the answer has to trace to standards that carry that weight.</p>
<p><b>10 Life Cycle Phases</b></p>
<p>The life cycle spans ten phases, from Scoping and Design through Decommissioning and Archiving. Each phase identifies default owners (Product, Legal, ML Engineering, SRE, and others), expected evidence artifacts, and measurable metrics. Across all ten phases, 84 phase-to-principle links map governance commitments to specific moments in the system&rsquo;s life.</p>
<p>Each link comes with a life cycle signal that includes a rationale explaining why that principle matters at that stage. Transparency, for example, means something different during Operations and Monitoring than it does during Scoping and Design.</p>
<p>Scoping and Design tracks requirements coverage percentage and reading level targets. Data Preparation tracks missing and invalid data rates, label agreement scores, and PII leakage tests. Evaluation and Red Teaming tracks bias delta, attack success rates, and coverage percentage. Operations and Monitoring tracks mean time to repair, drift alerts per month, and SLO attainment. Instead of &ldquo;monitor for bias,&rdquo; the framework says &ldquo;measure bias delta during Evaluation and Red Teaming and track drift alerts per month during Operations and Monitoring.&rdquo;</p>
<p><b>18 Identified Risks</b></p>
<p>The risk layer assesses 18 identified risks for severity and likelihood using a qualitative rubric tied to the five pillars. Seven are rated Very High severity, eight High, and three Medium. These risks generate 23 links to standards and touch 24 of the 37 principles, connecting the threat landscape directly to the controls and standards that address it.</p>
<p>As I see it, one of the more distinctive ideas in the framework is the &ldquo;enabling risk&rdquo; concept. The three risks rated Medium severity are transparency and explainability gaps that function as force multipliers for other, more serious harms. A system that lacks Explainability makes every other harm harder to detect, harder to diagnose, and harder to remediate. This layered thinking about risk cascades reflects how AI breakdowns actually propagate in practice.</p>
<p><b>The Cross-Link Network</b></p>
<p>In total, the framework contains over 500 explicit links. 187 control-to-principle. 215 standard-to-principle. 84 phase-to-principle. 23 risk-to-standard. Pick any entry point and trace a path to every other part of the framework.</p>
<h4><b>What Sets the AILCCP Apart</b></h4>
<p><b>Bidirectional Traceability</b></p>
<p>Most governance frameworks are organized top-down. The NIST AI RMF flows from four functions (GOVERN, MAP, MEASURE, MANAGE) down to categories and subcategories, but provides no built-in path from a risk finding back to the relevant activities and standards. ISO/IEC 42001 follows the Annex SL hierarchy common to ISO management standards, with 42 control objectives that trace from clauses downward, but the reverse mapping is left to the implementing organization. The OECD AI Principles offer five principles and five policy recommendations with no controls, no life cycle phases, and no risk mappings at all. In each case, the framework is organized in one direction.</p>
<p>A diligent team can reverse-engineer any of these frameworks. But the AILCCP builds the reverse paths in. Its 500+ explicit cross-references mean a user can start from a risk and trace to the standards and principles that mitigate it, start from a standard and see which principles it supports and which life cycle phases it touches, or start from a life cycle phase and see what should be measured, who owns it, and what evidence needs to be produced.</p>
<p>An auditor starts with a finding, a development team with a life cycle phase, a regulator with a risk. The graph accommodates all of them.</p>
<p><b>Ownership Built In</b></p>
<p>Every life cycle phase names default owners, required evidence artifacts, and measurable metrics. This turns governance from &ldquo;someone should handle this&rdquo; into &ldquo;here is who is responsible, here is what they produce, and here is how it gets measured.&rdquo;</p>
<p>The ownership model spans Product, UX, Legal, Risk, ML Engineering, Data Science, QA, Security, SRE, and Communications, because AI governance requires coordinated action across disciplines.</p>
<p><b>Designed for Audits</b></p>
<p>Because the AILCCP maps finalized, prescriptive standards, it produces references auditors and regulators recognize. When someone asks for evidence of data governance controls, the framework traces to a specific control, its rationale, the principles it implements, and the published standards that back it up. That is what &ldquo;audit-ready&rdquo; looks like in practice, a traceable chain from commitment to evidence.</p>
<p><b>Coverage Visibility</b></p>
<p>With 29 of 37 principles referenced by standards and 24 of 37 referenced by identified risks, the framework makes its own coverage gaps visible. Eight principles are not yet referenced by any mapped standard. Stakeholders can see at a glance which principles have strong standards backing and which need additional work.</p>
<p><b>Who the Framework Serves</b></p>
<p><b>Development teams</b> can use the 48 controls as a checklist during system design and code review, trace a specific risk back to the principles and controls that mitigate it, and identify which standards apply to a given feature or component.</p>
<p><b>Compliance and legal teams</b> can demonstrate alignment with the EU AI Act, ISO/IEC 42001, and other regulatory frameworks, prepare audit-ready documentation by mapping internal practices to published standards, and build a defensible governance narrative for regulators.</p>
<p><b>Risk and audit professionals</b> can use the severity and likelihood rubric to prioritize assessments, trace risks to specific life cycle phases to focus audit scope, and cross-reference internal risk registers against the AILCCP&rsquo;s identified risks.</p>
<p><b>Regulators and policy advisors</b> can use the framework to understand how international standards map to practical governance actions, and evaluate organizational compliance claims against a structured benchmark.</p>
<p><b>Executives and board members</b> can get a strategic view of governance coverage across the five pillars without requiring technical depth, using the framework as a common language between technical teams and leadership.</p>
<p>A small team can use the controls as a lightweight development checklist. A large enterprise can use the full cross-linked structure to build audit documentation, assign ownership across departments, and track metrics at every life cycle phase.</p>
<h4><b>The AILCCP Explorer</b></h4>
<p>The framework is delivered as an interactive, searchable web application called the AILCCP Explorer. The Explorer provides multi-directional navigation. Start from any entity type and trace connections across the knowledge graph. Filter by pillar, phase, risk severity, or standard body. And the Export Library feature enables offline analysis and audit preparation.</p>
<p>The risk assessment methodology is built into the interface with inline explanations, so stakeholders can understand why a risk carries the severity rating it does without consulting a separate document.</p>
<h4><b>Governance as Infrastructure</b></h4>
<p>The AILCCP started with a simple observation: the vocabulary of AI governance was too ambiguous to be operative. Three years later, that initial effort to define terms with precision has grown into a knowledge graph of 37 principles, 48 controls, 43 international standards, 10 life cycle phases, and 18 identified risks, all connected through over 500 explicit cross-references. The framework assigns ownership, specifies measurable metrics at each phase, and traces every control back to the principles and standards it serves. It works in every direction, so that an auditor entering through a finding, a development team starting at a life cycle phase, a compliance officer mapping to regulatory expectations, a board member looking for coverage across pillars, and a regulator focused on a risk are all navigating the same structure.</p>
<p>The work continues and the AILCCP Explorer AI governance<span>&nbsp;</span>accessible.</p>
<p>Explore the <a href="https://ailccp.replit.app" rel="noopener noreferrer" target="_blank">tool</a>. Try it. And tell me what works and what doesn&rsquo;t.</p>]]></content>
	<updated>2026-04-06T02:13:07+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-04-06T02:13:07+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="ai governance"/>

	<category term="ailccp"/>

	<category term="eran kahana"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-03-30:/284137</id>
	<link href="https://law.stanford.edu/2026/03/30/architectural-negligence-what-the-meta-verdicts-mean-for-openai-in-the-nippon-life-case/" rel="alternate" type="text/html"/>
	<title type="html">Architectural Negligence: What the Meta Verdicts Mean for OpenAI in the Nippon Life Case</title>
	<summary type="html"><![CDATA[<p>We saw two verdicts in two days. State of New Mexico v. Meta Platforms, Inc., decided March 24, 2026...</p>]]></summary>
	<content type="html"><![CDATA[<p>We saw two verdicts in two days. <i>State of New Mexico v. Meta Platforms, Inc.</i>, decided March 24, 2026, found Meta liable under New Mexico&rsquo;s Unfair Practices Act for misleading consumers about platform safety and endangering children, and ordered $375 million in civil penalties. The following day, a California jury in <i>K.G.M. v. Meta Platforms, Inc. &amp; YouTube LLC</i> found Meta and YouTube negligent in the design and operation of their platforms, concluding that design features caused addiction and mental health harms and awarded $6 million, half of it punitive. Together, they can be considered the Rosetta Stone for <i>Nippon Life Insurance Co. v. OpenAI</i>, which I wrote about <a href="https://law.stanford.edu/2026/03/07/designed-to-cross-why-nippon-life-v-openai-is-a-product-liability-case/" rel="noopener noreferrer" target="_blank">here</a> and the legal setup in all three cases is identical. What varies is the domain of harm. <i>Meta</i> dealt with child safety. <i>Nippon Life</i> deals with the unauthorized practice of law (UPL). The litigation strategy used in in the March 2026 cases is the same that Nippon Life will likely make in Illinois, and it is the same strategy that will likely be used in every licensed profession plaintiff that AI has in its crosshairs.</p>
<p><b>The Design vs. Content Pivot</b><b></b></p>
<p>Section 230 of the Communications Decency Act functions as an immunity, not an affirmative defense and tech companies typically invoke it in a motion to dismiss to stop litigation before discovery begins. Meta raised arguments in both the New Mexico and California proceedings consistent with Section 230&rsquo;s traditional content-immunity framing, arguing it was a passive conduit for third-party generated content and therefore immune from liability for what that content did. But the courts in both proceedings allowed design-based and consumer protection claims to proceed. That did not immediately resolve the cases, but it opened the door to discovery, and discovery is where the cases were won.</p>
<p>With that door opened, the New Mexico jury was able to see internal Meta documents and evidence uncovered through the NM AG&rsquo;s investigation, including Operation MetaPhile, employee warnings that had been disregarded, and evidence the AG argued showed Meta had deliberately designed its platforms to addict young users and connect them with predators. The California jury saw the same architecture of corporate knowledge and deliberate design choice and responded with punitive damages. Neither jury was deciding whether Meta was responsible for what some predator posted. Both were deciding whether Meta architected the loop that made the harm foreseeable, systematic, and profitable.</p>
<p>Section 230 arguments will be raised in <i>Nippon Life</i>, but the Meta litigation suggests they will face the same limiting analysis. And OpenAI&rsquo;s own System Card, the published disclosure documenting its safety architecture, alignment choices, and residual risk assessments, creates a contradiction that OpenAI cannot easily resolve. When a company publishes a detailed account of how it shapes, filters, and aligns its model&rsquo;s outputs, it has staked out a position that is difficult to reconcile with a neutrality claim. While a defense attorney will argue that Section 230 and the System Card are complementary, one functioning as a legal shield, the other as a failure-to-warn mitigation, the response to that framing is going to be that what matters is not what the company disclosed, but what the company built.</p>
<p><b>This was all Foreseeable</b><b></b></p>
<p>OpenAI&rsquo;s knowledge of its models&rsquo; failure modes is already public. It published research explaining why language models hallucinate, documenting the frequency with which models generate false information with high expressed confidence. Their technical literature on RLHF describes a training methodology that rewards outputs users rate positively, which in practice creates incentives toward outputs that sound authoritative and agreeable, independent of whether they are accurate. And a Stanford University study led by Myra Cheng, <a href="https://arxiv.org/abs/2510.01395" rel="noopener noreferrer" target="_blank">Sycophantic AI Decreases Prosocial Intentions and Promotes Dependence</a>, found widespread social sycophancy across production LLMs, including OpenAI&rsquo;s, concluding that model training rewards agreement as well as accuracy.</p>
<p>Roman Yampolskiy, a computer science and engineering professor and AI safety researcher argues in <i>AI: Unexplainable, Unpredictable, Uncontrollable</i> that LLM developers operate in a state of deep ignorance regarding the internal logic of their own systems. They understand the architecture but have almost no visibility into the reasoning behind any specific output, and that certain safety guarantees are mathematically unreachable for systems of this complexity. If Yampolskiy is correct, the developer cannot claim those failures were unpredictable.</p>
<p><b>The Defective Feature</b><b></b></p>
<p>Product liability doctrine requires the plaintiff to identify a specific, articulable defect. In the Meta litigation, the defects were the infinite scroll, variable-reward notification timing, suppressed engagement signals and algorithmic. Each was an engineering choice that could have been made differently, and this moved the cases from editorial neutrality into product liability territory.</p>
<p>The analogous defect in <i>Nippon Life</i> is the absence of refusal architecture. In my January 2012 <a href="https://law.stanford.edu/2012/01/14/computational-law-applications-unauthorized-practice-law/" rel="noopener noreferrer" target="_blank">Computational Law Applications and the Unauthorized Practice of Law</a> post, I introduced the concept of the uncrossable threshold (UT), a design principle that separates the provision of legal information from UPL. ChatGPT crossed the UT the moment it told Dela Torre that her attorney&rsquo;s advice was wrong.</p>
<p><b>What Follows</b><b></b></p>
<p><i>Nippon Life</i> is lining up to be the first major case to apply the architectural negligence logic of Meta to the domain of unlicensed professional practice. And it will not be the last. If juries in New Mexico and California can hold a technology company liable for designing a system it knew would harm children, a court in Illinois might very well hold a technology company liable for designing a system it knew would practice law and harm not only the end user, but the defendant, the court, the taxpayer, etc. And if this finding can happen in law, it can happen in medicine, finance, and other professional license domains in which AI models are unlawfully used.</p>]]></content>
	<updated>2026-03-30T13:48:45+00:00</updated>
	<author><name>Eran Kahana</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-03-30T13:48:45+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="artificial intelligence"/>

	<category term="eran kahana"/>

	<category term="llm liability"/>

	<category term="rlhf"/>

	<category term="unauthorized practice of law"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-03-30:/284119</id>
	<link href="https://law.stanford.edu/2026/03/30/who-owns-digital-thoughts-the-limits-of-property-law-and-the-2025-unesco-recommendation-on-the-ethics-of-neurotechnology/" rel="alternate" type="text/html"/>
	<title type="html">Who Owns Digital Thoughts? The Limits of Property Law and the 2025 UNESCO Recommendation on the Ethics of Neurotechnology</title>
	<summary type="html"><![CDATA[<p>The rapid advancement of Brain&ndash;Computer Interfaces (BCIs) and artificial intelligence (AI) in neurot...</p>]]></summary>
	<content type="html"><![CDATA[<p>The rapid advancement of Brain&ndash;Computer Interfaces (BCIs) and artificial intelligence (AI) in neurotechnology has moved beyond speculative science and clinical experimentation into commercial and regulatory relevance.[1] Advances in neural sensing and AI now permit systems capable of translating patterns of brain activity into text or other communicative outputs, and in some cases enabling users to control digital systems or physical devices through neural signals. As these technologies increasingly migrate into consumer-facing and workplace settings, they generate novel forms of data: neural signals and the probabilistic inferences derived from them.</p>
<p>As algorithms analyze data from neural activity to generate inferences about cognitive and affective states, a foundational legal question emerges: how should law conceptualize and regulate information that reveals, or purports to reveal, the contents of the human mind? For many years, U.S. data governance has relied heavily on notice-and-consent architectures embedded in privacy statutes and consumer protection law. While American privacy law is not reducible to a pure property regime, it often treats personal data as an object of exchange subject to disclosure and contractual allocation.[2] Whether that structure is adequate for neural data is increasingly contested.</p>
<h2><strong>I. The Limits of Property-Adjacent Privacy Frameworks</strong></h2>
<p>American privacy law&mdash;including statutes such as the California Privacy Rights Act (CPRA)&mdash;reflects a hybrid structure combining consumer protection, informational privacy, and market-based consent mechanisms.[3] Under this framework, data processing is generally permissible provided that firms disclose their practices and individuals are afforded certain forms of consumer choice, including the ability to consent to specific uses of sensitive data, opt out of data sales or sharing, and exercise statutory rights such as access or deletion. Scholars and regulators, however, have long questioned whether digital consent models function as meaningful exercises of autonomy.[4]</p>
<p>The concern is amplified in the neurotechnology context. Users of consumer EEG devices or neuro-adaptive systems may lack the technical capacity to understand how raw neural signals can be transformed into predictive or probabilistic inferences about emotion, attention, or preference.[5] AI systems do not merely collect neural signals; they generate inferential profiles that may have legal or economic consequences.[6] Existing privacy statutes often regulate collection and sharing, but they provide limited procedural mechanisms for contesting algorithmic inferences as such. As Brandon Garrett has argued in the broader AI context, procedural due process principles become salient when automated systems generate determinations that materially affect individuals without meaningful opportunities for explanation or challenge.[7]</p>
<p>A second concern relates to commodification. Conceptualizing neural data primarily as a transferable asset risks normalizing its exchange as a condition of employment, insurance, or service access. Property concepts can be analytically useful in structuring entitlements, but they may insufficiently capture the qualitative distinction between commercial data and information that reveals&mdash;or enables inference about&mdash;an individual&rsquo;s mental life.[8] Where regulation implicates the architecture of cognition itself, dignity and autonomy concerns arise that are not easily reduced to market exchange models.</p>
<p>These critiques do not imply that privacy statutes are irrelevant. Rather, they suggest that additional normative frameworks may be required when technologies directly implicate freedom of thought and mental integrity.</p>
<h2><strong>II. The Human Rights and &ldquo;Neurorights&rdquo; Framework</strong></h2>
<p>In response to these concerns, legal scholars and bioethicists have proposed the development or clarification of &ldquo;neurorights&rdquo;&mdash;interpretations of existing human rights principles tailored to neurotechnological contexts. Marcello Ienca and Roberto Andorno have argued that traditional rights to privacy and bodily integrity may require doctrinal refinement where technologies can access or modulate neural processes.[9]</p>
<p>Central to this discussion is the concept of cognitive liberty, sometimes described as mental self-determination.[10] As articulated by scholars, cognitive liberty encompasses the right to control one&rsquo;s mental processes and to be free from non-consensual intrusion or manipulation. It also implies that individuals should not be subjected to coercive &ldquo;neuro-surveillance&rdquo; or compelled disclosure of cognitive information absent compelling justification.[11]</p>
<p>Related principles include mental privacy and mental integrity. Mental privacy would protect individuals against unauthorized extraction or decoding of neural data.[12] Mental integrity extends established protections against physical interference to technologically mediated interventions that alter or influence cognitive states. Rather than framing the problem primarily in terms of ownership, this approach emphasizes the protection of autonomy, dignity, and freedom of thought.</p>
<p>At the same time, human rights framing is not self-executing. International human rights instruments often operate at a high level of abstraction and depend upon domestic implementation. Without legislative incorporation and enforcement mechanisms, rights-based language may remain aspirational.[13] The analytical question is therefore not whether to invoke human rights, but how to operationalize them within domestic legal systems and translate broadly articulated norms into locally intelligible legal and institutional practices.[14]</p>
<h2><strong>III. The 2025 UNESCO Recommendation: Normative Significance and Limits</strong></h2>
<p>In November 2025, UNESCO adopted the Recommendation on the Ethics of Neurotechnology.[15] As a Recommendation, the instrument does not create binding treaty obligations under international law. It does, however, articulate a normative framework endorsed by UNESCO member states concerning the governance of brain&ndash;computer interfaces and neural data.</p>
<p>The Recommendation situates neurotechnology within a human rights framework, emphasizing human dignity, freedom of thought, mental privacy, and autonomy. It calls upon states to adopt appropriate legal and regulatory measures to prevent harmful uses, including applications that facilitate coercive control, unlawful surveillance, or manipulation. It also highlights the risks associated with deploying neurotechnology in employment and commercial contexts where power asymmetries may undermine meaningful consent.</p>
<p>The Recommendation does not impose enforceable prohibitions. Rather, its significance lies in establishing a shared normative baseline and encouraging domestic reform. The instrument also emphasizes the importance of informed consent in the collection and use of neural data. At the same time, this emphasis highlights a tension identified earlier in the context of notice-and-consent privacy models: consent-based governance models may be insufficient where technologies generate probabilistic inferences about mental states that individuals may not fully understand or control. It reflects an emerging international consensus that neural data warrants treatment beyond ordinary consumer information.</p>
<h2><strong>IV. Conclusion and Policy Implications</strong></h2>
<p>The governance of neurotechnology raises structural questions about the adequacy of existing privacy frameworks. While U.S. consumer privacy statutes in some states provide important tools, they may not fully address technologies that generate inferences about mental states.</p>
<p>A defensible reform agenda would not require abandoning current statutory structures but supplementing them. Legislatures could explicitly classify neural data and derived cognitive inferences as highly sensitive information subject to heightened safeguards. Several U.S. states, including California, Colorado, Montana, and Connecticut, have already begun experimenting with this approach by classifying neural data as sensitive personal information under state privacy statutes, while no comparable federal framework currently exists.[16] They could restrict conditioning employment or essential services on the disclosure of neural information. They could also require meaningful transparency, explainability, and contestability where AI systems draw inferences about cognitive or affective states with material consequences.</p>
<p>The core claim is not that neural data can never be conceptualized within property or privacy frameworks. Rather, it is that legal systems should resist reducing neural information to an ordinary market commodity. Where regulation touches the integrity of mental life, doctrines of autonomy, dignity, and freedom of thought must play a central role.</p>
<h2><strong>References</strong></h2>
<p>[1] See Nita A. Farahany, <em>The Battle for Your Brain</em> (2023) (discussing emerging neurotechnology and its societal implications).</p>
<p>[2] Jane R. Bambauer,&nbsp;<em>How to Get the Property Out of Privacy Law</em>, 133 Yale L.J. F. 1087 (2024).</p>
<p>[3] Cheryl Saniuk-Heinig,&nbsp;<em>Private Rights of Action in US Privacy Legislation</em>, IAPP (June 10, 2024), <a href="https://iapp.org/resources/article/private-rights-of-action-us-privacy-legislation" rel="noopener noreferrer" target="_blank"><br>
https://iapp.org/resources/article/private-rights-of-action-us-privacy-legislation</a>.</p>
<p>[4] Lauren Henry Scholz,&nbsp;<em>The Illusion of Consent: Rethinking Privacy Online</em>, Ga. St. U. L. Rev. (2025),<br>
<a href="https://www.gsulawreview.org/blog/the-illusion-of-consent-rethinking-privacy-online/" rel="noopener noreferrer" target="_blank">https://www.gsulawreview.org/blog/the-illusion-of-consent-rethinking-privacy-online/</a>.</p>
<p>[5] <em>See </em>Farahany,<em> supra</em> note 1.</p>
<p>[6] See Brandon L. Garrett, <em>Artificial Intelligence and Procedural Due Process</em>, 27 U. Pa. J. Const. L. 933 (2025).</p>
<p>[7] <em>Id.</em></p>
<p>[8] Talya Deibel,&nbsp;<em>Private Law and the Inner Self: Comparative Perspectives on the Governance of Neurotechnology</em>, 14 Glob. J. Comp. L. 105 (2025).</p>
<p>[9] Marcello Ienca &amp; Roberto Andorno,&nbsp;<em>Towards New Human Rights in the Age of Neuroscience and Neurotechnology</em>, 19 Life Sci., Soc&rsquo;y &amp; Pol&rsquo;y 5 (2017).</p>
<p>[10] Jan-Christoph Bublitz,&nbsp;<em>&ldquo;My Mind Is Mine!?&rdquo;: Cognitive Liberty as a Legal Concept</em>, in&nbsp;<em>Cognitive Enhancement</em>&nbsp;233 (Elisabeth Hildt &amp; Andreas G. Franke eds., 2013).</p>
<p>[11] Council of Europe,&nbsp;<em>CDBIO Report on Neurotechnologies</em>&nbsp;(2021),&nbsp;<a href="https://rm.coe.int/round-table-report-en/1680a969ed." rel="noopener noreferrer" target="_blank">https://rm.coe.int/round-table-report-en/1680a969ed.</a></p>
<p>[12] <em>See</em>, Ienca &amp; Andorno, <em>supra</em> note 9.</p>
<p>[13] UNESCO,&nbsp;<em>Recommendation on the Ethics of Neurotechnology</em>, U.N. Doc. SHS/BIO/REC-NEURO/2025 (Nov. 2025); U.N. Human Rights Council,&nbsp;<em>Report of the Special Rapporteur on the Right to Privacy</em>, U.N. Doc. A/HRC/58/6 (2025).</p>
<p>[14] Sally Engle Merry, <em>Human Rights and Gender Violence: Translating International Law into Local Justice</em> (Univ. Chicago Press 2005) (describing the process of &ldquo;vernacularization,&rdquo; through which international human rights norms are translated and adapted into local legal and cultural contexts).</p>
<p>[15] <em>See</em> UNESCO, <em>supra</em> note 13.</p>
<p>[16] See Cal. Civ. Code &sect; 1798.140 (West 2025) (classifying neural data as sensitive personal information under the CCPA, as amended by SB 1223); Colo. Rev. Stat. &sect; 6-1-1303(4)(b) (2024) (including neural data within &ldquo;biological data,&rdquo; a sensitive data category under the CPA); <em>see also</em> Mont. Code Ann. &sect; 50-46-102(11) (2025) (defining &ldquo;neurotechnology data&rdquo;); Conn. Gen. Stat. &sect; 42-515(23) (2026) (defining neural data from central nervous system activity).</p>]]></content>
	<updated>2026-03-30T15:01:36+00:00</updated>
	<author><name>Law and Biosciences Blog</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-03-30T15:01:36+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>

	<category term="ai governance"/>

	<category term="brain-computer interface"/>

	<category term="data commodification"/>

	<category term="freedom of thought"/>

	<category term="international human rights"/>

	<category term="mental integrity"/>

	<category term="neuroscience"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-03-25:/283661</id>
	<link href="https://law.stanford.edu/2026/03/19/email-based-ai-agents-for-law-firms-mixus-stanford-codex-group-meeting-3-19-2026/" rel="alternate" type="text/html"/>
	<title type="html">Email-Based AI Agents for Law Firms – Mixus  | Stanford CodeX Group Meeting 3.19.2026</title>
	<summary type="html"><![CDATA[<p>Elliot Katz, co-founder and CEO of Mixus, presented to the Stanford CodeX group about his company...</p>]]></summary>
	<content type="html"><![CDATA[<p>Elliot Katz, co-founder and CEO of Mixus, presented to the Stanford CodeX group about his company&rsquo;s email-based AI agents designed for law firms. Drawing on his background as an attorney and his prior startup Phantom Auto (which kept humans in the loop for autonomous vehicles), Katz built Mixus around the same principle: AI needs human oversight for high-stakes work. Mixus agents work entirely through email &mdash; attorneys simply email tasks in plain language and receive completed work product like redlines, issues lists, and cap tables in return &mdash; eliminating the change management burden that has slowed AI adoption in legal.</p>
<p>The platform includes firm-level approval workflows, automatic playbook generation from past documents, and deterministic gates that prevent outputs from advancing without human sign-off. The discussion touched on concerns around rubber-stamping, attorney-client privilege, and data security, with Mixus addressing those through SOC 2 compliance, zero data retention agreements with their model provider (Anthropic&rsquo;s Claude), and an auditable email trail of who reviewed and approved each output.</p>
<p><img fetchpriority="high" decoding="async" src="https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026.png" alt="Email-Based AI Agents for Law Firms: Mixus CEO on Human-in-the-Loop Legal AI | Stanford CodeX Group Meeting 3.19.2026" srcset="https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026.png 886w,https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026-300x163.png 300w,https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026-768x417.png 768w,https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026-147x80.png 147w,https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026-220x119.png 220w,https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026.png 886w,https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026-300x163.png 300w,https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026-768x417.png 768w,https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026-147x80.png 147w,https://law.stanford.edu/wp-content/uploads/2026/03/email-based-ai-agents-for-law-firms-mixus-ceo-on-human-in-the-loop-legal-ai-stanford-codex-group-meeting-3-19-2026-220x119.png 220w" sizes="(max-width: 886px) 100vw, 886px" referrerpolicy="no-referrer" loading="lazy"></p>
<p><a href="https://youtu.be/_CKXvSSCBSs?si=VAMu-rIk1oRuDZk4" rel="noopener noreferrer" target="_blank">Watch Mixus Codex Group Meeting on Youtube</a></p>
<p><span>Roland Vogl: Welcome everyone to our Codex group meeting. It is March 19th, 2026. I was just telling Elliot, our guest here, and my colleague Elaine, that we&rsquo;re in the midst of a hot phase of preparations for our FutureLaw week.</span></p>
<p><span>So if you haven&rsquo;t registered yet, you should do so. It&rsquo;s going to be an amazing event, and just an amazing group of people who have already announced their participation. So don&rsquo;t miss it. Join us for that. And today we have, as I said, Elliot Katz here. He&rsquo;s co-founder and CEO of Mixus, which is bringing agentic AI into law firms and doing so in a safe manner. And so we&rsquo;re really thrilled to have you here with us today, Elliot, and very excited to learn about what you&rsquo;ve been up to. So I&rsquo;ll turn it over to you.</span></p>
<p><span>Elliot Katz: Great, great. Thanks, Roland. Thanks so much for inviting me. I&rsquo;m honored to be speaking to everyone here today at Stanford CodeX. As Roland mentioned, I&rsquo;m the co-founder of Mixus. What we do is we provide email-based AI agents with built-in firm-level oversight to legal teams, including to multiple AmLaw 20 firms. As to my background, I&rsquo;m what I like to call a recovering attorney.</span></p>
<p><span>So I did go to Cornell Law School, and from there I went to DLA Piper, where I led their autonomous vehicle practice. And then as a sixth year, I moved to McGuireWoods as a partner and global chair of their autonomous vehicle practice. And through my experience working with my autonomous vehicle company clients and getting to ride in their vehicles, I really concluded that autonomous vehicles could not be commercially deployed at scale without some way of keeping a human in the loop when the vehicles needed assistance.</span></p>
<p><span>Then fast forward to 2017. I met my now co-founder, Shai, who you can see here, when he gave me a teleoperated ride around the block in a vehicle he was remotely driving from his living room in Palo Alto. So at that point, I left the practice of law and we started Phantom Auto, where our technology enabled humans sitting literally thousands of miles away to remotely assist or operate unmanned vehicles when they ran into issues that autonomy could not handle.</span></p>
<p><span>Now fast forward to 2024. Shai and I co-founded Mixus together with essentially the same premise, right? Which is AI can do a lot, but if the stakes are high and the work is truly of consequence, you absolutely need a human in the loop. I mean, even if AI can get you 80 to 90% of the way there, you still need humans for that 10 to 20% when the circumstances mandate that everything&mdash;and I mean everything&mdash;must be done correctly.</span></p>
<p><span>So that&rsquo;s who we are. Our DNA is human-in-the-loop, and we&rsquo;re now applying that DNA to the legal sector with Mixus agents, which again combine artificial and human intelligence to provide the level of work product that this sector requires. So the first thing I&rsquo;ll tell you, and this is based on my experience as an actual practitioner and from deploying Mixus agents to some of the top law firms in the world, is that your jobs as attorneys are safe.</span></p>
<p><span>I could probably find multiple LinkedIn posts in my feed right now that say, you know, lawyers and law firms won&rsquo;t exist come 2027 because you&rsquo;ll just talk to a chatbot. But we really believe that that is nonsense. Because for AI to be deployed at scale in the legal sector, you have to mix us&mdash;right, that&rsquo;s the name of the company&mdash;artificial intelligence and human intelligence together. Right? Because the correct answer to a contract negotiation question is not a matter of factual accuracy, right? It depends on judgment and the client&rsquo;s risk tolerance, the deal type, the counterparty&rsquo;s position, and a multitude of other factors that simply don&rsquo;t exist in the public domain. So Mixus exists not to displace attorneys but to greatly augment their brilliant legal minds.</span></p>
<p><span>So let&rsquo;s dive in. So if we can go to the next slide. Why can&rsquo;t attorneys just use fully autonomous agents for their work? First, because they&rsquo;re probabilistic, right? And no client has ever hired an attorney for them to guess the next most probable word needed in a purchase agreement in a massive M&amp;A deal, right? Clients hire attorneys for laser precision. They&rsquo;re paying them hundreds of thousands, millions of dollars for laser precision. And that&rsquo;s simply not what probabilistic AI provides.</span></p>
<p><span>Okay, number two: it&rsquo;s not enough for an agent to have end-of-one oversight, right? You need oversight at the firm level so that attorneys with different areas of expertise can review and approve when appropriate and when needed, right?</span></p>
<p><span>And third, and this cannot be overlooked, the AI tools that exist today are standalone tools, right? Attorneys need to learn a new tool and integrate it into their workflow. And that level of change management has already proven very difficult for the legal sector, right? AI has taken off for coding, for example. And part of that is because coders are highly technical, right? For lawyers, as I&rsquo;m sure many of you in the audience can appreciate, that&rsquo;s not always the case, right? As a first-year attorney, I remember working with one partner&mdash;he was a brilliant attorney, but to this day I&rsquo;m still not sure that he knew how to turn on a laptop, right? So asking someone like that to learn a new tool, learn a new UI, integrate it into their workflow&mdash;very, very difficult to do.</span></p>
<p><span>But with Mixus agents, we set out from day zero to solve all of these issues, right? Number one: we meet attorneys where they are most of their day, which is their email inbox. To use our agents&mdash;and I&rsquo;ll show you guys this in a second&mdash;you just email </span>agent@mixus.com<span> a task in natural language, the same way you would talk to an associate or a partner, right? And you can cc any of your colleagues. The agent then emails back the completed work product, and the attorneys review and approve the agent outputs.</span></p>
<p><span>So we are mimicking exactly how lawyers already work today&mdash;exactly what they&rsquo;ve now been doing for decades since email came out in the mid-&rsquo;90s&mdash;collaboratively and in natural language over email, so that we fit exactly into their workflow with no change management at all. And because we enable that firm-level attorney oversight, legal teams get the efficiency of AI agents without the risk of incorrect AI outputs making their way to their clients or to, you know, a legal brief or anything that they&rsquo;re submitting to the court. Obviously, we&rsquo;ve all seen public examples of when that&rsquo;s gone horribly wrong.</span></p>
<p><span>So now let me show you a quick demo of a few of our agents. And for the demo, I&rsquo;ll show you some of our venture financing agents, as those are near and dear to my heart as a startup founder. So let&rsquo;s start with our term sheet agent. And let me first set the scene, right? So let&rsquo;s say that Mixus gets a term sheet today from XYZ VC firm. The first thing I do as the founder of Mixus is I forward that term sheet to my VC partner, and then they probably, in all likelihood, send it to one of their associates to do a redline and an issues list, which is exactly what I want to see. That&rsquo;s the work product I need. And then the partner reviews, and I get it back a few days later. Also, maybe there&rsquo;s tax implications or stuff like that&mdash;they bring in a tax partner or whatever it is. But the whole process, soup to nuts, is a few days here.</span></p>
<p><span>If you&rsquo;re looking at the screen right now, in this example, Christian is emailing the Mixus agent the term sheet that he received, right? And the Mixus agent&mdash;the email address, you don&rsquo;t see it in this format, but it&rsquo;s </span>agent@mixus.com<span>&mdash;and he&rsquo;s emailing the term sheet. So Christian here is playing like the partner at the law firm, and he&rsquo;s also cc&rsquo;ing some of his associates. And he&rsquo;s saying redline the term sheet. So if you go down a few minutes later, he gets back an email that has everything that he would need that I, as a founder, want back from my attorneys. It has the redline, and it also has the issues list.</span></p>
<p><span>And you could, Christian, if you want to open up the redline, just to show everyone what that looks like quickly. Okay, great. Looks like a normal redline. And then go back to the email. And so you also do have the ability to click on the link here and go work directly in our web UI. What we&rsquo;ve found with our deployments thus far: attorneys really want to stay in email. So most of them do everything that they do over email, which is entirely possible. But if you&rsquo;d like a web UI, you can do that as well.</span></p>
<p><span>So go back to the email chain, Christian. So then if you go down, it&rsquo;s telling you everything that it did. It attached the documents. But then one of the associates on the chain says, &ldquo;Agent, please reduce the no-shop period from 60 days to 30 days.&rdquo; So then if you go down, Christian, here it&rsquo;s made that change. It&rsquo;s attached all the new documents. And I don&rsquo;t know if there&rsquo;s anything more after that. If you can keep going down, Christian. Yeah, maybe you can show the issues. Yeah. So here&rsquo;s the issues list that it produced. So you&rsquo;re getting everything that you need, and you&rsquo;re doing it exactly the way that firms are doing it today: collaboratively over email. Anyone can interact with the agent. You saw associates and partners interacting together and with the agent. And it&rsquo;s all in natural language. So there&rsquo;s no learning curve, right? You don&rsquo;t have to understand how to do any of this.</span></p>
<p><span>The second thing that I&rsquo;ll show is after you get the term sheet, we need a pro forma cap table. So Christian, if you could go to&mdash;yeah. So here he&rsquo;s just saying, &ldquo;Agent, create a new pro forma cap table based on the preexisting cap table that he&rsquo;s attaching and the Series A term sheet.&rdquo; And if you can go down, Christian, a few minutes later it&rsquo;s going to provide that pro forma. You can click on the link just to quickly show everyone what that looks like. Looks very nice. It&rsquo;s got the waterfall analysis, etc., which I like to look at, if you go to the left&mdash;stuff like that. So you can go back to the email and keep going down.</span></p>
<p><span>So he had&mdash;oh, I guess that&rsquo;s it for the pro forma. The last one that I&rsquo;ll show you guys is the M&amp;A docs. That&rsquo;s what you need to do after the pro forma. You already&mdash;let&rsquo;s say this company already raised a seed round, and now they&rsquo;re raising their A. So all the attorney has to do is attach the Series Seed docs and then ask for them to be updated based on the new term sheet. And that&rsquo;s exactly what you&rsquo;re going to get here.</span></p>
<p><span>And then if you can keep going down, Christian. He did cc one of his associates. So one of the associates chimes in and says, &ldquo;Hey, I looked at everything, and everything looks good.&rdquo;</span></p>
<p><span>So that is a very high-level, quick overview of Mixus. We&rsquo;re going to take some questions in a second here. But if anyone listening is interested in learning more or trialing our agents, just reach out to me: </span><b>elliot@mixus.ai</b><span>. And because our agents are email-based, there&rsquo;s no complex onboarding or installation required. We can set you up in minutes. And because we&rsquo;re mimicking exactly how firms are doing this today, you know, we don&rsquo;t need any elongated onboarding or anything like that. Attorneys just know how to use it pretty much instantly.</span></p>
<p><span>And last thing I&rsquo;ll say is if you&rsquo;re in the audience right now thinking, you know, &ldquo;Geez, we brought in XYZ AI tool into our org or into our firm, but our attorneys aren&rsquo;t really utilizing that tool,&rdquo; we could be a perfect fit for you. Because our current customers all had or have licenses for other tools as well. But when everything comes down to usability, right&mdash;what AI tools will attorneys actually use day to day and integrate into their core workflow?&mdash;the firms that we&rsquo;re working with today have found that our approach is really unparalleled in the market on that specific front.</span></p>
<p><span>So with that, let me know what questions we can answer, and we&rsquo;ll move from there.</span></p>
<p><span>Roland Vogl:</span><span> Yeah. So there&rsquo;s a couple of questions coming in the chat, but I have, before we go to those, a couple of questions. So one is: how much setup time is involved for each firm? Presumably, you know, when you do those automatic&mdash;when your agents do those redlines&mdash;you know, they must be trained to know, you know, whatever&mdash;you know, how, what&rsquo;s the, you know, the market for this or that, right? And so that must be based on the knowledge of the firm, right, or the human lawyers of the firm. How do you handle this process? And&mdash;great question&mdash;and how do you have&mdash;you talk about agents, you know, that&rsquo;s like there&rsquo;s one email for agents, right? But do you have agents for different verticals, you know, there&rsquo;s like, yeah, VC practice and whatever environmental compliance practice&mdash;at least separate agents versus all like&mdash;</span></p>
<p><span>Elliot Katz:</span><span> Yeah. Great question. So there&rsquo;s really two questions in there. As to the first: many of our agents do not require a playbook. But some of our agents either, you know, do require a playbook, or the outputs that you&rsquo;ll receive from the agent will be more tailored to your preferences if you do have a playbook.</span></p>
<p><span>Now, what we consistently heard from our customers, especially early on, is, &ldquo;Listen, even if we have to make an upfront investment of time of a couple of hours of developing our own playbooks, the juice is potentially so worth the squeeze, because then we can use the agents moving forward.&rdquo; And it&rsquo;s not just a one-time, essentially, cost on our time.</span></p>
<p><span>But what we created was an automatic playbook builder. So now all you have to do to create a playbook is email in exemplars. Let&rsquo;s say it was the first agent that I showed, the term sheet agent, right? You email in&mdash;attach a few exemplars of term sheets that you&rsquo;ve done in the past or that you&rsquo;ve redlined, and the system will ingest that. It will automatically create the playbook for you so that you have the foundation. And then you can just go in and make any edits that you want to fit your specific preferences.</span></p>
<p><span>And I think that&rsquo;s what we&rsquo;re showing right now on the screen, is the ability to make those playbooks. And after you make the playbook, the playbooks can also automatically update based on your preferences. So as you go through and do more work with the system, it understands your preferences and things that you changed along the way, and it will check in with you and say, &ldquo;Hey, is this something that&rsquo;s a one-off or a standard that you&rsquo;d like to apply to the playbook generally?&rdquo;</span></p>
<p><span>So that&rsquo;s how we handle that piece. As to your second question, Roland, which was about which agents do we have deployed&mdash;so we have probably deployed like 50 agents at this point, both purely legal agents and also other agents that are not necessarily purely legal, right? For one firm that we&rsquo;re working with, we are deploying&mdash;we&rsquo;ve deployed a task management agent that basically serves as a project manager across all of your matters. It&rsquo;s entirely over email. You can talk to it like a human. So it&rsquo;s an agent that keeps the train on the tracks when associates are working with six different partners and five different matters for each. It can coordinate amongst those groups seamlessly, 100% over email. So again, no tool switching, no change management.</span></p>
<p><span>But we deploy agents that are common in each practice. And then another thing that we do with our customers is we will build and deploy custom-built agents. So not only will we optimize current agents to tailor them to fit their practices specifically, but if they have a new workflow where they would find a lot of value because their firm does a lot of XYZ work, we will create those agents for them as well.</span></p>
<p><span>Roland:</span><span> Got it. So Benjamin raises a good question, too, which is, you know, going to the point that, you know, we need human oversight, but how do we make sure that humans are not just rubber-stamping the AI outputs, right? Like, how hard is it to actually, you know, really go into the outputs of the AI and review, you know, the accuracy of the output? And so we&rsquo;re not sort of like in the ballpark, &ldquo;Okay, let it just go out like that.&rdquo; So what&rsquo;s&mdash;what level of&mdash;what is oversight mean? And how do we make sure that it&rsquo;s not just people rubber-stamping the AI?</span></p>
<p><span>Elliot:</span><span> Yeah, absolutely. Great question. So first of all, to kind of the middle part or second part of your question: very easy to review the outputs, right? These are attorneys where it&rsquo;s their subject matter expertise, right? So you&rsquo;re going in, you&rsquo;re reviewing a redline, you&rsquo;re reviewing a new document that the agent put forth. You have all the facts, you have everything in one chain if you&rsquo;re on email, or in the chat if you&rsquo;re on the web UI.</span></p>
<p><span>As to the second point, there is no kind of blind rubber-stamping here, because at the end of the day, you do have a human who is on record of being responsible for checking this, right? In the same way that my VC partner would send an issues list to an associate today and say, &ldquo;Review this and make sure everything&rsquo;s accurate and all that,&rdquo; that&rsquo;s what&rsquo;s happening when a human reviewer is signing off here as well. And there is a record of who verified, right?</span></p>
<p><span>So some of the firms that we&rsquo;re working with&mdash;they&rsquo;ve created rules, right, where AI outputs cannot go out in work product to a client before at least one partner signs off, or whatever the rule may be. And you have a record, an email, of someone saying, &ldquo;I verified that this looks good, and we can proceed.&rdquo; So it&rsquo;s the same kind of social pressure, for lack of a better term, as to why you would get the same outcome that you would get today.</span></p>
<p><span>Roland:</span><span> So like&mdash;that&rsquo;s good. Yeah. So Jason has a question. Sorry, Benjamin, did you want to add something on that?</span></p>
<p><span>Benjamin:</span><span> Yeah, I&rsquo;d like to raise&mdash;like, there have been federal judges that have had their interns or their clerks, you know, do things, and they just rubber-stamp it. And even federal judges who&rsquo;ve had AI stuff that has been rubber-stamped. And while they didn&rsquo;t literally put their signature on it, I think the meaningfulness of a review is to verify that the person who actually is reviewing it understands what is going on in some sort of interactive way. And I know that you have a limited managed work budget. And when you get too much work, you just sort of rubber-stamp things. And so how do you sort of force them to slow down and put like a roadblock to make sure that they tell the system that they understand why?</span></p>
<p><span>Elliot:</span><span> Yeah. I mean, I think I would answer just similarly to kind of what I said before, in the sense that no different than if you give an associate something to review before it goes out to a client today&mdash;they know that they&rsquo;re kind of, their butt&rsquo;s on the line, for lack of a better term. That&rsquo;s similar to the way our system works, right? There&rsquo;s still the person who is the front line making sure that everything is in place before it goes over to the client, and all that is auditable. There&rsquo;s a record within email or using the chat as to who, you know, was doing those checks.</span></p>
<p><span>Roland:</span><span> Yeah. I guess it&rsquo;s also a, you know, a question of like, you know, continuing to sort of instill a sensitivity in people who use AI in professional services and elsewhere, you know, about, you know, that it&rsquo;s not, you know, it&rsquo;s not perfect and it may hallucinate and so on. And then, you know, and understanding that then, you know, their reputation is on the line if they don&rsquo;t, you know, provide meaningful review. And so, yeah, I think it&rsquo;s a little unclear now, but I think it will sort of become clearer in the future as to what level of control different humans will be able to, you know, display over AI. But yeah, it&rsquo;s a really good question, Benjamin. And Jason had a question on&mdash;I could just ask about client privilege.</span></p>
<p><span>Jason:</span><span> Yeah, yeah. So obviously attorneys are using Harvey AI and Legora and, you know, Westlaw and all the other stuff. But, you know, in practice, what are you hearing as far as any pushback of using an LLM on the backend? It&rsquo;s putting, you know, client data into the LLM. And yes, I&rsquo;m sure that the APIs have, you know, good terms of service, but still you&rsquo;re getting&mdash;at this point, what kind of concerns are attorneys or law firms at the corporate level saying about attorney-client privilege? Because like the New York Times versus OpenAI case back in last May has still not been, you know, fleshed out where it&rsquo;s going to land. And people are kind of wondering about that.</span></p>
<p><span>Elliot:</span><span> Yeah, yeah. So I mean, first of all, on the security side, especially for the customers that we work with, we go through, you know, very lengthy security reviews. We have all the things that these big law firms would expect, right? We&rsquo;re SOC 2, we have all the ISOs that we need in place, etc. Also, with our model provider, we have a zero data retention agreement in place. So I think we&rsquo;re buttoned up on that side in the eyes of our customers.</span></p>
<p><span>Going to your question about privilege, you know, my opinion&mdash;and this is, you know, based on many conversations that I&rsquo;ve had with our customers&mdash;is that this is basically settled law, right? In the sense that law firms have been using vendors for years, right, that do document review and other things. And those are considered part of the privilege. So, you know, we haven&rsquo;t run into any issues there yet. But we&rsquo;d love to hear if you have, you know, kind of a different tack or different thoughts on the subject.</span></p>
<p><span>Jason:</span><span> Well, you know, it&rsquo;s perception, you know, on this matter, right? And there are some, you know, folks that I&rsquo;ve worked with in some law firms that feel&mdash;but it&rsquo;s perception. And you have to make that case and say, &ldquo;Well, everybody else is doing that.&rdquo; And you&rsquo;re like, &ldquo;Well, we&rsquo;re not everybody else,&rdquo; right? So I was just curious what you&rsquo;ve seen, you know, in the trenches as you work with some of them, because some of them can be very, very conservative about that point.</span></p>
<p><span>Elliot:</span><span> Oh yeah, yeah. No, no, for sure. Like, email has been established in the industry very clearly. And if you have a cloud provider, you know, that&rsquo;s a branded cloud&mdash;like, you&rsquo;ve got your decades there. But LLMs in particular have, you know, some aspects to them as far as, you know, bioterrorism and other things that they&rsquo;ve got people watching, a sampling of these things, and that&rsquo;s throwing up other questions anyway we can offer&mdash;</span></p>
<p><span>Jason:</span><span> No, no, I think that, yeah, I think it&rsquo;s&mdash;listen, this is a very important topic. And to your point about, you know, cloud providers and all that&mdash;I mean, we have talked with major law firms that have not migrated to the cloud, right? They are still completely on-prem, right? So these are very conservative, you know, security-first organizations. And we molded our company around that expectation. I mean, I came from this world. So I mean, that&rsquo;s probably the thing that we&rsquo;ve invested from a time perspective, you know, and dollar-wise, just a huge amount of time and money into security.</span></p>
<p><span>Jason:</span><span> Yeah, it&rsquo;s&mdash;oh, you&rsquo;ve done a nice job. It looks really good.</span></p>
<p><span>Elliot:</span><span> Thank you. Thank you, I appreciate it.</span></p>
<p><span>Roland:</span><span> Yeah. There&rsquo;s a couple more questions in the chat. I&rsquo;m not sure we can get to all of this. I know Dasa has mentioned a little bit of his work with the agencies he&rsquo;s been creating. So, Dasa, you want to elaborate?</span></p>
<p><span>Dasa:</span><span> Yeah, sure. Thank you, Roland. And yeah, I agree&mdash;great presentation. I was just saying I&rsquo;ve been spending a lot of work with clients lately developing agents to do reviews and red-team before, basically, like the attorney or the business person even sees the draft. Do you have flows that basically include some sort of review or red-team-y loop for that type of revision before, you know, basically as a gate before it gets to a next step in a process?</span></p>
<p><span>Elliot:</span><span> Great question. Christian, do you want to chime in on this one? I know it&rsquo;s a topic near and dear to your heart.</span></p>
<p><span>Christian:</span><span> Yeah. So we do have a way that you can define different steps in a process, so you can decide, you know, very specific processes that you have. I can show you one example of that actually over here. So if you&rsquo;re following one specific process very regularly, one thing you can do is say, &ldquo;Save this workflow as an agent.&rdquo; And then whenever a new email comes in, you can have that specific agent run. So you can also just create these custom workflows just by talking to the agent. So yeah, that&rsquo;s possible as well.</span></p>
<p><span>Dasa:</span><span> Okay, that&rsquo;s great. Thanks.</span></p>
<p><span>Roland:</span><span> And look, Roland, I&rsquo;m wearing my CodeX hat, getting ready for FutureLaw.</span></p>
<p><span>Elliot:</span><span> Oh, I appreciate it, yes.</span></p>
<p><span>Roland:</span><span> Yeah, getting into&mdash;you&rsquo;re getting into the spirit. I love it.</span></p>
<p><span>Elliot:</span><span> Right, super.</span></p>
<p><span>Roland:</span><span> Okay, so Matthew, yes, one comment&mdash;thinks that a tool like yours would free up a lot of time since it&rsquo;s doing a huge chunk of the first round of work. Yeah. This just goes to the concern around, &ldquo;Well, is somebody just going to rubber-stamp it?&rdquo; I think we&rsquo;re going to have way more time than we ever had ever before when these AI tools are doing a huge amount of the work.</span></p>
<p><span>Elliot:</span><span> Yeah. I couldn&rsquo;t agree more with that statement. We&rsquo;re already seeing it with our customers. You know, some of the feedback that we&rsquo;re getting is, &ldquo;I&rsquo;m as busy as, you know, as I was before we were using the tool. I&rsquo;m just doing a lot more work a lot more efficiently for a lot more clients,&rdquo; right? But I think you are going to see that this role of essentially managing agent outputs, verifying the agent outputs, is going to be&mdash;not just in the legal sector, but more broadly&mdash;a big part of how work gets done moving forward.</span></p>
<p><span>Roland:</span><span> Okay. And then Mavi asks a question quickly on the sort of backend security of the LLM model. Yeah, it&rsquo;s the sort of multi-modal architecture&mdash;is the sort of oversight really mainly carried out by the humans in the loop?</span></p>
<p><span>Elliot:</span><span> So Christian, you want to jump in on that one too?</span></p>
<p><span>Christian:</span><span> We mainly use Claude. And, you know, we have a zero data retention policy with them, as Elliot mentioned. So that&rsquo;s the sort of base model that we use. So we have different ones that you can choose from. So we just keep sort of following up on, like, okay, whenever there&rsquo;s a new model evolution, right&mdash;so right now it&rsquo;s Opus, that&rsquo;s the latest one. That&rsquo;s the one we&rsquo;re using. So we always use the latest and greatest model from Claude, basically. So I mean, that&rsquo;s in terms of the underlying model. So I just want to understand the question on the human side&mdash;like, what was that exactly?</span></p>
<p><span>Question:</span><span> Is there a sovereign layer to review output from a software side, or is it only human-in-the-loop, basically, right?</span></p>
<p><span>Christian:</span><span> Yeah. So what I could say there, like, we have deterministic gates. So until someone approves one step, it&rsquo;s not going to continue on to the next step. And that&rsquo;s a deterministic thing you can configure. So you can also do that within the UI, actually. So if you go over here and you want to create a new agent, that is possible. Then you can create that here, and then you can see you can define these different steps. All of this is possible via email as well. So you can just tell the agent to create these different steps for a new agent or workflow that you have. And then you can say, &ldquo;Require verification.&rdquo; And then you can define the users that you want to verify. So in this step, you could say, &ldquo;Okay, I want this, you know, user to verify step one before it continues on to step two.&rdquo; And that&rsquo;s going to be a deterministic approval that has to take place before it goes on to the next step, right? So that&rsquo;s, you know, similar to what was mentioned before on these custom workflows. That&rsquo;s how we can support that as well.</span></p>
<p><span>Roland:</span><span> Right. Well, we&rsquo;re already a little bit over time. So we have to close here, unfortunately. But what would be a good way for folks to reach out with any follow-up questions? Do you think you could put your email address into the chat, perhaps?</span></p>
<p><span>Elliot:</span><span> Yeah, absolutely. It would be great. And so the easiest way is just email, or you can find me on LinkedIn as well. And look forward to chatting with anyone that wants to learn more.</span></p>
<p><span>Roland:</span><span> Super. Love it. Thank you so much, Elliot and Christian. It&rsquo;s been a great presentation. It&rsquo;s very cool. It&rsquo;s like, you know, kind of like I feel like I&rsquo;ve seen the future. And so, so amazing. Thank you for sharing with this group here. And yeah, we look forward to tracking your progress.</span></p>
<p><span>Elliot:</span><span> Okay. Awesome. Thank you guys so much. Really appreciate it, Roland.</span></p>]]></content>
	<updated>2026-03-19T22:08:49+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-03-19T22:08:49+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="codex"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-03-23:/283390</id>
	<link href="https://law.stanford.edu/2026/03/23/paraguay-computational-antitrust/" rel="alternate" type="text/html"/>
	<title type="html">The Paraguayan Competition Authority Joins the Stanford Computational Antitrust Project</title>
	<summary type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces that the Comisi&oacute;n Nacional de la Competencia ...</p>]]></summary>
	<content type="html"><![CDATA[<p>The Stanford Computational Antitrust Project announces that the Comisi&oacute;n Nacional de la Competencia (CONACOM) of Paraguay has joined its network of partner agencies.</p>
<p>CONACOM is the public body entrusted with the application of Paraguay&rsquo;s competition law. Since its establishment, the agency has contributed to the gradual consolidation of competitive conditions across key sectors of the Paraguayan economy. Its activity reflects an institutional trajectory marked by increasing engagement with both domestic enforcement priorities and international cooperation. This evolution is significant. In jurisdictions where competition frameworks are relatively recent, antitrust agencies play a structuring role in shaping market expectations and business conduct. CONACOM&rsquo;s work illustrates how enforcement can operate as a dynamic force.</p>
<p>The partnership with the Stanford Computational Antitrust Project builds on this trajectory. It creates a platform to examine how computational methods can complement existing analytical tools and support evidence-based enforcement. Thibault Schrepel, founder of the Stanford Computational Antitrust Project, stated:</p>
<p>&ldquo;We warmly welcome CONACOM to the project. Paraguay offers a valuable context to study how computational approaches can support competition agencies operating in fast-evolving market environments.&rdquo;</p>
<p>The collaboration will focus on methodological exchanges and applied research. It reflects a joint commitment to strengthening analytical capacity and refining the tools used to evaluate competition.</p>]]></content>
	<updated>2026-03-23T08:00:54+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-03-23T08:00:54+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-03-18:/282976</id>
	<link href="https://law.stanford.edu/2026/03/18/moroccan-competition-council-computational-antitrust/" rel="alternate" type="text/html"/>
	<title type="html">Moroccan Competition Council Joins Stanford Computational Antitrust Project</title>
	<summary type="html"><![CDATA[<p>Morocco&rsquo;s Competition Council (Conseil de la Concurrence) is joining Stanford computational antitru...</p>]]></summary>
	<content type="html"><![CDATA[<p><strong></strong> Morocco&rsquo;s Competition Council (<em>Conseil de la Concurrence</em>) is joining Stanford computational antitrust project  which brings the total number of affiliated competition agencies to over 80 worldwide.</p>
<p>The Stanford Computational Antitrust project, founded and led by Thibault Schrepel (Vrije Universiteit Amsterdam / Stanford CodeX Center for Legal Informatics), is the world&rsquo;s leading initiative at the intersection of competition law and computational methods. It brings together competition agencies and academics to develop empirical and technological tools for modern antitrust enforcement. The project receives no private funding.</p>
<p>Morocco&rsquo;s Competition Council is an independent constitutional institution responsible for ensuring transparency and fairness in economic relations, including the analysis of anti-competitive practices, merger control, and market regulation. Fully operational since 2018, the Council has established itself as one of Africa&rsquo;s most active competition agencies, with a track record of merger decisions and antitrust enforcement that spans digital markets and traditional sectors alike.</p>
<p>&ldquo;We are delighted to welcome the Moroccan Competition Council to the network,&rdquo; said Thibault Schrepel. &ldquo;Their expertise and perspective will strengthen the project&rsquo;s African and Mediterranean representation. Their enforcement experience is directly relevant to the computational challenges we are working to address.&rdquo;</p>
<p>The affiliation deepens the project&rsquo;s engagement across Africa, where competition authorities are increasingly confronting the enforcement challenges raised by digital markets.</p>
<p><strong>About the Stanford Computational Antitrust Project</strong> The Stanford Computational Antitrust project brings together over 80 competition agencies globally to advance empirical and computational approaches to antitrust enforcement. It operates under the Stanford CodeX Center for Legal Informatics and accepts no private funding. More information: <a href="http://www.computationalantitrust.com/" rel="noopener noreferrer" target="_blank">www.computationalantitrust.com</a>.</p>
<p><strong>About Morocco&rsquo;s Competition Council</strong> The <em>Conseil de la Concurrence</em> is Morocco&rsquo;s independent competition agency. It is responsible for ensuring free and fair competition, regulating anti-competitive practices, and advising government and parliament on competition matters.</p>]]></content>
	<updated>2026-03-18T08:01:23+00:00</updated>
	<author><name>CodeX</name></author>
	<source>
		<id>https://law.stanford.edu/blog/codex/</id>
		<link rel="self" href="https://law.stanford.edu/blog/codex/"/>
		<updated>2026-03-18T08:01:23+00:00</updated>
		<title>CodeX - Stanford Law School</title></source>

	<category term="computational antitrust"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-02-26:/281030</id>
	<link href="https://law.stanford.edu/2026/02/26/reproductive-due-process-procedural-justice-in-an-era-of-arbitrariness/" rel="alternate" type="text/html"/>
	<title type="html">Reproductive Due Process: Procedural Justice in an Era of Arbitrariness</title>
	<summary type="html"><![CDATA[<p>I. Introduction: The Invisible Constraint
The rapid evolution of reproductive technologies has force...</p>]]></summary>
	<content type="html"><![CDATA[<h3><strong>I. Introduction: The Invisible Constraint</strong></h3>
<p>The rapid evolution of reproductive technologies has forced courts and legislatures to confront questions that once seemed purely theoretical. In vitro fertilization (IVF) has become routine medical practice, while emerging techniques such as in vitro gametogenesis (IVG)&mdash;an experimental method of generating eggs or sperm from ordinary somatic cells such as skin cells&mdash;suggest that future reproduction may involve the large-scale creation and management of embryos.[1] Although such developments remain scientifically and politically contingent, advances in stem-cell-derived gametes and genomic sequencing could expand the scale of embryo creation and selection, thereby intensifying the regulatory and legal stakes of reproductive governance. Even at a preclinical stage, IVG suggests that reproduction may increasingly unfold within laboratory-based and institutionally structured frameworks.[2]</p>
<p>Since <em>Dobbs v. Jackson Women&rsquo;s Health Organization</em>,[3] legal debate has largely focused on whether reproductive autonomy remains protected as a substantive constitutional right.[4] This blog asks a different question: when the state restructures reproductive governance&mdash;by redefining embryos, prohibiting their disposition, or altering regulatory frameworks&mdash;what procedural obligations follow?</p>
<p>Substantive due process asks whether certain forms of state regulation impermissibly infringe constitutionally protected liberty interests; procedural due process concerns how it must regulate when doing so.[5] Even where no fundamental right is recognized, the Constitution requires fair procedures when the state deprives individuals of recognized liberty or property interests.[6] Research on procedural justice further suggests that the legitimacy of the state depends not only on outcomes, but on the fairness and predictability of decision-making processes.[7] In the assisted reproductive technologies context, the erosion of procedural safeguards risks replacing constitutional order with government arbitrariness.</p>
<h3><strong>II. The Vanishing Question of Procedure</strong></h3>
<p>Since <em>Dobbs v. Jackson Women&rsquo;s Health Organization</em> repudiated the constitutional right to abortion, debates over reproduction have largely been framed in binary terms: either reproductive autonomy is a fundamental right, or it is not.[8] What has followed is not a careful recalibration of how states regulate reproduction, but a proliferation of blunt legal interventions. Recent reporting by organizations such as the Guttmacher Institute indicates that multiple states have enacted or proposed legislation recognizing forms of fetal or embryonic personhood, often with significant implications for assisted reproductive technologies.[9]</p>
<p>Notably absent from these developments is sustained attention to procedural due process, the requirement that when the government deprives individuals of liberty or property, it must do so through fair and predictable procedures.[10] A skeptic might argue that if no substantive right exists, no procedural protection is triggered. This reasoning overlooks a central feature of due process doctrine. Procedural due process does not protect &ldquo;fundamental rights&rdquo; alone; it protects any &ldquo;liberty&rdquo; or &ldquo;property&rdquo; interest created by existing law, including interests shaped by state-created regulatory frameworks, contractual arrangements, or settled practices.[11] As the Supreme Court explained in <em>Perry v. Sindermann</em>, constitutionally protected property interests, for instance, may arise from &ldquo;mutually explicit understandings,&rdquo; even where no formal entitlement is guaranteed by statute.[12]</p>
<p>This blog does not contend that participation in assisted reproduction creates a freestanding constitutional right. Rather, it argues that once the state affirmatively structures, licenses, and regulates a reproductive medical framework, it assumes procedural obligations when altering that framework in ways that arbitrarily infringe settled reliance interests. Patients who have invested genetic material, significant financial resources, and years of medical reliance on IVF may have reliance interests analogous to the mutually explicit understandings recognized in procedural due process doctrine.</p>
<h3><strong>III. The Alabama Example</strong></h3>
<p>In most areas of law, decisions with profound personal consequences&mdash;termination of parental rights, involuntary commitment, or denial of public benefits&mdash;trigger procedural safeguards designed to ensure fairness and predictability.[13] The regulation of assisted reproductive technologies, however, increasingly operates outside this framework.</p>
<p>Critics may respond that general legislation does not require individualized hearings.[14] Under cases such as <em>Bi-Metallic Investment Co. v. State Board of </em>Equalization, 239 U.S. 441 (1915), when a rule applies to the public, due process does not mandate case-by-case adjudication.[15] That principle is well established. But the concern here is not the absence of individualized hearings; it is the absence of legitimate, transitional governance when legal rules are abruptly redefined in ways that disrupt settled reliance interests.</p>
<p>When a legislature or court suddenly reclassifies embryos, the deprivation of genetic material and decisional authority may follow automatically, without notice, safe-harbor periods, or prospective application. Procedural justice research suggests that individuals are more likely to accept regulatory outcomes when decision-making processes are perceived as fair, transparent, and respectful.[16] Abrupt legal shifts without transitional mechanisms undermine not only expectations but institutional legitimacy.</p>
<p>The Alabama Supreme Court&rsquo;s 2024 decision in <em>LePage v. Center for Reproductive Medicine </em>exemplifies this dynamic.[17] The court&rsquo;s interpretation of the state&rsquo;s wrongful death statute effectively reclassified embryos in a manner that significantly altered the legal framework within which IVF patients had structured their reproductive decisions, without providing a procedural mechanism to mitigate the consequences of that shift.</p>
<p>No notice period or prospective application was offered.[18] Had transitional safeguards been provided&mdash;such as prospective limitation of liability, grandfathering provisions, or time to transfer embryos&mdash;the regulatory change might have avoided the appearance of judicial arbitrariness. Instead, deprivation operated immediately and categorically.</p>
<p>As articulated in <em>Mathews v. Eldridge</em>, 424 U.S. 319 (1976)&mdash;a case involving the termination of Social Security disability benefits&mdash;due process analysis evaluates the private interest at stake, the risk of erroneous deprivation, and the probable value of additional procedural safeguards.[19] Although <em>Mathews</em> arose in an administrative benefits context rather than general legislation, its framework highlights a broader constitutional concern: when legal change creates a significant risk of unjustified deprivation of structured private interests, the availability of procedural mitigation mechanisms becomes normatively and institutionally consequential.</p>
<h3><strong>IV. Why IVG Raises the Stakes</strong></h3>
<p>Emerging technologies such as IVG will only amplify these procedural deficits. IVG would enable the creation of large numbers of embryos from somatic cells, increasing the frequency and complexity of decisions about storage, testing, and disposition. In some cases, abrupt legal reclassification could leave patients without access to what may be their only medically feasible pathway to genetically related parenthood or could render years of reproductive planning legally precarious. As reproduction becomes more regulated through licensing regimes, statutory definitions, insurance mandates, hospital oversight, and potential embryo registries, the consequences of abrupt legal reclassification by courts or legislatures grow more significant.</p>
<p>As reproductive technology governance becomes more structurally regulated, its insulation from individualized procedural protection becomes more consequential. When complex regulatory systems operate without mechanisms to manage reliance or provide transitional safeguards, the risk of systemic arbitrariness increases&mdash;not because of case-specific misjudgment, but because legal change leaves no room for mitigation.</p>
<p>Without mechanisms to surface contradictions in policy&mdash;such as promoting childbirth while chilling the technologies that enable it&mdash;the law risks becoming not only restrictive but internally incoherent. IVG does not simply expand scientific possibilities; it intensifies the need for governance structures that account for reliance, predictability, and the cumulative effects of regulatory change.</p>
<h3><strong>V. Conclusion: </strong><strong>Procedural Legitimacy and Reproductive Governance</strong></h3>
<p>Reframing the regulation of reproductive technologies as a procedural due process problem does not require resurrecting <em>Roe</em>. It requires only recognition that even where the state may regulate reproduction, the legitimacy of that regulation depends on how change is implemented. Even where regulatory authority shifts from administrative agencies to legislatures or courts, the underlying demand for procedural fairness does not disappear; it becomes more difficult to enforce and more consequential when absent. Procedural safeguards demand transparency, neutrality, and meaningful opportunities for affected parties to anticipate and respond to regulatory shifts&mdash;features that procedural justice research identifies as central to legal legitimacy. They obligate states to justify not only what they regulate, but how regulatory change is structured and whom it disrupts.</p>
<p>When these safeguards disappear, reproductive governance risks sliding from constitutional order toward arbitrary power. The erosion of procedural norms normalizes a vision of reproduction as an administrative permission rather than a domain structured by reasoned and predictable legal processes. Even where substantive reproductive rights are contested, the durability and legitimacy of reproductive regulation depend on procedures that respect reliance, mitigate abrupt disruption, and constrain arbitrariness.</p>
<p>Reproductive technology governance without procedural fairness does not simply narrow autonomy; it undermines the constitutional commitment to law as a system of reasoned and accountable decision-making.</p>
<h3><strong>References</strong></h3>
<p>[1] See Nat&rsquo;l Acads. of Scis., Eng&rsquo;g &amp; Med., <em>Heritable Human Genome Editing</em> 89&ndash;92 (2020).</p>
<p>[2] See Henry T. Greely, <em>The End of Sex and the Future of Human Reproduction</em> 1&ndash;20, 120&ndash;50 (Harvard Univ. Press 2016).</p>
<p>[3]<em> Dobbs v. Jackson Women&rsquo;s Health Org.</em>, 597 U.S. 215 (2022).</p>
<p>[4] See, e.g., Elizabeth Price Foley, <em>Dobbs and the Future of Substantive Liberty</em>, 64 Santa Clara L. Rev. 159 (2024).</p>
<p>[5] See, e.g., Erwin Chemerinsky, Constitutional Law: Principles and Policies &sect; 10.1 (6th ed. 2019).</p>
<p>[6] <em>Board of Regents v. Roth</em>, 408 U.S. 564, 569&ndash;70 (1972); <em>Mathews v. Eldridge</em>, 424 U.S. 319, 332&ndash;35 (1976).</p>
<p>[7] Tom R. Tyler, <em>Why People Obey the Law</em> (1990).</p>
<p>[8] <em>Dobbs v. Jackson Women&rsquo;s Health Org.,</em> 597 U.S. 215 (2022); see, e.g., Elizabeth Price Foley, <em>Dobbs and the Future of Substantive Liberty</em>, 64 Santa Clara L. Rev. 159, 181 (2024).</p>
<p>[9] See Guttmacher Inst., <em>State Policy Trends 2025: Full-Year Analysis</em> (Feb. 4, 2026), <a href="https://www.guttmacher.org/2025/12/state-policy-trends-2025-full-year-analysis" rel="noopener noreferrer" target="_blank">https://www.guttmacher.org/2025/12/state-policy-trends-2025-full-year-analysis</a>; Guttmacher Inst., <em>State Policy Trends: Midyear Analysis</em> (June 16, 2025), <a href="https://www.guttmacher.org/2025/06/state-policy-trends-midyear-analysis" rel="noopener noreferrer" target="_blank">https://www.guttmacher.org/2025/06/state-policy-trends-midyear-analysis</a>; Guttmacher Inst., <em>First Quarter 2024 State Policy Trends</em> (May 8, 2024), <a href="https://www.guttmacher.org/2024/05/first-quarter-2024-state-policy-trends" rel="noopener noreferrer" target="_blank">https://www.guttmacher.org/2024/05/first-quarter-2024-state-policy-trends</a>.</p>
<p>[10] U.S. Const. amend. XIV, &sect; 1; <em>Mathews v. Eldridge</em>, 424 U.S. 319, 332&ndash;35 (1976).</p>
<p>[11] See <em>Board of Regents v. Roth</em>, 408 U.S. 564, 569&ndash;70 (1972); <em>Perry v. Sindermann</em>, 408 U.S. 593, 601&ndash;02 (1972).</p>
<p>[12] See <em>Perry v. Sindermann</em>, 408 U.S. 593, 601 (1972).</p>
<p>[13] <em>Santosky v. Kramer</em>, 455 U.S. 745, 753&ndash;54 (1982); <em>Goldberg v. Kelly</em>, 397 U.S. 254, 267&ndash;71 (1970).</p>
<p>[14] <em>Bi-Metallic Inv. Co. v. State Bd. of Equalization</em>, 239 U.S. 441 (1915).</p>
<p>[15] See <em>Bi-Metallic Inv. Co. v. State Bd. of Equalization</em>, 239 U.S. 441, 445 (1915).</p>
<p>[16] Tom R. Tyler, <em>What Is Procedural Justice?</em>, 22 Law &amp; Soc&rsquo;y Rev. 103 (1988).</p>
<p>[17] <em>LePage v. Ctr. for Reprod. Med</em>., P.C., 2024 WL 1161240 (Ala. Feb. 16, 2024).</p>
<p>[18] The Alabama Supreme Court&rsquo;s 2024 decision in <em>LePage v. Center for Reproductive Medicine</em>, No. SC-2022-0579 (Ala. Feb. 16, 2024), exemplifies this dynamic.</p>
<p>[19] <em>Mathews v. Eldridge</em>, 424 U.S. 319, 335 (1976).</p>]]></content>
	<updated>2026-02-26T15:55:38+00:00</updated>
	<author><name>Law and Biosciences Blog</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-02-26T15:55:38+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>

	<category term="assisted reproductive technology"/>

	<category term="constitutional law"/>

	<category term="in vitro gametogenesis"/>

	<category term="legal legitimacy"/>

	<category term="medicine"/>

	<category term="procedural due process"/>

	<category term="procedural justice"/>

	<category term="reproductive governance"/>


</entry>

<entry>
	<id>tag:vifa-recht.de,2026-02-13:/279887</id>
	<link href="https://law.stanford.edu/2026/02/13/neuroimaging-evidence-in-criminal-cases/" rel="alternate" type="text/html"/>
	<title type="html">Neuroimaging Evidence in Criminal Cases</title>
	<summary type="html"><![CDATA[<p>Imagine you&rsquo;re a juror in a murder trial. The defense attorney wheels in a large monitor displ...</p>]]></summary>
	<content type="html"><![CDATA[<p>Imagine you&rsquo;re a juror in a murder trial. The defense attorney wheels in a large monitor displaying colorful brain scans of the defendant. An expert witness points to areas highlighted in blue and red, explaining that these images show abnormalities consistent with schizophrenia. The attorney argues that these scans prove the defendant couldn&rsquo;t tell right from wrong when he committed the crime. As you look at the images, you can&rsquo;t help but notice how scientific, authoritative, and compelling they appear. After all, you&rsquo;re looking directly at their brain.</p>
<p>But will you or any other juror make the &ldquo;right&rdquo; call when faced with information they may not fully understand?</p>
<h3><strong>Actus Reus and Mens Rea</strong></h3>
<p>Before diving into brain scans, it&rsquo;s important to understand two fundamental principles that typically determine criminal liability in the United States: <em>actus reus</em> and <em>mens rea</em>.</p>
<p><em>Actus reus</em> (Latin for &ldquo;guilty act&rdquo;) refers to the physical act of committing a crime. This is usually the more straightforward element to prove, because it is typically based on objective action, such as pulling the trigger, taking property, or striking the victim.[1]</p>
<p><em>Mens rea</em> (Latin for &ldquo;guilty mind&rdquo;) refers to the mental state or intent behind the act. This is the harder element to prove. It often looks at considerations such as whether the defendant intended to act or whether it was an unfortunate accident, and whether they knew or should have known their conduct was wrong.[2] Different crimes require different levels of intent. Murder typically requires intent to kill, while manslaughter might involve recklessness rather than specific intent.[3]</p>
<p>Both elements must typically be present for someone to be found guilty of a crime. The state can&rsquo;t convict someone of first-degree murder simply because they caused a death; the prosecution must also adequately prove they had the requisite mental state.</p>
<p>Attorneys have started using neuroimaging as evidence to argue that abnormal brain scans demonstrate that the killer lacked the mental capacity to form this necessary intent, or that they couldn&rsquo;t distinguish right from wrong due to mental illness. In essence, lawyers are trying to use neuroscience to prove their client lacked <em>mens rea</em> for a given criminal charge.[4]</p>
<h3><strong>How Courts Decide Whether to Admit Brain Scans as Evidence</strong></h3>
<p>When a party wants to introduce scientific or technical evidence like brain scans, courts don&rsquo;t simply accept it at face value. After all, jurors likely don&rsquo;t have the expertise needed to make credibility determinations when it comes to neuroimaging. In 1993, the U.S. Supreme Court decided the criteria for expert testimony in a case called <em>Daubert v </em><em>Merrell Dow Pharmaceuticals, Inc.</em>. The <em>Daubert </em>Court noted that experts must testify to scientific knowledge that will assist a jury to better understand the facts.[5] If so, the scientific evidence must be reliable, as shown through testing, peer review and publication, potential rate of error, and general acceptance in the relevant scientific community.[6]</p>
<p>The <em>Daubert </em>court also referred to Federal Rule of Evidence 702 and 403.[7] Federal Rule of Evidence 702 requires that expert testimony be helpful to the jury, based on sufficient facts and data, properly tested with scientific methods, and appropriately applied to the case at hand.[8] Federal Rule of Evidence 403 allows evidence to be thrown out if it might mislead the jury, among other criteria such as wasting the jury&rsquo;s time.[9]</p>
<p>In 2012, the Sixth Circuit used the <em>Daubert </em>criteria in a case called <em>United States v. Semrau</em>. In <em>Semrau,</em> the defendant was a doctor who was charged with healthcare fraud and attempted to introduce functional Magnetic Resonance Image (fMRI) test results showing he was &ldquo;generally truthful&rdquo; when claiming he tried to follow proper billing practices in good faith.[10] An fMRI is a technique for measuring changes in blood oxygenation and flow in the brain, which occurs in response to neural activity.[11] However, the signal is nonspecific, since it&rsquo;s an average of millions of cells.[12] This means that it cannot easily differentiate between specific lobes of the brain, nor can it tell us exactly what a person is thinking.</p>
<p>Ultimately, the <em>Semrau </em>court decided to exclude this evidence due to reliability problems. One of the reasons was because the expert witness noted that fMRI lie detection had &ldquo;a huge false positive problem,&rdquo; where truth-tellers were incorrectly identified as liars 60-70% of the time.[13] A study in 2009 asked participants to commit a &ldquo;mock crime&rdquo; or stealing and damaging CDs, and reported that fMRI may have high sensitivity, but low specificity.[14] The study noted that this result meant an fMRI test may be helpful to &lsquo;&lsquo;rule out&rsquo;&rsquo; an innocent suspect, but not very helpful in &lsquo;&lsquo;ruling in&rsquo;&rsquo; a guilty suspect.[15]</p>
<h3><strong>Brain Scans to Prove Lack of Criminal Responsibility</strong></h3>
<p>In <em>Commonwealth v. Chism</em>, decided in 2025 by the Massachusetts Supreme Judicial Court, the defense of a 14-year-old brought in a structural MRI (sMRI) brain scan containing detailed images of his brain&rsquo;s anatomy.[16] The scans show volumetric abnormalities (differences in the size of certain brain structures) consistent with schizophrenia. When the defendant committed first-degree murder, aggravated rape, and armed robbery, his lawyer used brain scan evidence to argue that the 14-year-old couldn&rsquo;t understand right from wrong due to mental illness.[17]</p>
<p>The court relied on a 2014 multidisciplinary consensus report from Emory University, which concluded that &ldquo;the practice of performing imaging studies on a defendant in order to shed light on brain function or state of mind at the time of a prior criminal act is problematic.&rdquo;[18] The key reason is because a brain scans taken months or years after a crime occurred cannot tell us what was happening in the defendant&rsquo;s brain at the moment they committed the criminal act.[19] The court also noted methodological issues because the control group (the &ldquo;normal&rdquo; brains the defendant&rsquo;s scans were compared against) wasn&rsquo;t age-matched to the 14-year-old defendant, making the comparison scientifically questionable.[20]</p>
<h3><strong>What This Means for the Future</strong></h3>
<p>Does this mean neuroimaging evidence will never be admissible in criminal cases? Not necessarily. Courts seem to have left open the possibility that as science advances and gains broader acceptance, such evidence might meet admissibility standards in the future.</p>
<p>However, the timing issue remains. Criminal law asks whether a defendant had a particular mental state at a specific moment in the past, while neuroimaging shows us what a brain looks like now or how it responds to stimuli in a current testing situation. Bridging that temporal gap requires scientific advances that don&rsquo;t yet exist.</p>
<p>As neuroscience continues to advance, courts will likely continue to grapple with how and whether brain imaging should influence criminal responsibility. As legal scholar Francis Shen notes, the goal is not to wait for &ldquo;magical tools,&rdquo; but to adopt an entrepreneurial &ldquo;What now?&rdquo; mentality.[21] Perhaps the way forward is to define clear expert witness guidelines for what type of neuroimaging can be used in the courtroom, or to create better jury instructions that lead to a rightfully skeptical jury.</p>
<p>Understanding these issues will affect how we balance scientific advancement with legal protections, how we determine criminal responsibility, and ultimately, how we define what it means to have a &ldquo;guilty mind&rdquo; in an age where we can peer inside the brain itself.</p>
<h3><strong>References</strong></h3>
<p>[1] Uri Maoz &amp; Gideon Yaffe, <em>What Does Recent Neuroscience Tell Us About Criminal Responsibility?</em>, 3 J.L. &amp; Biosciences 120, 122 (2015).</p>
<p>[2] <em>Id.</em> at 122&ndash;23.</p>
<p>[3] <em>Id.</em> at 130.</p>
<p>[4] Neal Feigenson, <em>Brain Imaging and Courtroom Evidence: On the Admissibility and Persuasiveness of fMRI</em>, 2 Int&rsquo;l J. L. Context 233, 234 (2006).</p>
<p>[5] <em>Daubert v. Merrell Dow Pharms., Inc.</em>, 509 U.S. 579, 588 (1993).</p>
<p>[6] <em>Id.</em> at 593&ndash;95.</p>
<p>[7] <em>Daubert</em>, 509 U.S. 594-95.</p>
<p>[8] Fed. R. Evid. 702.</p>
<p>[9] Fed. R. Evid. 403.</p>
<p>[10] <em>United States v. Semrau</em>, 693 F.3d 510, 515 (2012).</p>
<p>[11] Nikos K. Logothetis, <em>What We Can Do and What We Cannot Do With fMRI</em>, 453 Nature 869, 869 (2008).</p>
<p>[12] <em>Id.</em> at 876.</p>
<p>[13] <em>Semrau</em>, 693 F.3d 518.</p>
<p>[14] F. Andrew Kozel et al., <em>Functional MRI Detection of Deception After Committing a Mock Sabotage Crime</em>, 54 J. Forensic Sci. 220, 228 (2009).</p>
<p>[15] <em>Id. </em></p>
<p>[16] <em>Commonwealth v. Chism</em>, 495 Mass. 358, 360, 370&ndash;71 (2025).</p>
<p>[17] <em>Id.</em></p>
<p>[18] <em>Id.</em> at 376&ndash;77.</p>
<p>[19] <em>Id.</em> at 376.</p>
<p>[20] <em>Id.</em></p>
<p>[21] Francis X. Shen, <em>Law and Neuroscience 2.0</em>, 48 Ariz. St. L.J. 1043, 1085 (2016).</p>]]></content>
	<updated>2026-02-13T19:49:16+00:00</updated>
	<author><name>Katherine Wu</name></author>
	<source>
		<id>https://law.stanford.edu/blog/lawandbiosciences/</id>
		<link rel="self" href="https://law.stanford.edu/blog/lawandbiosciences/"/>
		<updated>2026-02-13T19:49:16+00:00</updated>
		<title>Law and Biosciences Blog - Stanford Law School</title></source>

	<category term="criminal law"/>

	<category term="evidence"/>

	<category term="litigation"/>

	<category term="neuroimaging"/>

	<category term="neurolaw"/>

	<category term="neuroscience"/>


</entry>


</feed>
<!-- vim:ft=xml
	  -->